Deep Neural Networks, Backpropagation, Dropout, CNNs and Embeddings
In 1958, Frank Rosenblatt described the perceptron, an artificial neuron that learns to separate two classes with a linear boundary. Networks with several layers of such neurons can learn much more complex functions. In 1986, the paper Learning representations by back-propagating errors showed how to train them with gradient descent, by propagating the errors backwards from the output layer to the first one.
Deep Neural Networks (also known as Multi-Layer Perceptrons) are universal approximators, i.e. they can approximate any continuous function on a closed and bounded domain. They are the most important and relevant ML tool in the field of supervised learning, as they are part of the models used for most supervised tasks. This post covers their structure, the back propagation algorithm that trains them and its implementation with automatic differentiation, and then dropout, convolutional networks, skip connections and embeddings.
The structure of a basic NN is the following: one input layer of size \(D\), \(L\) hidden layers of size \(K\), and one output layer. It is a feedforward network: the computation performed by the network starts with the input from the left and flows to the right, with no feedback loop. It can be used for regression (when the output is a real value) and for classification (when the output is the class). The following picture illustrates a network with one hidden layer, where each node is connected to every node of the next layer, i.e. a fully connected network:
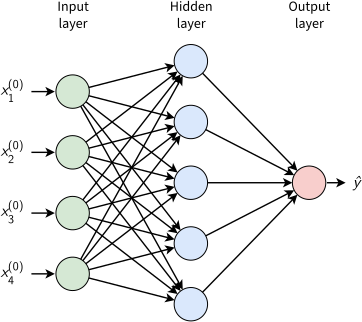
A fully connected feedforward network with an input layer of size \(D = 4\), one hidden layer of size \(K = 5\) and one output \(\hat{y}\). Adapted from: Machine Learning course CS-433 lecture notes, M. Jaggi, EPFL
Input and output layers work similarly to any previous regression method. Hidden layers are different. The output at node \(j\) in hidden layer \(l\) is given by:
\[x_j^{(l)} = \phi ( \sum_i w_{i,j}^{(l)} x_i^{(l-1)}+b_j^{(l)}).\]where \(b\) is the bias term, trained like any other weight. Note that, to compute the output, each neuron first computes the weighted sum of the inputs and then applies an activation function \(\phi\) to this sum. The activation function must be non-linear, otherwise the whole network would be equivalent to a single linear layer. The function implemented by each layer can equally be described in the form:
\[x^{(l)} = f^{(l)} (x^{(l-1)}) = \phi ((W^{(l)})^T x^{(l-1)}+b^{(l)})\]where \(f\) is the regression function of neurons, as previously. Some popular choices of activation functions are:
- sigmoid function: \(\phi(x) = \frac{1}{1+e^{-x}}\), positive and bounded;
- tanh: \(\phi(x) = \frac{e^x - e^{-x}}{e^x+e^{-x}}\), balanced (positive and negative) and bounded;
- Rectified Linear Unit – ReLU: \(\phi(x) = [x]_+ = max\{0,x\}\), always non-negative and unbounded; often used as it is computationally cheap and helps fight the issue of vanishing gradients in DNNs, as the positive output region does not have a small derivative;
- Leaky ReLU: \(\phi(x) = max \{\alpha x,x\}\), with \(0 < \alpha < 1\). Fixes the dying ReLU problem of non-leaky rectified linear units;
- In brief, if the dot product of the input to a ReLU with its weights is negative, the output is 0. The gradient of \(max\{ 0,x \}\) is \(0\) when the output is \(0\). If for any reason the output is consistently \(0\) (for example, if the ReLU has a large negative bias), then the gradient will be consistently 0. The error signal backpropagated from later layers gets multiplied by this 0, so no error signal ever passes to earlier layers. The ReLU has died. With leaky ReLUs, the gradient is never 0, and this problem is avoided.
In practice, ReLU and its variants are the default choice for hidden layers, while the sigmoid and tanh are used where a bounded output is needed, e.g. a probability at the output of a binary classifier.
Back-propagation
Similarly to previous regression use cases, the loss of the system needs to be minimized, using e.g. Stochastic Gradient Descent. As always with gradient descent, the algorithm computes the gradient of the cost function for a particular input sample (with respect to all weights and bias terms), and takes a small step in the direction opposite to this gradient. Computing the derivative with respect to a particular parameter is an application of the chain rule of calculus. The cost function over \(N\) samples can be written as (details omitted):
\[\mathcal{L} = \frac{1}{N} \sum_{n=1}^N ( y_n - f^{(L+1)} \circ ... \circ f^{(2)} \circ f^{(1)} (x_n^{(0)}) ) ^2\]Since in general there are many parameters, it would not be efficient to do this for each parameter individually. However, the back propagation algorithm does it more efficiently, as it computes the derivatives of all parameters with one forward and one backward pass through the network. The aim is to compute, for the loss \(\mathcal{L}_n\) of a sample \(n\):
\[\frac{\partial \mathcal{L}_n}{\partial w_{i,j}^{(l)}}, l=1, ..., L+1 \text {, and } \frac{\partial \mathcal{L}_n}{\partial b_{j}^{(l)}}, l=1, ..., L+1 \label{eq_gradient}\]For simplicity, the total input computed at the \(l\)-th layer, before the activation function, is represented as:
\[z^{(l)} = (W^{(l)})^T x^{(l-1)}+b^{(l)} . \label{eq_z}\]These quantities are easy to compute by a forward pass in the network, starting at \(x^{(0)} = x_n\) and then applying this recursion for \(l=1,...,L+1\).
Now, let
\[\delta_j^{(l)} = \frac{\partial \mathcal{L}_n}{\partial z_j^{(l)}}. \label{eq_delta}\]These quantities are easier to compute with a backward pass:
\[\begin{align*} \delta_j^{(l)} = & \frac{\partial \mathcal{L}_n}{\partial z_j^{(l)}} \\ = & \sum_k \frac{\partial \mathcal{L}_n}{\partial z_k^{(l+1)}} \frac{\partial z_k^{(l+1)}}{\partial z_j^{(l)}} \\ = & \sum_k \delta_k^{(l+1)} \frac{\partial \left[ (W^{(l+1)})^T x^{(l)}+b^{(l+1)} \right]_k}{\partial z_j^{(l)}} \\ = & \sum_k \delta_k^{(l+1)} W_{j,k}^{(l+1)} \frac{\partial x_j^{(l)}}{\partial z_j^{(l)}} \\ = & \sum_k \delta_k^{(l+1)} W_{j,k}^{(l+1)} \phi '(z_j^{(l)}) \end{align*}\]The chain rule is used in the second equality, and, in the fourth, the fact that \(x_j^{(l)}\) is the only entry of \(x^{(l)}\) that depends on \(z_j^{(l)}\). Going back to equation \ref{eq_gradient}:
\[\frac{\partial \mathcal{L}_n}{\partial w_{i,j}^{(l)}} = \sum_k \frac{\partial \mathcal{L}_n}{\partial z_k^{(l)}} \frac{\partial z_k^{(l)}}{\partial w_{i,j}^{(l)}} = \delta_j^{(l)} x_i^{(l-1)} \label{eq_w}\]Here, the derivation uses the chain rule, the definition of \(\delta\) in equation \ref{eq_delta}, and the partial derivative of equation \ref{eq_z} with respect to \(w\), which is zero for \(k \neq j\). In a similar manner:
\[\frac{\partial \mathcal{L}_n}{\partial b_{j}^{(l)}} = \sum_k \frac{\partial \mathcal{L}_n}{\partial z_k^{(l)}} \frac{\partial z_k^{(l)}}{\partial b_{j}^{(l)}} = \delta_j^{(l)} \cdot 1 = \delta_j^{(l)} \label{eq_b}\]The complete back propagation algorithm is then summarized as:
- Forward pass: set \(x^{(0)} = x_n\). Compute \(z^{(l)}\) for \(l=1,...,L+1\);
- Backward pass: set \(\delta ^{(L+1)}\) using the appropriate loss and activation function. Compute \(\delta ^{(l)}\) for \(l = L, ..., 1\);
- Final computation: for all parameters, compute \(\frac{\partial \mathcal{L}_n}{\partial w_{i,j}^{(l)}}\) (eq. \ref{eq_w}) and \(\frac{\partial \mathcal{L}_n}{\partial b_{j}^{(l)}}\) (eq. \ref{eq_b}).
Automatic Differentiation
The chain rule shows the theoretical framework, but not how to compute it efficiently. In practice, contrary to the back-propagation algorithm above, automatic differentiation (“autodiff”) algorithms such as PyTorch’s autograd do not require the derivatives of the loss and activation functions to be specified explicitly.
Instead, a computational graph (a DAG) is created dynamically, where nodes are added to the graph as the modules’ forward methods are called. The backward propagation is then computed by applying the chain rule to the derivatives (grad_fn) of the nodes in the computational graph. Recursive calls add new nodes to the graph for every call, and conditional calls may add different nodes at each forward pass; therefore, the computational graph cannot be extracted from the model definition directly (see an example here).
Finally, when tensor.backward() is called, it recursively computes the gradients up to the leaf nodes of the graph. When this process ends, the computational graph is discarded, and a new one may be created via a new forward call (unless retain_graph=True is set in the backward function). For more details, Chi-Feng Wang’s post gives an illustrative example of the automatic differentiation graph, and the Princeton course COS 324 on automatic differentiation a thorough explanation of the whole process.
Storing a computational graph is also useful for activation checkpointing, where one needs to recompute a module’s output during the backward pass, as it is discarded during the forward pass to save memory. A good example of activation checkpointing based on the reentrant and non-reentrant PyTorch implementations can be found in the post How Activation Checkpointing enables scaling up training deep learning models.
It also follows that inference requires less memory than training, as training requires the computational graph to save all activations. For completeness, very good step-by-step overviews of the back propagation theory applied to a real example can be found in Hooks for autograd saved tensors and PyTorch Autograd: Backpropagation.
Dropout
Dropout is a method that drops neurons (in different layers) with a given probability \(p\) at training time. For each training sample in a minibatch, a new network is sampled.
The outputs of the kept neurons are scaled by \(1/(1-p)\), so that their expected value is the same at training and inference time. At inference time, all neurons are used, and no dropout is applied. A simple code snippet to explain this is:
class MyDropout(nn.Module):
    def forward(self, X):
        if self.training:
            binomial = torch.distributions.binomial.Binomial(probs=1-self.p)
            return X * binomial.sample(X.size()) * (1.0/(1-self.p))
        return X
Dropout helps reduce overfitting, as the network learns to never rely on any given activation, so it learns redundant ways of solving the task with multiple neurons. It also leads to sparse activations, similar to a regularization (L1).
Dropout can be improved by adding max-norm regularization, a decaying learning rate and high momentum. Dropping 20% of input units and 50% of hidden units was often found to be optimal in the original publication. It is computationally less expensive than regular model averaging of multiple trained DNNs. However, it takes 2-3 times longer to train than a single fully-connected DNN, because it requires many more epochs, as parameter updates are very noisy.
Because a fully connected layer holds most of the parameters, it is prone to overfitting. Therefore, dropout increases model generalization. The following picture illustrates a standard network (left) and one of the thinned networks that dropout samples from it (right):
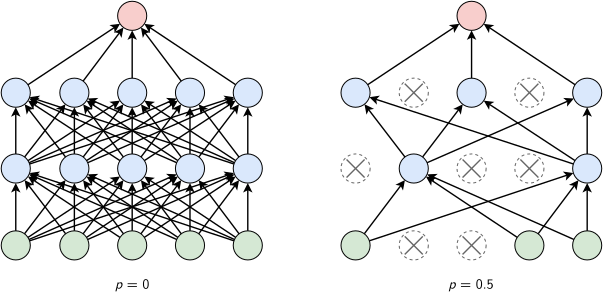
Dropout. Left: a standard network with two hidden layers (\(p = 0\)). Right: a thinned network produced by dropout with \(p = 0.5\), where \(p\) is the probability of dropping a unit: the crossed units are dropped, with their connections. Adapted from: Dropout: A Simple Way to Prevent Neural Networks from Overfitting
Convolutional Neural Networks
The disadvantage of large neural networks is that they have a very high number of parameters, so they may require lots of data to be trained. In some scenarios, local connectivity should suffice. For example, in an audio stream, it is natural to process an input stream \(x^{(0)}[n]\) by running it through a linear time-invariant filter, whose output \(x^{(1)}[n]\) is given by the convolution of the input \(x^{(0)}[n]\) and the filter \(h[n]\), as:
\[x^{(1)}[n] = \sum_u h[u]x^{(0)} [n-u]\]The filter \(h\) is local, i.e. \(h[u]=0\) for \(\vert u \vert \ge r\). By choosing an appropriate type of filter, one can bring out various aspects of the underlying signal, e.g. smooth features by averaging, or enhance differences between neighboring elements by using a high-pass filter. An analogous scenario applies to a picture:
\[x^{(1)}[n,m] = \sum_{u,v} h[u,v]x^{(0)} [n-u,m-v]\]The output \(x^{(1)}\) at position \([n, m]\) only depends on the values of the input \(x^{(0)}\) at positions close to \([n, m]\). So a fully connected network is no longer needed, but only one that represents the local structure, leading to fewer parameters to deal with.
This structure implies that the same filter (i.e., not only the same connection pattern but also the same weights) should be used at every position! This is called weight sharing, and it reduces the number of parameters even further. The difference between a locally/sparsely connected and a fully connected network is obvious:
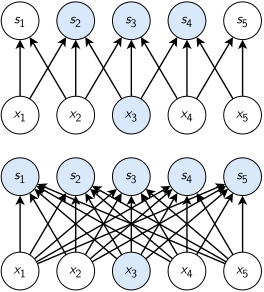
Sparse and full connectivity, viewed from below. Top: a locally connected layer with a kernel of width 3, where the input \(x_3\) affects only the outputs \(s_2\), \(s_3\) and \(s_4\). Bottom: a fully connected layer, where \(x_3\) affects every output. Adapted from: Deep Learning, I. Goodfellow, Y. Bengio and A. Courville, Figure 9.2
It is common to not only compute the output of a single filter but to use multiple filters. The various outputs are called channels. This introduces some additional parameters into the model.
With several channels, the result is not a 2D output in the next level, but in fact a 3D output. Layer after layer, there are increasingly more channels but a smaller “footprint”. In brief, applying local connectivity to a 2D input dataset on a deep neural network leads to the following final structure, a convolutional neural network (CNN):
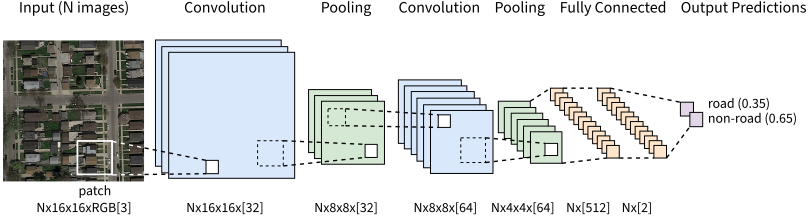
A CNN that classifies \(16 \times 16\) RGB patches of a satellite image as road or non-road: two stages of convolution and pooling, two fully connected layers, and the output probabilities of the two classes. Each label gives the shape of the data after a layer for \(N\) input images, with the number of channels or units in brackets.
Notice the three types of operations involved:
- convolutional layer: applies a convolution operation to the input, passing the result to the next layer. The convolution emulates the response of an individual neuron to visual stimuli;
- convolution is a mathematical operation on two functions that produces a third function, which expresses how the shape of one is modified by the other. Convolution is similar to cross-correlation;
- pooling: combines the outputs of neuron clusters at one layer into a single neuron in the next layer.
- A very common operation is max pooling, which uses the maximum value of each cluster of neurons at the prior layer;
- fully connected: similar to a multi-layer perceptron, providing the universal approximator function;
The size of each picture typically gets smaller and smaller as the data proceeds through the layers, either due to the handling of the boundary or because the network may perform subsampling.
Training is done with backpropagation, ignoring that some weights are shared and considering each weight on each edge to be an independent variable. Once the gradient has been computed for this network with independent weights, the gradients of all edges that share the same weight are summed up. This gives the gradient for the network with weight sharing, as the loss depends on the shared weight through each of these edges.
Skip connections
An issue with very deep networks is that the performance of the model drops as the depth of the architecture increases. This is known as the degradation problem. It is not caused by overfitting, since the training error increases as well.
Possible reasons are vanishing and/or exploding gradients. One way to improve this is to use normalization techniques to ensure that gradients have healthy norms. However, the authors of ResNet observed the degradation problem even with normalization layers and healthy gradient norms.
A better way to improve this is to provide layers of the network with the outputs of layers that are not directly connected to them. These connections skip some of the layers in the neural network and feed the output of one layer as the input of later layers, hence the name skip connections. In practice, the input to a given layer is the combination (typically via addition or concatenation) of the outputs of several previous layers.
With an addition, as in ResNet, the skipped layers only need to learn a correction (a residual) to their input, which is easier to optimize than the whole mapping. With a concatenation, as in DenseNet, each layer receives the feature maps of all the layers before it, so the number of channels grows with every layer. The following picture illustrates a dense block of DenseNet:
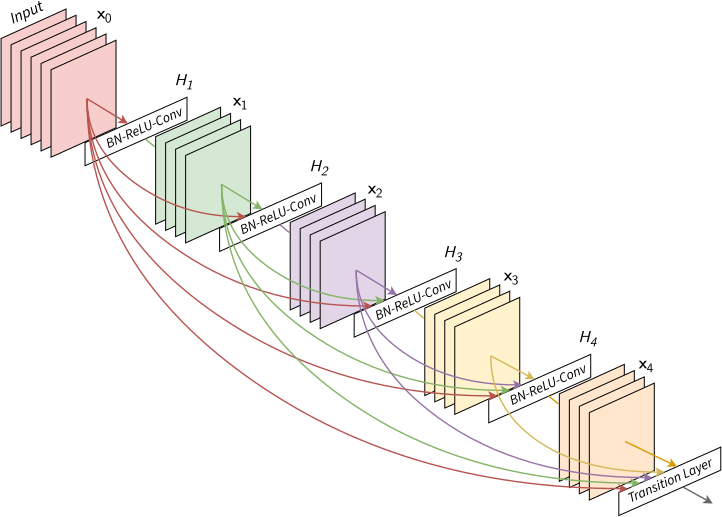
A 5-layer dense block of DenseNet with a growth rate of \(k = 4\): each layer \(H_i\) (BN-ReLU-Conv) takes the feature maps \(x_0, \ldots, x_{i-1}\) of all preceding layers as input and produces \(k\) new feature maps \(x_i\). The transition layer takes all of them. Adapted from: Densely Connected Convolutional Networks
There is currently a plethora of different implementations of CNNs with several layouts of skip connections. To know more, the curious reader can have a look at ResNet, DenseNet and U-net.
Embeddings
Embeddings in machine learning are dense, low-dimensional vector representations of data (e.g., words, images, or users) that capture their semantic or contextual meaning in a continuous vector space. Embeddings can be collected by passing input data (e.g., text, images) through a trained machine learning model (e.g., a neural network) and extracting the values from a specific intermediate layer, typically before the final output layer.
A list of the most common data types and embedding types:
- words: Word2vec (skipgram or continuous bag of words), whose inputs are one-hot vectors of the words
- skipgram: slower to train (“3 days” in the original paper), better at capturing semantic relationships, e.g. for ‘cat’ it returns ‘dog’ as a word with close embeddings;
- CBOW: faster to train (“1 day” on the same data), better at capturing syntactic relationships between words, e.g. for ‘cat’ it returns ‘cats’;
- text (word sequences): BERT
- non-textual sequences: Encoder-Decoders, e.g. LSTMs, RNNs
- point cluster or array: Principal Component Analysis
- images:
- in a classification task: the activation of the last layer before the layer that does logit/softmax, i.e. the input to the final layer, which is the output of the one before last;
- in an image-to-image task, e.g. segmentation using a U-net: the activation of the last downsampling layer, which is the input of the first upsampling layer, i.e. the bottleneck of the network;
- audio: a waveform is a long 1D sequence of samples (typically 16-bit integers at 16 to 48 kHz), too long to model directly, so it is first turned into a shorter sequence of frames:
- spectrograms: the waveform is converted into a log-Mel spectrogram, a 2D time-frequency image, and fed to a CNN or Transformer encoder whose activations are the embeddings. E.g. Whisper resamples audio to 16 kHz and computes 80 Mel channels on 25 ms windows with a 10 ms stride. A vocoder turns a spectrogram back into a waveform, as in the text-to-speech model TorToise;
- neural audio codecs: a convolutional encoder downsamples the waveform into embeddings, and a decoder with transposed convolutions reconstructs it. In between, residual vector quantization (RVQ) turns each embedding into discrete tokens: the embedding is replaced by its nearest entry in a codebook, the residual is quantized with a second codebook, and so on. E.g. EnCodec turns 24 kHz audio into 75 embeddings per second, a 320-fold reduction, and the number of codebooks sets the bitrate (8 codebooks of 1024 entries give 6 kbps), while DAC compresses 44.1 kHz audio into 8 kbps of tokens. These tokens can be modeled like text, e.g. VALL-E does text-to-speech by predicting EnCodec tokens with a language model;
- videos: the input is now 5D (batch size, time, channels, height, width), i.e. a sequence of video frames stacked on the time dimension. Embeddings are collected similarly to a regular CNN (adapted to use 3D instead of 2D convolutions, etc.);
-
graphs: the embedding of a node is given by its state after several steps of the message passing algorithm, and the embedding of a graph by a readout (e.g. sum, mean or max) over all node embeddings. A message passing step is given by:
\[x_i^{(k)} = \gamma^{(k)} \left( x_i^{(k-1)}, \Box_{j \in \mathcal{N}(i)} \, \psi^{(k)} \left( x_i^{(k-1)}, x_j^{(k-1)}, e_{j,i} \right) \right)\]where:
- \(x_i^{(k)}\) is the embedding of node \(i\) at message passing step \(k\);
- \(\mathcal{N}(i)\) is the set of neighbors of node \(i\);
- \(e_{j,i}\) is the embedding of the edge from node \(j\) to node \(i\);
- \(\Box\) is a differentiable, permutation-invariant function, e.g. sum, mean or max;
- and \(\gamma\) and \(\psi\) are differentiable functions such as DNNs or RNNs (LSTMs, GRUs).
To find more about the topic, the Deep Learning book by Goodfellow, Bengio and Courville covers feedforward networks and back propagation (chapter 6), regularization and dropout (chapter 7) and convolutional networks (chapter 9).