Distributed Matrix Transpose Algorithms
The transpose of a matrix (or, equivalently, of the connectivity matrix of a graph) is trivial on a single compute node, but becomes a hard task when the matrix is distributed, as the edges that reach a vertex may start on any node. The following sections introduce an efficient method to transpose a distributed sparse matrix, including matrices with several values per cell. The method is implemented with the Message Passing Interface (MPI).
The basics
A graph \(G = (V, E)\) is a data structure consisting of a set of nodes or vertices \(V\), and a set of inter-node connections or edges \(E\). An edge \((i,j,e)\) in \(E\), with \(i,j \in \mathbb{N}\) and \(e \in T\), represents a connection between vertices \(i\) and \(j\) in \(V\) with edge information of type \(T\). It can be either ordered or unordered, depending on whether the graph is directed or undirected.
A matrix \(M\) represents the connectivity \(E\) in \(G\), iff for all \((i,j,e) \in E\), if \(G\) is directed then \(M_{ij}=e\), and if it is undirected then \(M_{ij} = M_{ji} = e\). Since \(M\) holds the possible connectivity between nodes in \(V\), \(M\) is a square matrix of size \(\vert V \vert \times \vert V \vert\), also known as the adjacency matrix of the graph. The cells of the pairs of vertices without an edge are empty.
When a matrix is stored in a single compute node, the transpose is easy and follows the mathematical definition: the transpose of a matrix \(M\) is given by \((M^T)_{ij} = M_{ji}\). It swaps the row and column placement of the cells of the initial matrix. The graph whose connectivity is described by the matrix \(M^T\) can then be described by \(G^{\star} = (V, E^{\star})\), where \(E^{\star} = \{ (j,i,e) : (i,j,e) \in E \}\) holds the reversed edges. For an undirected graph, \(M\) is symmetric and equal to its transpose, so the rest of this post considers directed graphs.
A distributed memory data layout assumes that the vertices \(V\) are distributed across \(R\) compute nodes (ranks, numbered from 0) and that only the rows local to each memory region are directly accessible to a rank. Let \(G_{r} = (V_{r}, E_{r})\) be the subset of \(G\) that is stored in rank \(r\), with vertices \(V_{r}\) and edges \(E_{r}\).
Each rank holds a disjoint range of consecutive rows of the initial graph \(G\) (a 1D partitioning of the matrix by rows), such that the cover (\(\bigcup\limits_{r} G_{r} = G\)) and disjoint (\(G_{r} \cap G_{s} = \emptyset, \forall r \neq s\)) properties hold. Ranks only hold information about outgoing connectivity (edges from vertices in this rank to other vertices), i.e. \(E_{r} = \{ (i,j,e) \in E : i \in V_r \}\). Thus, the same cover and disjoint properties also hold for edges, and the rows \(V_r\) of \(M\) form the block \(M_r\) of rank \(r\), of size \(\vert V_r \vert \times \vert V \vert\).
Given a dense matrix representation of a graph connectivity \(E\), the algorithm to compute \(G^{\star}_{r} = (V_{r}, E^{\star}_{r})\) for every rank \(r\) requires only the computation of the block \((M^{T})_{r}\) of the rows \(V_r\) of \(M^T\), for the connectivity \(E^{\star}_{r}\). Note that the vertex information is local to a compute node and stays in the same memory location after the transpose, so \(V\) is the same for \(G\) and \(G^{\star}\).
The implementation of the distributed transpose of a dense connectivity matrix is well known: the MPI_Alltoall collective call, in which each rank sends a different block of its array to every rank. If each rank holds one row of the matrix, the all-to-all is the transpose itself; if it holds several rows, each block is also transposed locally. The following picture illustrates the all-to-all, with the buffer of each process in a row, before (left) and after (right) the exchange:
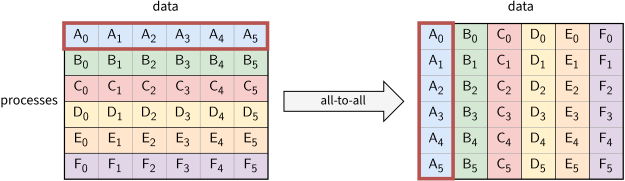
MPI_Alltoall on 6 processes: block \(j\) of process \(i\) goes to process \(j\), as its block \(i\). The blocks of process A (red frame) become the first block of every process.
For sparse matrices, the problem is not so trivial. Most cells are empty, so each rank stores only its nonempty cells, each with its column id. The number of cells that a rank sends to each other rank then depends on the data: no rank knows in advance how many cells it receives, nor where they go in its rows, so the cells are sent with their row and column ids.
A common format for the distributed storage of a sparse matrix is the Compressed Sparse Row (CSR) format. Each submatrix stored on a compute node is represented (serialized) as three arrays, holding (1) the number of populated columns per row (counts in the picture), (2) the id of each populated column (disps), and (3) their respective values (cells). Note that the standard CSR stores the offset of each row instead of its number of populated columns. For clarity, the following picture illustrates a sample graph with vertices 0-5 and 12 edges labeled A-T, its representative sparse matrix, and the CSR data structure on 3 ranks:
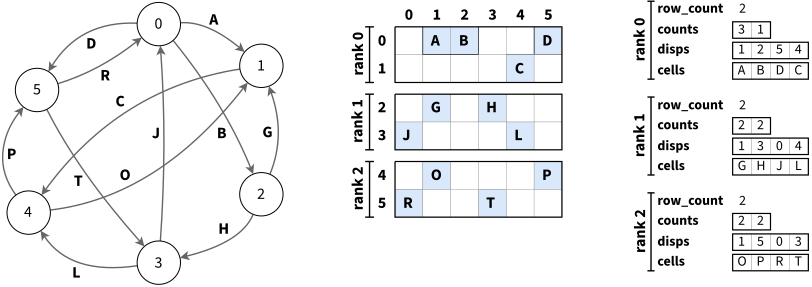
How to transpose it?
After the transpose, rank \(r\) must hold the rows \(V_r\) of \(M^T\), i.e. the columns \(V_r\) of \(M\), which have cells on every rank. A small mental trick to understand this is to notice that a sparse matrix transpose is nothing more than a composition of two operations: a local matrix transpose and a view swap. The local transpose transposes the block of each rank in its own memory, with no communication. The view swap keeps the matrix as it is but changes the part that each rank holds, from the rows \(V_r\) to the columns \(V_r\), and performs all the communication. These two operations describe a distributed sparse matrix in four different data layouts, illustrated below:
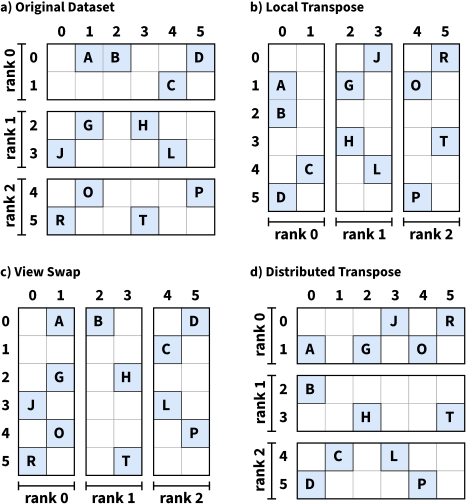
A local transpose of the original dataset (a) yields layout (b), a view swap yields layout (c), and both operations together yield the distributed transpose (d), whichever comes first: a view swap of (b) and a local transpose of (c) both lead to (d).
The formulation of the solution starts with the mathematical formalism underlying the distributed matrix transpose operations, with rows and columns indexed from 0, as in the pictures. A horizontal concatenation of two matrices \(M_{n \times m}\) and \(N_{n \times m'}\) is represented by \(M \| N\) and defined as the operation that joins two sub-matrices horizontally into a matrix of dimensionality \({n \times (m+m')}\), such that:
\[(M \| N)_{i j} =\left\{ \begin{array}{@{}ll@{}} M_{i \,\, j} & \text{, if } j < m\\ N_{i \,\, j-m} & \text{, otherwise} \end{array}\right.\]Analogously, a vertical concatenation \(M_{n \times m} // N_{n' \times m}\) joins two sub-matrices vertically into a matrix of dimensionality \({(n+n') \times m}\), such that:
\[(M // N)_{i j} =\left\{ \begin{array}{@{}ll@{}} M_{i \,\, j} & \text{, if } i < n\\ N_{i-n \,\, j} & \text{, otherwise} \end{array}\right.\]A view refers to the perspective of data storage. The row view describes the matrix as the vertical concatenation of the subsets of rows stored on each rank, the blocks \(M_r\): \(M = M_0 // M_1 // ... // M_{R-1}\). The column view describes it as the horizontal concatenation of the subsets of columns stored on each rank, \(M = \tilde{M}_0 \| \tilde{M}_1 \| ... \| \tilde{M}_{R-1}\), where the block \(\tilde{M}_r\), of size \(\vert V \vert \times \vert V_r \vert\), holds the columns \(V_r\) of \(M\). It follows that \((M \| N)^T = M^T // N^T\) and \((M // N)^T = M^T \| N^T\), as both concatenations provide the same dataset described by two alternative views, and the transpose of a concatenated dataset yields the orthogonally concatenated dataset.
The local transpose of a matrix \(M\) represented by the concatenation of \(R\) submatrices in either view is defined as the concatenation of the transposes of the individual matrices in the orthogonal view:
\[\mathrm{LocalTranspose}(M)_{i j} =\left\{ \begin{array}{@{}ll@{}} \big( M^T_0 \| M^T_1 \| ... \| M^T_{R-1} \big)_{i j}& \text{, if } M \text{ is in row view }\\ \big( \tilde{M}^T_0 // \tilde{M}^T_1 // ... // \tilde{M}^T_{R-1} \big)_{i j}& \text{, otherwise} \end{array}\right.\]Note that the operation yields a transposed version of the original rank matrices that formed the initial dataset, so no communication between ranks is necessary, as the data \(M_r\) of every rank is locally transposed into \(M^T_r = (M_r)^T\). This block holds the columns \(V_r\) of \(M^T\); it is not the block \((M^T)_r\) of its rows \(V_r\). In the CSR format, the local transpose reorders the cells of each rank by column id, then by row id. Moreover, it is an involutory function, as \((\mathrm{LocalTranspose} \circ \mathrm{LocalTranspose})(M) = M\), where \(\circ\) is the composition of functions, which applies the right function first.
The view swap of a distributed matrix, which alternates between a data representation in one view and its orthogonal one (from row- to column-accessible and vice versa) while maintaining the same matrix contents, is defined by:
\[\mathrm{ViewSwap}(M)_{i j} =\left\{ \begin{array}{@{}ll@{}} \big( \tilde{M}_0 \| \tilde{M}_1 \| ... \| \tilde{M}_{R-1} \big)_{i j}& \text{, if } M \text{ is in row view}\\ \big( M_0 // M_1 // ... // M_{R-1} \big)_{i j}& \text{, otherwise} \end{array}\right.\]Unlike the local transpose, the view swap needs communication: the block \(\tilde{M}_r\) holds the columns \(V_r\) of all the rows, and so cells of every rank, as layout (c) shows. Moreover, the view swap is also an involutory function, as two consecutive view swaps yield the initial dataset.
Algorithmic verification
Is this algorithm guaranteed to work regardless of the dataset? The proof below shows that it is indeed mathematically sound.
The distributed sparse transpose is defined as the composition of the local transpose and view swap methods. Both methods take a distributed matrix in the CSR format and yield one in the CSR format: the local transpose reorders the cells of each rank, and the view swap sends them to their new ranks, as the next section shows. It remains to show that the distributed sparse transpose is also mathematically sound, i.e. that it yields the transpose of any matrix.
Take a matrix \(M\) in row view, represented by the vertical concatenation of partial matrices \(M_0 // M_1 // ... // M_{R-1}\). A local transpose of \(M\) leads to \(M^T_0 \| M^T_1 \| ... \| M^T_{R-1}\), which is \(M^T\) in column view, as the transpose of a vertical concatenation is the horizontal concatenation of the transposes. Applying a view swap yields \((M^T)_0 // (M^T)_1 // ... // (M^T)_{R-1}\), with the rows \(V_r\) of \(M^T\) on each rank \(r\), which is the definition of the distributed transpose of \(M\) in the original view. In brief, it follows that \(\mathrm{Transpose}(M) = (\mathrm{ViewSwap} \circ \mathrm{LocalTranspose})(M)\).
The verification with the commuted functions, \(\mathrm{Transpose}(M) = (\mathrm{LocalTranspose} \circ \mathrm{ViewSwap})(M)\), also holds: a view swap over the original dataset leads to \(\tilde{M}_0 \| \tilde{M}_1 \| ... \| \tilde{M}_{R-1}\), and a subsequent local transpose yields the final result \(\tilde{M}^T_0 // \tilde{M}^T_1 // ... // \tilde{M}^T_{R-1}\). This is the same matrix, as the transpose \(\tilde{M}^T_r\) of the columns \(V_r\) of \(M\) is the block \((M^T)_r\) of the rows \(V_r\) of \(M^T\).
As \(\mathrm{Transpose}\) is a composition of two involutory functions, and because both functions commute, i.e. \(\mathrm{ViewSwap} \circ \mathrm{LocalTranspose} = \mathrm{LocalTranspose} \circ \mathrm{ViewSwap}\), \(\mathrm{Transpose}\) is also involutory. Two transposes in a row swap the two functions in the middle, and then each function cancels itself:
\[\begin{aligned} \mathrm{Transpose} \circ \mathrm{Transpose} &= \mathrm{ViewSwap} \circ (\mathrm{LocalTranspose} \circ \mathrm{ViewSwap}) \circ \mathrm{LocalTranspose} \\ &= (\mathrm{ViewSwap} \circ \mathrm{ViewSwap}) \circ (\mathrm{LocalTranspose} \circ \mathrm{LocalTranspose}), \end{aligned}\]which is the identity, as both compositions in parentheses are.
The view swap in MPI
At the level of a rank, the matrix data layout after a view swap is unknown until the swap is performed, as ranks do not hold information about the matrix structure across other ranks. Therefore, a communication step (MPI_Allgather) must be executed beforehand to gather the number of rows held by individual ranks and compute the row interval of every rank \(r\) as:
where \(\vert V_s \vert\) is the number of rows of rank \(s\). The start of each interval is the prefix sum of the row counts of the previous ranks (an exclusive scan).
This information is required to match each column/row id to its target rank in the sparse transpose steps that follow: the cells of column 4, for instance, go to rank 2, whose interval \([4, 6)\) holds the row 4 of \(M^T\). The view swap algorithm then follows in two communication steps.
The first step performs a dense matrix transpose (MPI_Alltoall) to send/receive the number of elements to/from other ranks. The second step performs a selective scatter-gather (MPI_Alltoallv) that delivers the elements to the final rank. Both steps follow the local transpose, which sorts the elements of each rank by column id, so that the elements for each destination rank form one contiguous segment of the send buffer. The following picture illustrates both steps on the sample matrix above: the transpose of the element counts (left), and the exchange of the elements with their row and column ids (right):
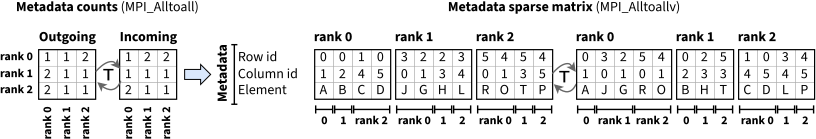
A memory realignment based on column id and row id leads to the final distributed matrix dataset, as in layout (d).
The full transpose algorithm performs only three collective communication calls: an MPI_Allgather to compute the row offsets of ranks, and one MPI_Alltoall and one MPI_Alltoallv to transpose the element counts and the cell values in the view swap. The first two calls move \(R\) integers per rank, and the MPI_Allgather can run once, at the onset of execution, as the rows of each rank do not change. The MPI_Alltoallv sends every element with its row and column ids, so it carries most of the data. Moreover, the involutory property of this transpose method is of high importance, as it guarantees that the distributed transpose can be validly executed any number of times while respecting the data integrity of a CSR-based graph problem representation.
Higher Cardinality Matrices
Having a single edge between each pair of nodes is often not the case in real-life situations, which then require multigraphs. Take as an example the matrix representing information about common interests between pairs of users in a social network: some pairs of users may be connected by hundreds of common interests, while others may have barely any interests in common. Another example is a URL cross-referral map, where one may be required to store not only the number of hyperlinks between pages, but also additional information about every link. Each cell of such a matrix holds a list of values, whose number, the cardinality of the cell, differs from cell to cell: these are high-cardinality matrices. How to implement the transpose in this case?
The solution starts by defining a data format that can hold high-cardinality cells. It is called the extended CSR, or XCSR for short, and is defined as the previous CSR data structure with an added dimension that holds the number of values per matrix cell (or edges between pairs of nodes), cell_counts in the picture. The layout is as follows:
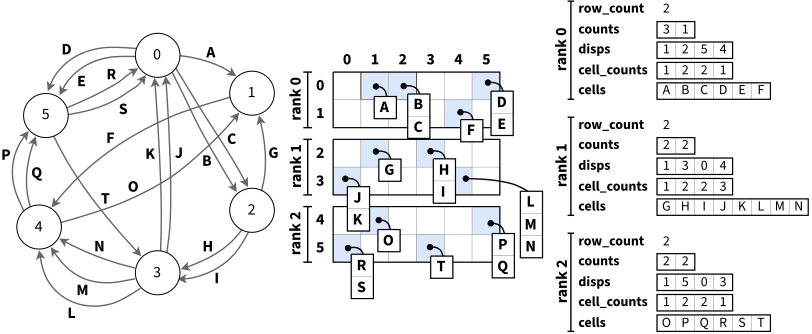
The transpose algorithm then follows in three steps. First, each compute node (rank) collects the metadata of its own sub-matrix, composed of the set of triplets of the form [row id, column id, number of values], indicating the row, column and cardinality of each cell. Then the ranks perform a local transpose of their own data, by reordering their triplets by column and row id. This sequence illustrates the first step:
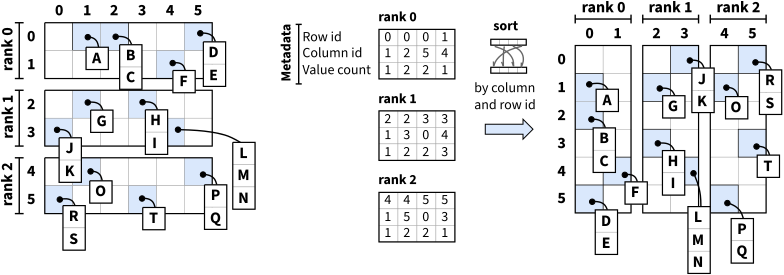
The second step starts the view swap method. All ranks pack their triplets and exchange them (i.e. an all-to-all communication), sending each triplet to the recipient of its cell in the final transposed matrix. In practice, the previous local transpose operation already sorted each sub-matrix by columns (i.e. by rows of the final transposed dataset), so the triplets are already grouped by destination rank.
More importantly, the matrix composed of all triplets across all ranks is a distributed matrix with a fixed element size per cell (a tuple of fixed size). Therefore, this exchange is performed by the same view swap as the CSR matrix, presented in the section The view swap in MPI, with the triplets as elements. As the two matrices have the same cells, the counts are also the same. After the exchange, all ranks will hold the triplets of the metadata (but not the data yet) of the final matrix structure:
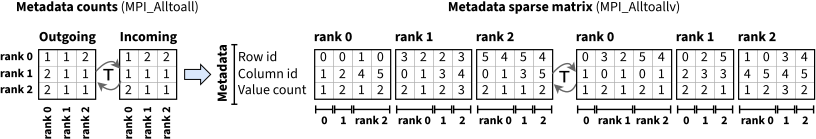
Finally, the view swap is completed by communicating the data, based on the metadata of the transposed matrix. First, each rank counts the number of values to be sent to each rank. The matrix of distributed counts of all values to be sent and received per rank is a dense matrix that can be transposed easily (MPI_Alltoall).
These counts are then used to allocate the buffers for the incoming data and to perform an MPI_Alltoallv that sends/delivers the values of the final matrix across all compute nodes. Upon completion, the (previously column-oriented) values are sorted by row and column, which yields the final dataset:
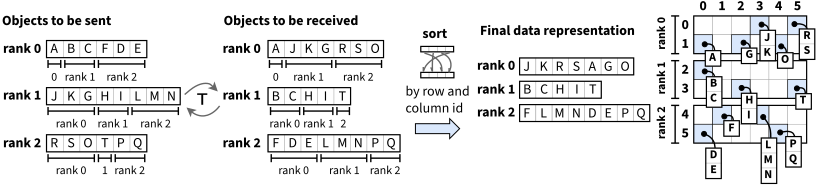
The triplets received in the second step give the cell and the cardinality of each group of values, so that each rank sorts its values by row and column id.
To sum up, the full transpose algorithm requires five collective communication calls: an MPI_Allgather to compute the row offsets of ranks, and two MPI_Alltoall and two MPI_Alltoallv for the metadata and cell values transpose. These are two calls more than for a CSR matrix, as the metadata and the values are exchanged separately, so the CSR transpose is preferred for matrices with a single value per cell. The same holds when every cell has the same number of values, as a cell can then be sent as one element of fixed size (an MPI derived datatype).
For more details, implementation and benchmark information, the original publication (preprint) and the source code are available for download.