Faster attention (GQA, FlashAttention, sparse, linear and latent attention)
In 2017, the Transformer model was presented in the paper Attention Is All You Need. Its attention mechanism lets each token gather information from the other tokens of the sequence, and it is the only part of a Transformer whose cost per token grows with the context length. This post covers the methods that make attention faster, from better kernels to new attention architectures, and implements several of them in PyTorch.
The scaled dot-product attention of a head is computed as:
\[\text{Attention}(Q, K, V) = \text{softmax}\left( \frac{QK^T}{\sqrt{h}} \right) V\]where \(Q\), \(K\) and \(V\) are the queries, keys and values of the head, \(h\) is the head size, and the softmax turns each row of scores into weights that sum to one. The following picture illustrates this computation for \(S_q\) queries and \(S_k\) keys, with the names used in the code below:
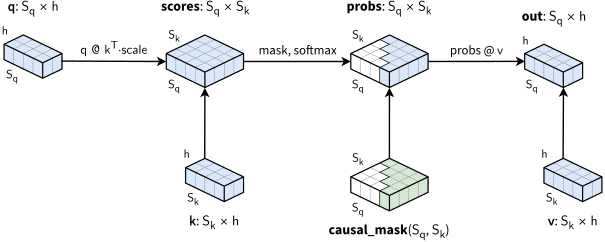
The following code implements this attention. The function scaled_dot_product_attention takes an optional mask of the keys that each query can see, and causal_mask builds the mask of a decoder, where each token sees only itself and the previous tokens. Most modules of this post reuse both functions:
def scaled_dot_product_attention(q, k, v, mask=None, scale=None):
    """ softmax(q @ k^T * scale) @ v, for the queries q: [B, H, Sq, h], and the keys k and values v: [B, H, Sk, h]
        (or [B, 1, Sk, h], shared by all heads). mask: [Sq, Sk] or [B, Sq, Sk], True (or nonzero) where a query
        can attend to a key. The scale is 1/sqrt(h) by default """
    scale = q.size(-1) ** -0.5 if scale is None else scale

    # attention scores: [B, H, Sq, h] @ [B, H, h, Sk] -> [B, H, Sq, Sk]
    scores = q @ k.transpose(-1, -2) * scale  # @ is torch.matmul; torch.dot only takes 1D tensors

    if mask is not None:
        if mask.dim() == 2:    # [Sq, Sk] -> [1, 1, Sq, Sk]
            mask = mask[None, None, :, :]
        elif mask.dim() == 3:  # [B, Sq, Sk] -> [B, 1, Sq, Sk]
            mask = mask[:, None, :, :]
        if mask.dtype != torch.bool:
            mask = mask != 0
        # A masked score must get a softmax weight of 0, and e^x is 0 only when x is -inf. Multiplying the scores by
        # the mask would turn the masked scores into 0, which still get a weight e^0 / sum. -inf works when a query
        # can attend to at least one key, but a row of -inf gives NaN, as the softmax subtracts the row maximum and
        # -inf - (-inf) = NaN. The smallest float avoids it, and unlike a constant such as -1e9, it fits in float16
        scores = scores.masked_fill(~mask, torch.finfo(scores.dtype).min)

    probs = F.softmax(scores, dim=-1)  # [B, H, Sq, Sk]
    return probs @ v                   # [B, H, Sq, Sk] @ [B, H, Sk, h] -> [B, H, Sq, h]


def causal_mask(Sq, Sk, device=None):
    """ Causal mask of the last Sq of Sk tokens: [Sq, Sk], True where query i can attend to a key, i.e. up to its
        own position Sk - Sq + i. Without a KV cache, Sq == Sk. With a KV cache of P past tokens, Sk = P + Sq, and
        the Sq new tokens see all the past tokens and the new ones up to themselves """
    return torch.ones(Sq, Sk, dtype=torch.bool, device=device).tril(diagonal=Sk - Sq)
During prefill, \(QK^T\) compares every token of the prompt with every previous token, so the compute grows quadratically with the prompt length \(S\), and a naive implementation stores an \(S \times S\) matrix of scores per head. During decode, every new token reads the keys and values of the whole context from the KV cache, described in the post on prefill, decode and the KV cache, so the cost of each step grows linearly with the context.
A Transformer layer of width \(E\) holds about \(12E^2\) weights (\(4E^2\) in the attention projections and \(8E^2\) in an MLP with a hidden size of \(4E\)), and each weight costs 2 FLOPs per token, i.e. \(24E^2\) FLOPs in total. Attending to \(S\) tokens costs \(4SE\) FLOPs per token, as \(QK^T\) and the product with \(V\) take \(2SE\) FLOPs each. So attention costs more than the rest of the layer once the context is longer than \(6E\) tokens, e.g. 24,576 tokens for \(E = 4096\).
In practice, the authors of Native Sparse Attention (below) estimated that attention accounts for 70-80% of the latency when decoding with a 64K-token context. Long documents, long conversations, agents and reasoning models with long chains of thought all live in this regime.
There are three families of solutions, which can be combined:
- compute the full attention faster, with better kernels (FlashAttention, FlashDecoding) and lower precision (SageAttention);
- store fewer keys and values, by sharing or compressing them (MQA, GQA and MLA);
- compute less attention, by attending only to the most relevant tokens (sparse attention), or by replacing softmax attention with a linear-time alternative (linear attention and hybrid models).
Prefill processes all the tokens of the prompt at once and is limited by compute, so it benefits most from faster kernels (FlashAttention and SageAttention). Decode processes one token at a time and is limited by memory bandwidth, so it benefits most from storing and reading fewer keys and values (MQA, GQA, MLA and KV eviction). It also benefits from kernels that spread the reading of a long KV cache over the whole GPU (FlashDecoding). Sparse attention, linear attention and hybrid models help both phases, and the summary table at the end of the post lists where each method helps most.
Multi-Head (MHA), Multi-Query (MQA) and Grouped-Query Attention (GQA)
Decode reads the whole KV cache at every step, so a smaller KV cache means faster decoding, and leaves room for larger batches and longer contexts.
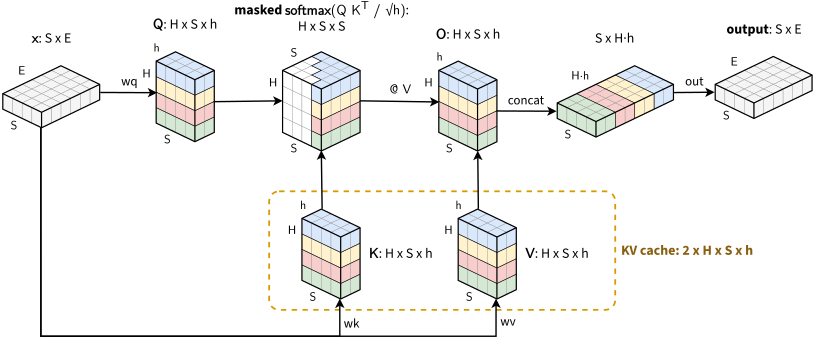
Multi-Head Attention (MHA), the attention of the original Transformer, keeps one query, one key and one value per head. The following picture illustrates it with \(H = 4\) heads, one color per head, where the keys and values of all heads form the KV cache:
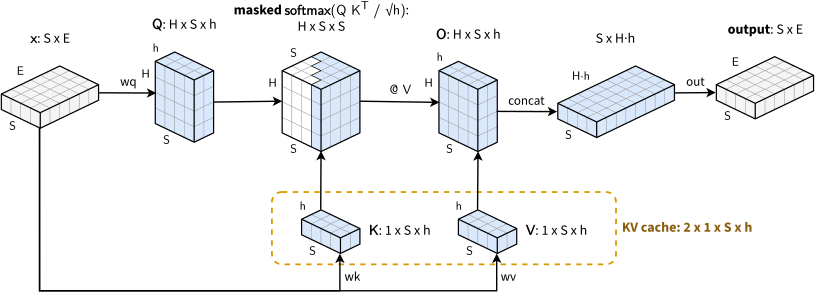
In 2019, Noam Shazeer proposed Multi-Query Attention (MQA), which keeps one query per head, but all heads share a single key head and a single value head. The KV cache shrinks by a factor equal to the number of heads, at some cost in quality. The following picture shows the same example with MQA:
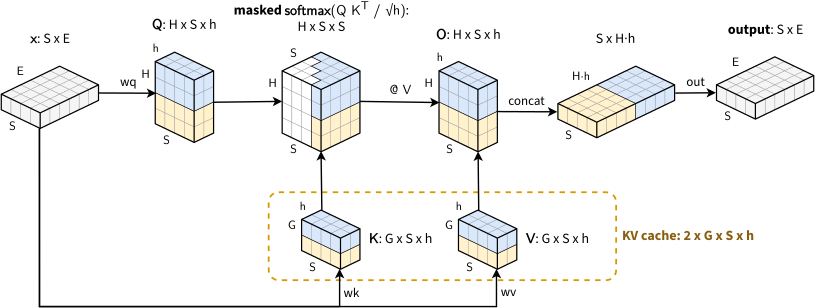
Grouped-Query Attention (GQA), proposed in 2023, is the middle ground, with a quality close to MHA and a speed close to MQA, and most current models use it. The \(H\) heads are split into \(G\) groups, and the heads of a group share one key head and one value head, so the cache shrinks by a factor \(H / G\). Thus, GQA becomes MHA when \(G = H\), and MQA when \(G = 1\). The following picture illustrates GQA with \(H = 4\) heads in \(G = 2\) groups, one color per group:
A trained MHA model can be converted to GQA by averaging (mean pooling) the key and value heads of each group, followed by a short uptraining with about 5% of the original pre-training compute. Note that the savings of MQA and GQA appear only when there is a KV cache to read during decode: without a cache, GQA only saves a little compute in the key and value projections.
The following code implements GQA with an optional KV cache; it is also MHA with num_groups = num_heads, and MQA with num_groups = 1. First, the module projects the input into \(H\) query heads and \(G\) key and value heads. Then, it appends the keys and values of the new tokens to the cache, which therefore holds \(G\) heads instead of \(H\). Finally, it repeats each key and value head for the \(H / G\) query heads of its group, and computes the attention.
During decode, the module receives only the new tokens, and the model must give them the positions that follow the cached ones. MLA and DSA, below, follow the same convention: an optional kv_cache argument, and the new cache returned with the output:
class GQA(nn.Module):
    """ Grouped-Query Attention: the H = num_heads query heads are split in G = num_groups groups, and the heads of
        a group share the same key and value. GQA is MHA when num_groups == num_heads, and MQA when num_groups == 1.
        For a prompt x: [B, S, E], followed by one new token x_new: [B, 1, E] at a time:
            out, kv_cache = gqa(x, causal_mask(S, S))      # prefill: kv_cache holds the prompt's keys and values
            out, kv_cache = gqa(x_new, kv_cache=kv_cache)  # decode: x_new attends to the cached tokens and itself """

    def __init__(self, input_dim, head_dim, num_heads=8, num_groups=2):
        super().__init__()
        assert num_heads % num_groups == 0, "the number of heads must be a multiple of the number of groups"
        self.head_dim = head_dim
        self.num_heads = num_heads
        self.num_groups = num_groups
        self.wq = nn.Linear(input_dim, head_dim * num_heads)   # one query per head
        self.wk = nn.Linear(input_dim, head_dim * num_groups)  # one key per group
        self.wv = nn.Linear(input_dim, head_dim * num_groups)  # one value per group
        self.out = nn.Linear(head_dim * num_heads, input_dim)

    def forward(self, x, mask=None, kv_cache=None):
        B, S, _ = x.shape
        H, G, h = self.num_heads, self.num_groups, self.head_dim

        q = self.wq(x).view(B, S, H, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, H*h] -> [B, H, S, h]
        k = self.wk(x).view(B, S, G, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, G*h] -> [B, G, S, h]
        v = self.wv(x).view(B, S, G, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, G*h] -> [B, G, S, h]

        # KV cache: append the keys and values of the S new tokens to those of the P past tokens
        if kv_cache is not None:
            k = torch.cat([kv_cache[0], k], dim=2)  # [B, G, P, h], [B, G, S, h] -> [B, G, P+S, h]
            v = torch.cat([kv_cache[1], v], dim=2)  # [B, G, P, h], [B, G, S, h] -> [B, G, P+S, h]
        kv_cache = (k, v)

        # each group of H/G consecutive heads uses the key and value of its group, e.g. with 8 heads and 2 groups,
        # heads 0-3 use group 0 and heads 4-7 use group 1: [B, G, P+S, h] -> [B, H, P+S, h]
        k = k.repeat_interleave(H // G, dim=1)
        v = v.repeat_interleave(H // G, dim=1)

        attn = scaled_dot_product_attention(q, k, v, mask)               # [B, H, S, h]
        attn = attn.permute(0, 2, 1, 3).contiguous().view(B, S, H * h)  # [B, H, S, h] -> [B, S, H*h]
        return self.out(attn), kv_cache                                  # [B, S, H*h] -> [B, S, E]
FlashAttention
GPUs have a small amount of very fast on-chip memory (SRAM, around 200 KB per streaming multiprocessor) and a large amount of slower high-bandwidth memory (HBM, tens of GB). A standard attention implementation writes the \(S \times S\) score matrix \(QK^T\) to HBM, reads it back to compute the softmax \(P\), writes \(P\), and reads it again to compute \(PV\). These memory round-trips, not the math, dominate its runtime.
In 2022, Tri Dao and colleagues presented FlashAttention, which computes exactly the same result without ever writing \(QK^T\) or \(P\) to HBM. It splits \(Q\), \(K\) and \(V\) into tiles that fit in SRAM, and loops over the tiles of keys and values to compute the output of each tile of queries. The difficulty is the softmax, which needs the maximum and the sum over all the keys of a row before it can normalize.
FlashAttention solves it with an online softmax (Milakov and Gimelshein, 2018). For each query, it keeps a running maximum \(\mu\), a running sum \(\ell\) and an unnormalized output \(o\), starting from \(\mu = -\infty\), \(\ell = 0\) and \(o = 0\). Whenever a new tile of scores \(s_j\) and values \(v_j\) arrives, they are updated as:
\[\begin{align*} \mu' & = \max\left(\mu, \max_j s_j\right) \\ \ell' & = e^{\mu - \mu'} \, \ell + \sum_j e^{s_j - \mu'} \\ o' & = e^{\mu - \mu'} \, o + \sum_j e^{s_j - \mu'} \, v_j \end{align*}\]where \(j\) runs over the keys of the tile, and \(\mu'\), \(\ell'\) and \(o'\) are the updated values. Subtracting the maximum keeps every exponential at most 1, so it cannot overflow, and the factor \(e^{\mu - \mu'}\) rescales what was accumulated with the previous maximum. After the last tile, the output is \(o / \ell\).
Thus, the speedup of FlashAttention comes from better memory usage, not from fewer FLOPs: the memory used by attention drops from \(O(S^2)\) to \(O(S)\), and the traffic to HBM drops by a large factor, while the arithmetic stays \(O(S^2 E)\). With a causal mask, the tiles entirely above the diagonal are skipped, which saves about half of the work. During training, the backward pass recomputes \(QK^T\) and \(P\) tile by tile instead of storing them.
Each new version of FlashAttention adapted the algorithm to newer hardware:
- FlashAttention-2 (2023) swapped the order of the two loops: each tile of queries keeps its output on chip until the end, while the first version wrote the outputs back to HBM after each tile of keys and values. It also improved the parallelism and the partitioning of work across the GPU, and reduced the non-matmul operations, as, on an A100, a non-matmul FLOP is 16 times more expensive than a matmul FLOP. It is about twice as fast as the first version.
- FlashAttention-3 (2024) targets NVIDIA Hopper GPUs (H100). It overlaps data movement, matrix multiplications and softmax with the asynchronous hardware of Hopper, and supports FP8.
- FlashAttention-4 (2026) targets NVIDIA Blackwell GPUs (B200), whose tensor cores became much faster while the units computing exponentials and the shared memory did not. It emulates part of the exponentials in software, skips most of the rescaling steps of the online softmax, and keeps intermediate results in the new tensor memory of Blackwell. On a B200, it reaches up to 1,613 TFLOP/s in BF16 (71% utilization), up to 1.3 times faster than cuDNN 9.13 and 2.7 times faster than Triton.
In PyTorch, torch.nn.functional.scaled_dot_product_attention (SDPA) computes the same result as the scaled_dot_product_attention function above, but dispatches to a FlashAttention or memory-efficient kernel when the inputs allow it. Also, FlexAttention generates fused kernels for custom masks.
FlashDecoding
FlashAttention parallelizes over the batch, the heads and the blocks of queries. During decode there is a single query per sequence, so with a small batch most of the GPU sits idle while a few thread blocks walk through a long KV cache.
Flash-Decoding (2023) also splits the keys and values along the sequence. The chunks are processed in parallel, each producing a partial output and its softmax statistics (maximum and sum), and a final reduction combines them with the same rescaling as the online softmax. This makes decoding with very long contexts up to 8 times faster. Kernel libraries such as FlashInfer implement this split-KV strategy, together with attention over paged KV caches.
Quantized attention: SageAttention
Attention can also run in lower precision. The SageAttention family, from Tsinghua University, quantizes the inputs of the two matrix multiplications of attention, in a plug-and-play way that needs no retraining:
- SageAttention computes \(QK^T\) in INT8 and \(PV\) in 16 bits. In some channels, all keys share a large common value that would waste the INT8 range, so it first smooths \(K\) by subtracting its mean over the tokens. This does not change the result: subtracting the mean key \(\bar{k}\) from all keys subtracts the same value \(q \cdot \bar{k}\) from every score of a row, and the softmax is not affected by such a shift.
- SageAttention2 quantizes \(Q\) and \(K\) to INT4 with fine-grained (per-thread) scales, and computes \(PV\) in FP8.
- SageAttention3 uses the FP4 tensor cores of NVIDIA Blackwell GPUs with micro-scaling, and reaches 1,038 TOPS on an RTX 5090, about 5 times faster than the fastest FlashAttention on that GPU.
Unlike FlashAttention, these kernels are not exact, but the first SageAttention is already about 2.1 times faster than FlashAttention-2, with almost no loss in the end-to-end metrics of language, image and video models.
Sparse attention
In practice, each query puts most of its attention weight on a small subset of the tokens. Sparse attention computes attention only over the tokens that matter. The difficulty is to find them cheaply, and to read them from memory efficiently: GPUs are fast on contiguous blocks of memory, and slow on scattered individual tokens. The speedup of sparse attention kernels comes mostly from the blocks of keys and values that they do not load from HBM into SRAM.
Fixed patterns. The simplest patterns are known in advance, as the local and strided patterns introduced in 2019 by the Sparse Transformer. In sliding window attention, each token attends only to a window of the most recent tokens, which bounds the size of the KV cache. As an example, Mistral 7B uses a window of 4,096 tokens, and since each of its 32 layers moves information forward by up to one window, its theoretical attention span is about 131K tokens. Longformer combines local windows with a few global tokens, and BigBird also adds a few random tokens.
StreamingLLM found that models put a lot of attention on the first few tokens, regardless of their content, and called them attention sinks. The softmax weights of a query must sum to one, so a query puts the weight it does not need on the first tokens, which every later token can see. Keeping these few tokens plus a window of recent tokens lets a model generate stably over millions of tokens without retraining, while a plain sliding window collapses once the first tokens leave the window.
KV eviction and selection without retraining. H2O keeps only the recent tokens and the heavy hitters, the tokens that received the most attention so far, and evicts the others. SnapKV selects the important tokens of each head from the attention of the last prompt tokens. Eviction saves memory, but an evicted token is lost, even if it becomes relevant later.
Quest keeps the whole cache instead, and stores the element-wise minimum and maximum of the keys of each page. These bound the attention score that any query can give to the page, so each decode step loads only the most promising pages for the current query.
Trainable sparse attention. Applying sparsity only at inference creates a mismatch with how the model was trained, and selecting individual tokens is hard to make fast. Recent methods therefore train the model with sparse attention. In 2025, Native Sparse Attention (NSA), from DeepSeek-AI, Peking University and the University of Washington (ACL 2025 Best Paper), runs three attention branches in parallel and mixes their outputs with learned gates:
- a compressed branch attends to coarse summaries of blocks of tokens, a cheap global view;
- a selected branch uses the scores of the compressed branch to pick the most important blocks, and attends to their tokens in full detail;
- a sliding window branch covers the local context.
Selection works on contiguous blocks, and all heads of a GQA group share the same selected blocks, so these are loaded only once, which keeps the kernels fast. NSA matches or beats full attention on general, long-context and reasoning benchmarks. On 64K-token sequences, it is up to 9 times faster in the forward pass, 6 times faster in the backward pass and 11.6 times faster in decoding.
Two other methods select blocks or tokens in a similar way. Mixture of Block Attention (MoBA), from Moonshot AI, applies the idea of mixture of experts to attention: for each query, a gate picks the few blocks of keys and values to attend to. The gate scores each block by the dot product of the query with the mean key of the block, so, unlike NSA, MoBA adds no parameters to the model. DeepSeek Sparse Attention (DSA), introduced in DeepSeek-V3.2, selects individual tokens with a small lightning indexer; the section on the DeepSeek models, below, describes and implements it.
Note that sparse attention reduces the compute and the amount of KV cache read at each step, but except for the eviction methods, the cache still stores every token.
Linear attention and hybrid models
In 2020, Katharopoulos et al. showed that attention can run in linear time, if the softmax is removed so that the matrix products can be reordered. Replacing \(\text{softmax}(QK^T)V\) with \(\phi(Q)\left(\phi(K)^T V\right)\), for some feature map \(\phi\), turns \(\phi(K)^T V\) into a small \(d_k \times d_v\) matrix, where \(d_k\) is the size of the features \(\phi(k)\) and \(d_v\) the size of the values. Thus, the cost grows linearly with the sequence length, instead of quadratically, hence the name linear attention.
During decode, linear attention behaves like a recurrent neural network: instead of a KV cache that grows with every token, each layer keeps a fixed-size state matrix \(M\) that maps keys to values. The state and the output of token \(t\) are computed as:
\[M_t = M_{t-1} + v_t \phi(k_t)^T, \quad\quad o_t = M_t \phi(q_t)\]where \(q_t\), \(k_t\) and \(v_t\) are the query, key and value of token \(t\), and \(o_t\) is its output. The state \(M\) has a fixed size of \(d_v \times d_k\), without the sequence length in its dimensions, so the memory and the time per token stay constant, whatever the context length.
However, a fixed-size state is a lossy memory that cannot hold all the details of a long context, so pure linear attention models recall exact information worse than softmax attention. A few methods improved this in recent years:
- Gating lets the model forget: \(M_t = \alpha_t M_{t-1} + v_t k_t^T\), with a data-dependent decay \(\alpha_t \in (0, 1)\), and with \(\phi\) folded into \(k_t\). State space models such as Mamba and Mamba-2 are closely related.
- The delta rule lets the model overwrite: \(M_t = M_{t-1} - \beta_t \left(M_{t-1} k_t - v_t\right) k_t^T\). Instead of adding \(v_t\) on top of what is already stored for the key \(k_t\), it moves the stored value towards \(v_t\) by a learned step \(\beta_t\) (for keys of unit length, as in these models). Schlag et al. introduced it into linear attention in 2021, and Gated DeltaNet combines both ideas.
- Kimi Delta Attention (KDA), from Moonshot AI, is a Gated DeltaNet with a finer-grained gate: one decay per channel instead of one per head.
Hybrid models keep the exact recall of softmax attention: they interleave the linear attention layers with a few full attention layers. As an example, Kimi Linear has one full attention layer (MLA) for every three KDA layers, and its 48B-parameter model (a mixture of experts with 3B active parameters) outperformed full MLA with the same training recipe. It also reduced the KV cache by up to 75%, and increased the decoding throughput up to 6 times at a 1M-token context. Other hybrid models follow the same recipe with different linear layers, such as Jamba (Mamba layers), MiniMax-01 (lightning attention) and Qwen3-Next (Gated DeltaNet).
To find more about the topic, Efficient Transformers: A Survey (Tay et al.) reviews many earlier sparse and linear attention variants.
Sparse plus linear attention: SLA
Diffusion transformers (DiTs), the models behind modern image and video generators, use bidirectional attention over very long sequences. A short video has tens of thousands of tokens, and attention runs at every denoising step, so it dominates the generation time.
SLA (Sparse-Linear Attention; Tsinghua University; ICLR 2026) starts from an observation: the attention weights split into a small fraction of large weights, which have a high rank, and a large majority of small weights, which have a very low rank. Sparse attention alone must keep too many blocks to stay accurate, and linear attention alone, whose attention matrix \(\phi(Q)\phi(K)^T\) has a rank of at most \(d_k\), loses too much quality. Thus, SLA splits the attention matrix into blocks and classifies each block as:
- critical, computed exactly with FlashAttention (quadratic cost, but only for a few blocks);
- marginal, computed with linear attention (cheap);
- negligible, skipped.
All three run in a single fused GPU kernel, for both the forward and backward passes, and a few fine-tuning steps adapt the model to it. On the Wan2.1-1.3B video model, SLA reduces the attention computation by 95% without degrading the generation quality, with a 13.7 times faster attention kernel and 2.2 times faster end-to-end video generation. Note that SLA targets diffusion transformers, and is not designed for the token-by-token decoding of language models.
DeepSeek Multi-head Latent Attention
In 2024, DeepSeek-V2 introduced Multi-head Latent Attention (MLA), which compresses the key and value of each token into a single small latent vector, and caches only that vector. The keys and values of each head are recovered with up-projection matrices. These matrices can be merged (absorbed) into the query and output projections, so that attention runs directly on the cached latent vectors.
With absorption, the cached latent vectors act as the keys and the values: MLA behaves like MQA, with a single, larger key-value head shared by all heads. However, rotary positional embeddings (RoPE) prevent the merge, because their rotation, which depends on the positions of the query and the key, sits between the query projection and the key up-projection. So MLA adds a small separate key component that carries the position.
Per token and layer, DeepSeek-V2 caches 576 values (a latent vector of 512 values and a position key of 64), against 2,048 for GQA with 8 key-value heads of size 128. Compared with DeepSeek 67B, DeepSeek-V2 reduced the KV cache by 93.3%, and increased its maximum generation throughput 5.76 times. Moreover, the DeepSeek-V2 paper reports that MLA performs better than MHA, while the quality of GQA and MQA does not match that of MHA.
MLA mainly accelerates decode, which is limited by memory bandwidth: as MQA and GQA, it shrinks the KV cache that every decoding step reads. Prefill is limited by compute instead, and absorbed attention costs more FLOPs per score, as it works in the latent dimension (512 in DeepSeek-V2) instead of the head dimension (128). Therefore, implementations usually up-project the latent vectors into keys and values during prefill, and use absorption during decode. The following picture illustrates both ways:
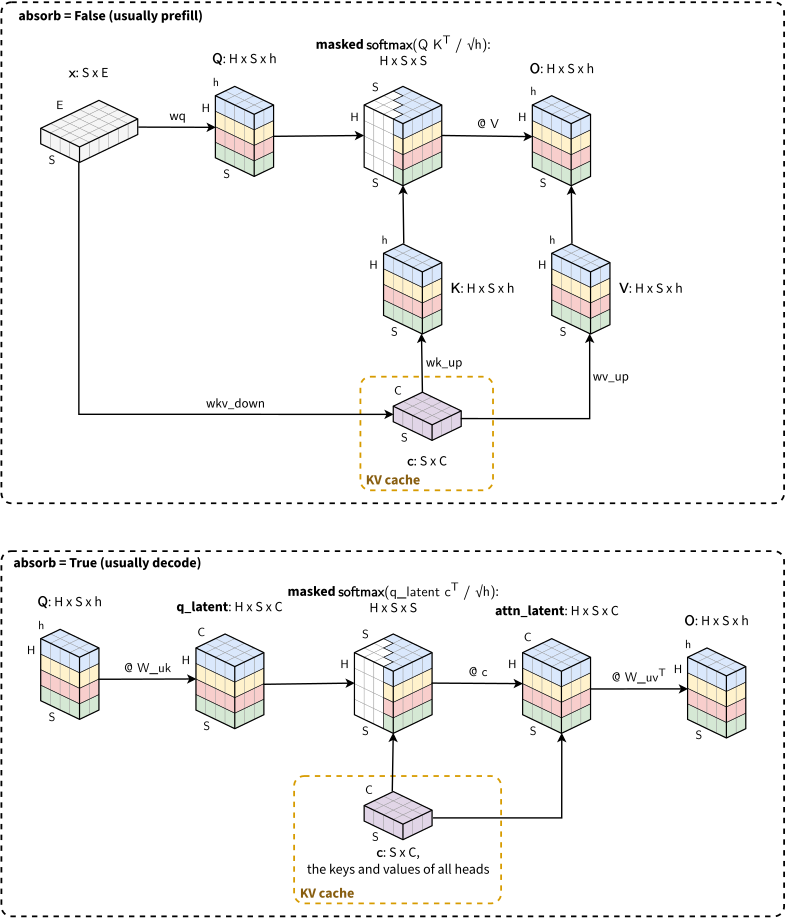
Multi-head latent attention, with S = 4 tokens, a latent dimension C = 3, H = 4 heads and a head dimension h = 2. With absorb = False (usually prefill), the keys and values of every head are recomputed from the cached latent vectors c. With absorb = True (usually decode), the queries are multiplied by W_uk, the attention runs directly over the cached latent vectors, and W_uv is applied to its output. Both panels show a whole sequence; in decode, the single new token attends to all the cached latent vectors, with no masked cells.
The following code implements MLA, without RoPE and its separate position key. First, the module computes the queries, and compresses the input into the latent vectors, which are the only tensors of the KV cache. Without absorption (absorb = False), it then recomputes the keys and values of every head from the latent vectors. With absorption (absorb = True), it multiplies the queries by the key up-projection, attends directly over the latent vectors, and applies the value up-projection to the output, which gives the same result:
class MLA(nn.Module):
    """ Multi-head Latent Attention: the keys and values of all heads are computed from a single latent vector of
        size C = latent_dim per token, and the KV cache stores only that vector. With absorption, the latent vectors
        behave like a single key-value head shared by all heads (multi-query attention). Implementations usually
        prefill with absorb = False and decode with absorb = True """

    def __init__(self, input_dim, head_dim, num_heads=8, latent_dim=128):
        super().__init__()
        self.head_dim = head_dim
        self.num_heads = num_heads
        self.wq = nn.Linear(input_dim, head_dim * num_heads)
        self.wkv_down = nn.Linear(input_dim, latent_dim, bias=False)  # compresses each token into a latent vector
        self.wk_up = nn.Linear(latent_dim, head_dim * num_heads)      # recovers the keys of all heads
        self.wv_up = nn.Linear(latent_dim, head_dim * num_heads)      # recovers the values of all heads
        self.out = nn.Linear(head_dim * num_heads, input_dim)
        self.absorb = True  # attention directly over the latent vectors, without recomputing keys and values

    def forward(self, x, mask=None, kv_cache=None):
        B, S, _ = x.shape
        H, h = self.num_heads, self.head_dim

        q = self.wq(x).view(B, S, H, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, H*h] -> [B, H, S, h]
        c = self.wkv_down(x)                                 # [B, S, E] -> [B, S, C]: the latent vectors

        # KV cache: only the latent vectors, of the P past tokens followed by the S new ones
        if kv_cache is not None:
            c = torch.cat([kv_cache, c], dim=1)  # [B, P, C], [B, S, C] -> [B, P+S, C]
        kv_cache = c

        if self.absorb:
            # absorb the key up-projection into the query: q.(W_uk c + b_uk) = (W_uk^T q).c + q.b_uk, where the last
            # term adds the same value to all the scores of a query, so the softmax is not affected by it
            W_uk = self.wk_up.weight.view(H, h, -1)             # [H*h, C] -> [H, h, C]
            q_latent = torch.einsum('bhsd,hdc->bhsc', q, W_uk)  # [B, H, S, h] -> [B, H, S, C]
            # attention with the latent vectors as a single key-value head, scaled by 1/sqrt(h) as the original
            # attention: [B, H, S, C] (queries), [B, 1, P+S, C] (keys and values) -> [B, H, S, C]
            c = c.unsqueeze(1)                                  # [B, P+S, C] -> [B, 1, P+S, C]
            attn_latent = scaled_dot_product_attention(q_latent, c, c, mask, scale=h ** -0.5)
            # absorb the value up-projection: sum_t w_t (W_uv c_t + b_uv) = W_uv (sum_t w_t c_t) + b_uv,
            # as the attention weights w_t sum to 1
            W_uv = self.wv_up.weight.view(H, h, -1)                   # [H*h, C] -> [H, h, C]
            attn = torch.einsum('bhsc,hdc->bhsd', attn_latent, W_uv)  # [B, H, S, C] -> [B, H, S, h]
            attn = attn + self.wv_up.bias.view(H, 1, h)               # [B, H, S, h]
        else:
            # recompute the keys and values of all heads from the latent vectors
            k = self.wk_up(c).view(B, -1, H, h).permute(0, 2, 1, 3)  # [B, P+S, C] -> [B, P+S, H*h] -> [B, H, P+S, h]
            v = self.wv_up(c).view(B, -1, H, h).permute(0, 2, 1, 3)  # [B, P+S, C] -> [B, P+S, H*h] -> [B, H, P+S, h]
            attn = scaled_dot_product_attention(q, k, v, mask)       # [B, H, S, h]

        attn = attn.permute(0, 2, 1, 3).contiguous().view(B, S, H * h)  # [B, H, S, h] -> [B, S, H*h]
        return self.out(attn), kv_cache                                  # [B, S, H*h] -> [B, S, E]
DeepSeek-V3.2: DeepSeek Sparse Attention
DeepSeek-V3.2 (2025) keeps MLA and adds DeepSeek Sparse Attention (DSA). For each query token \(t\), a small lightning indexer scores every past token \(s\), with an index score given by:
\[I_{t,s} = \sum_{j} w^I_{t,j} \cdot \text{ReLU}\left( q^I_{t,j} \cdot k^I_s \right)\]where \(q^I_{t,j}\) are the queries of the indexer heads \(j\) and \(w^I_{t,j}\) their weights, both computed from the query token, and \(k^I_s\) is a single indexer key per token. The indexer runs in FP8 and is much cheaper than the main attention. The main attention then reads only the 2,048 tokens with the highest index scores, the same tokens for all heads. Thus, its cost per query stops growing with the context, and only the cheap indexer still scores every past token.
DSA was added to an already trained model, in two stages. First, during a short dense warm-up, the model keeps its dense attention, and only the indexer is trained to imitate the attention distribution of its layer (the attention weights summed over the heads and normalized), with a KL-divergence loss. Then, the whole model is trained with sparse attention, and the input of the indexer is detached from the rest of the model, so that the indexer learns only from its own loss.
With a KV cache, the indexer key of every token is cached too. Index scores are often tied, since the ReLU outputs many zeros, so the selection uses a stable sort, which breaks ties the same way whether the tokens are processed together or one at a time. Decoding with a KV cache then gives the same result as processing the whole sequence at once. The following picture illustrates DSA with \(H = 4\) heads, where each query attends only to the 3 tokens with the highest index scores:
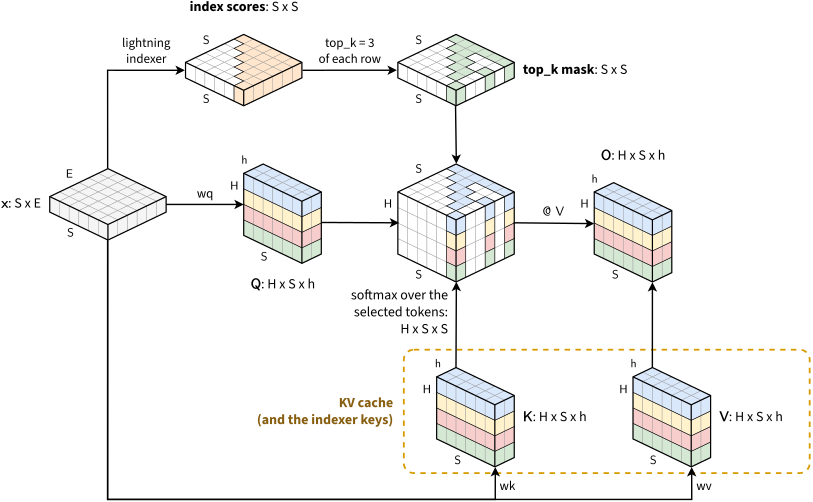
The following code adds DSA to multi-head attention. It keeps the projections of GQA with num_groups = num_heads, so it can load the weights of a trained MHA module, and adds the indexer. First, lightning_index_scores computes the index scores of the formula above, top_k_indices selects the highest ones with a stable sort, and indexer_loss computes the loss of the warm-up.
During the dense warm-up (dense = True), the queries attend to all past tokens, and the module computes indexer_loss, which is backpropagated alone to train the indexer. Afterwards, each query attends only to the top_k past tokens with the highest index scores; for simplicity, the code trains the indexer only during the warm-up. Note that the selection is applied as a mask over all the scores: the code shows the effect of DSA on quality, but its speedup needs a kernel that reads only the selected keys and values:
def lightning_index_scores(q, w, k):
    """ Index scores I[t, s] = sum_j w[t, j] * ReLU(q[t, j] . k[s]) of the lightning indexer, for the queries
        q: [B, Sq, HI, DI], their head weights w: [B, Sq, HI] and a single key per token or entry k: [B, Sk, DI],
        where HI is the number of indexer heads and DI their size """
    dots = F.relu(torch.einsum('bqjd,bkd->bqjk', q, k))  # [B, Sq, HI, DI], [B, Sk, DI] -> [B, Sq, HI, Sk]
    return torch.einsum('bqjk,bqj->bqk', dots, w)        # [B, Sq, HI, Sk], [B, Sq, HI] -> [B, Sq, Sk]


def top_k_indices(scores, k):
    """ Indices of the k highest scores of each row: [B, Sq, Sk] -> [B, Sq, k]. A stable sort breaks ties by keeping
        the earliest entries, so the selection is the same whether a sequence is processed at once or one token
        at a time """
    return scores.sort(dim=-1, descending=True, stable=True).indices[..., :k]


def indexer_loss(index_scores, attention_scores, mask):
    """ KL divergence between the attention distribution (the target: attention weights summed over heads and
        normalized) and the softmax of the index scores, over the entries each query can see.
        index_scores: [B, Sq, Sk], attention_scores: [B, H, Sq, Sk] logits, mask: [Sq, Sk] or [B, Sq, Sk] """
    with torch.no_grad():
        weights = F.softmax(attention_scores.masked_fill(~mask.unsqueeze(-3), -1e9), dim=-1)  # [B, H, Sq, Sk]
        target = weights.sum(dim=1) * mask  # [B, H, Sq, Sk] -> [B, Sq, Sk]
        target = target / target.sum(dim=-1, keepdim=True).clamp(min=1e-9)
    log_index = F.log_softmax(index_scores.masked_fill(~mask, -1e9), dim=-1).masked_fill(~mask, 0.0)  # [B, Sq, Sk]
    return F.kl_div(log_index.flatten(0, -2), target.flatten(0, -2), reduction='batchmean')


class DSA(nn.Module):
    """ Causal multi-head attention with DeepSeek Sparse Attention: a small lightning indexer scores the past tokens
        of each query, and all heads attend only to the top_k tokens with the highest scores. The KV cache holds the
        keys, the values and the indexer keys of the past tokens. The selection is applied as a mask over the scores
        of all tokens, which shows its effect on quality; the speedup needs a kernel that reads only the keys and
        values of the selected tokens """

    def __init__(self, input_dim, head_dim, num_heads=8, top_k=64, index_heads=4, index_dim=16):
        super().__init__()
        self.head_dim = head_dim
        self.num_heads = num_heads
        self.top_k = top_k
        self.index_heads = index_heads
        self.index_dim = index_dim
        self.wq = nn.Linear(input_dim, head_dim * num_heads)
        self.wk = nn.Linear(input_dim, head_dim * num_heads)
        self.wv = nn.Linear(input_dim, head_dim * num_heads)
        self.out = nn.Linear(head_dim * num_heads, input_dim)
        # lightning indexer: a few query heads with a weight each, and a single key per token
        self.index_wq = nn.Linear(input_dim, index_heads * index_dim)
        self.index_w = nn.Linear(input_dim, index_heads)
        self.index_wk = nn.Linear(input_dim, index_dim)
        self.dense = False        # dense warm-up: attend to all past tokens, and train the indexer to imitate them
        self.indexer_loss = None  # KL divergence between the attention and the indexer, during the dense warm-up

    def forward(self, x, kv_cache=None):
        B, S, _ = x.shape
        H, h, HI, DI = self.num_heads, self.head_dim, self.index_heads, self.index_dim

        q = self.wq(x).view(B, S, H, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, H*h] -> [B, H, S, h]
        k = self.wk(x).view(B, S, H, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, H*h] -> [B, H, S, h]
        v = self.wv(x).view(B, S, H, h).permute(0, 2, 1, 3)  # [B, S, E] -> [B, S, H*h] -> [B, H, S, h]

        # lightning indexer: it is trained on its own, without gradients into the rest of the model
        x_index = x.detach()
        q_index = self.index_wq(x_index).view(B, S, HI, DI)  # [B, S, E] -> [B, S, HI*DI] -> [B, S, HI, DI]
        w_index = self.index_w(x_index)                      # [B, S, E] -> [B, S, HI]
        k_index = self.index_wk(x_index)                     # [B, S, E] -> [B, S, DI]

        # KV cache: the keys, values and indexer keys of the P past tokens, followed by those of the S new ones
        if kv_cache is not None:
            k = torch.cat([kv_cache[0], k], dim=2)              # [B, H, P, h], [B, H, S, h] -> [B, H, P+S, h]
            v = torch.cat([kv_cache[1], v], dim=2)              # [B, H, P, h], [B, H, S, h] -> [B, H, P+S, h]
            k_index = torch.cat([kv_cache[2], k_index], dim=1)  # [B, P, DI], [B, S, DI] -> [B, P+S, DI]
        kv_cache = (k, v, k_index)
        Sk = k.size(2)  # P+S

        index_scores = lightning_index_scores(q_index, w_index, k_index)  # [B, S, P+S]
        causal = causal_mask(S, Sk, x.device)                             # [S, P+S]
        if self.dense:  # dense attention; the indexer learns to imitate it
            mask = causal
            # attention logits: [B, H, S, h] @ [B, H, h, P+S] -> [B, H, S, P+S]
            scores = q @ k.transpose(-1, -2) / h ** 0.5
            self.indexer_loss = indexer_loss(index_scores, scores, causal)
        else:  # the top_k past tokens with the highest index scores, the same for all heads: [B, S, top_k]
            top = top_k_indices(index_scores.masked_fill(~causal, float('-inf')), min(self.top_k, Sk))
            mask = torch.zeros(B, S, Sk, dtype=torch.bool, device=x.device).scatter_(-1, top, True)  # [B, S, P+S]
            mask = mask & causal
            self.indexer_loss = None

        attn = scaled_dot_product_attention(q, k, v, mask)               # [B, H, S, h]
        attn = attn.permute(0, 2, 1, 3).contiguous().view(B, S, H * h)  # [B, H, S, h] -> [B, S, H*h]
        return self.out(attn), kv_cache                                  # [B, S, H*h] -> [B, S, E]
DeepSeek-V4: Compressed Sparse Attention and Heavily Compressed Attention
DeepSeek-V4 (2026) supports a context of one million tokens. It replaces MLA with two types of attention that compress the KV cache along the sequence, interleaved across the layers (Hugging Face’s implementation documents the details):
- Compressed Sparse Attention (CSA) compresses the keys and values of every \(m = 4\) tokens into a single entry. Each entry is a sum of per-token vectors, weighted by a softmax over the tokens, computed separately for every channel, and it also covers the previous block, so the windows overlap. A lightning indexer, as in DSA but over the compressed entries, then selects the top entries of each query: 512 in DeepSeek-V4-Flash, and 1,024 in DeepSeek-V4-Pro.
- Heavily Compressed Attention (HCA) compresses every \(m' = 128\) tokens into a single entry, without overlap, and attends to all the entries, as the compressed sequence is short enough for dense attention.
Both use multi-query attention with a single key-value vector per entry, shared by all the query heads and used both as the key and as the value. A query only sees the entries of the blocks before its own block, as the entry of its own block may also cover later tokens. Therefore, every layer also attends to the uncompressed vectors of the last 128 tokens, a sliding window that keeps the local details.
A few other details complete the design: low-rank queries whose latent vector is shared with the indexer, and RMSNorm on the queries and the entries, which keeps the attention logits from exploding. Each head also has an attention sink (a learned logit that lets it attend to almost nothing), and the output projection is grouped. As a side note, serving engines must manage a different cache in every layer: the compressed entries, the indexer keys, the sliding window, and the tokens of the last, incomplete block.
With a context of one million tokens, DeepSeek-V4-Pro needs only 27% of the per-token inference FLOPs and 10% of the KV cache of DeepSeek-V3.2. The following table compares the attention of the DeepSeek models:
| Model | Attention | KV cache per layer | Each query attends to |
|---|---|---|---|
| DeepSeek-V2 and V3 | MLA | 576 values per token | all the past tokens |
| DeepSeek-V3.2 | MLA and DSA | 576 values and an indexer key per token | the top 2,048 past tokens |
| DeepSeek-V4, CSA layers | compression by 4, then top-k | an entry and an indexer key every 4 tokens, plus the last 128 tokens | the top-k entries and the last 128 tokens |
| DeepSeek-V4, HCA layers | compression by 128 | an entry every 128 tokens, plus the last 128 tokens | all the entries and the last 128 tokens |
The following pictures illustrate CSA and HCA on short sequences, for the last query of each sequence:
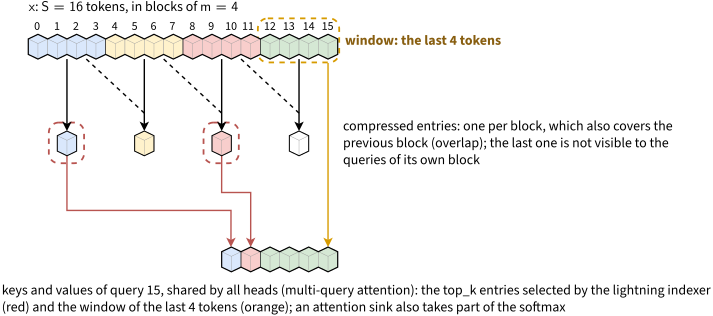
Compressed Sparse Attention (CSA) for query 15, with S = 16 tokens, blocks of m = 4 tokens, top_k = 2 and a window of the last 4 tokens. Each compressed entry also covers the previous block (dashed arrows). Entry 3 (dark grey) compresses the block of query 15 and is not visible to it. Inspired by: DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence
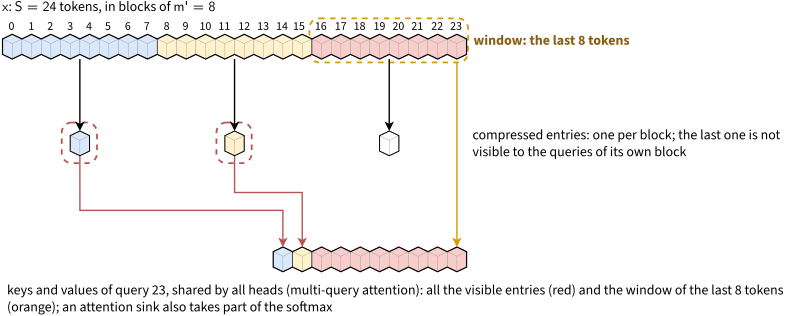
Heavily Compressed Attention (HCA) for query 23, with S = 24 tokens, blocks of m’ = 8 tokens, no overlap, and a window of the last 8 tokens. Entries 0 and 1 cover tokens 0 to 15, and the window covers tokens 16 to 23, the block of query 23, whose entry 2 (dark grey) is not visible to it. Inspired by: DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence
The following code implements both attention types in a single module, CSA when top_k is given and HCA otherwise. First, Compressor compresses the hidden states of every \(m\) tokens into one entry, with the overlap of CSA. Then, CompressedAttention masks the entries that each query cannot see, keeps the top_k entries of the lightning indexer for CSA, and attends to the entries and to the window together with the attention sink.
A model alternates CSA and HCA across its blocks. The module expects positional information in its input, such as learned positional embeddings, so it omits rotary embeddings. As in DSA, the indexer receives an input detached from the rest of the model, and learns to imitate the attention over the compressed entries with the KL-divergence loss indexer_loss, which is added to the training loss.
These attention types change the architecture, so a model that uses them is trained from scratch. Unlike the other modules of this post, this one has no KV cache, whose four parts are listed above, and processes whole sequences, as in training and prefill:
# lightning_index_scores, top_k_indices and indexer_loss are defined in the DSA code above

class Compressor(nn.Module):
    """ Compresses the hidden states of every m tokens into one entry: a sum of per-token entries, weighted per
        channel by a softmax over the tokens of the block, with learned positional biases. With overlap (CSA),
        each entry also covers the m tokens of the previous block, through a second series of entries and weights.
        The tokens of a trailing incomplete block are not compressed (the sliding window covers them) """

    def __init__(self, input_dim, entry_dim, m, overlap):
        super().__init__()
        self.m = m
        self.overlap = overlap
        n_series = 2 if overlap else 1
        self.wc = nn.Linear(input_dim, n_series * entry_dim, bias=False)        # entries C^a (and C^b)
        self.wz = nn.Linear(input_dim, n_series * entry_dim, bias=False)        # weights Z^a (and Z^b)
        self.position_bias = nn.Parameter(torch.zeros(n_series, m, entry_dim))  # B^a (and B^b)

    def forward(self, x):
        """ x: [B, S, E] -> compressed entries: [B, N, D], with N = S // m blocks and D = entry_dim """
        B, N = x.size(0), x.size(1) // self.m
        x = x[:, :N * self.m]                           # [B, S, E] -> [B, N*m, E]
        C = self.wc(x).unflatten(1, (N, self.m))        # [B, N*m, E] -> [B, N, m, n_series*D]
        Z = self.wz(x).unflatten(1, (N, self.m))        # [B, N*m, E] -> [B, N, m, n_series*D]
        if self.overlap:
            (Ca, Cb), (Za, Zb) = C.chunk(2, dim=-1), Z.chunk(2, dim=-1)    # [B, N, m, D] each
            Za, Zb = Za + self.position_bias[0], Zb + self.position_bias[1]
            Cb = F.pad(Cb, (0, 0, 0, 0, 1, 0))[:, :N]  # series b of the previous block (none for block 0)
            Zb = F.pad(Zb, (0, 0, 0, 0, 1, 0), value=float('-inf'))[:, :N]
            C, Z = torch.cat([Ca, Cb], dim=2), torch.cat([Za, Zb], dim=2)  # [B, N, 2m, D]
        else:
            Z = Z + self.position_bias[0]
        return (F.softmax(Z, dim=2) * C).sum(dim=2)  # [B, N, m or 2m, D] -> [B, N, D]


class CompressedAttention(nn.Module):
    """ DeepSeek-V4 attention, always causal, over whole sequences (without a KV cache). Both types compress every
        m tokens into one entry:
        - CSA, e.g. CompressedAttention(E, h, m=4, top_k=512): with overlap, and a lightning indexer selects the
          top_k compressed entries of each query;
        - HCA, e.g. CompressedAttention(E, h, m=128): without overlap, and each query attends to all the entries.
        Both use shared key-value multi-query attention: each entry is both the key and the value of all query heads,
        together with uncompressed entries of the last `window` tokens. The indexer is trained, as in DSA, to imitate
        the attention over the compressed entries: in training, add indexer_loss to the loss. The input is expected
        to carry positional information (e.g. learned positional embeddings), so DeepSeek-V4's partial RoPE is
        omitted """

    def __init__(self, input_dim, head_dim, num_heads=8, m=4, window=128, top_k=None,
                 out_groups=2, index_heads=4, index_dim=16):
        super().__init__()
        self.head_dim = head_dim
        self.num_heads = num_heads
        self.m = m
        self.window = window
        self.top_k = top_k
        q_latent_dim = input_dim // 2
        self.wq_down = nn.Linear(input_dim, q_latent_dim)  # low-rank queries; the latent is shared with the indexer
        self.wq_up = nn.Linear(q_latent_dim, head_dim * num_heads)
        self.compressor = Compressor(input_dim, head_dim, m, overlap=top_k is not None)
        self.w_window = nn.Linear(input_dim, head_dim)     # uncompressed entries, for the sliding window
        self.q_norm, self.kv_norm = nn.RMSNorm(head_dim), nn.RMSNorm(head_dim)
        self.sink = nn.Parameter(torch.zeros(num_heads))  # attention sink: a learned logit per head, with no value
        if top_k is not None:  # lightning indexer, with keys compressed like the entries
            self.index_heads = index_heads
            self.index_dim = index_dim
            self.index_wq = nn.Linear(q_latent_dim, index_heads * index_dim)
            self.index_w = nn.Linear(input_dim, index_heads)
            self.index_compressor = Compressor(input_dim, index_dim, m, overlap=True)
        # grouped output projection: each group of heads is projected separately, then all groups together
        self.out_groups, group_in, group_out = out_groups, num_heads // out_groups * head_dim, input_dim // out_groups
        self.w_group = nn.Parameter(torch.randn(out_groups, group_in, group_out) * group_in ** -0.5)
        self.out = nn.Linear(out_groups * group_out, input_dim)
        self.indexer_loss = None  # KL divergence between the attention over the entries and the indexer, in training

    def forward(self, x):
        B, S, _ = x.shape
        H, h, G = self.num_heads, self.head_dim, self.out_groups

        c_q = self.wq_down(x)                         # [B, S, E] -> [B, S, E/2]
        q = self.wq_up(c_q).view(B, S, H, h)          # [B, S, E/2] -> [B, S, H*h] -> [B, S, H, h]
        q = self.q_norm(q).permute(0, 2, 1, 3)        # [B, S, H, h] -> [B, H, S, h]
        entries = self.kv_norm(self.compressor(x))    # [B, S, E] -> [B, N, h], with N = S // m
        window = self.kv_norm(self.w_window(x))       # [B, S, E] -> [B, S, h]
        N, t = entries.size(1), torch.arange(S, device=x.device)

        # each query sees the compressed blocks before its own block, and the uncompressed last `window` tokens
        block_mask = torch.arange(N, device=x.device)[None, :] < (t // self.m)[:, None]     # [S, N]
        window_mask = (t[None, :] <= t[:, None]) & (t[None, :] > t[:, None] - self.window)  # [S, S]
        block_mask = block_mask.expand(B, S, N)                                             # [S, N] -> [B, S, N]
        self.indexer_loss = None
        if self.top_k is not None and N > 0:  # CSA: keep the top_k visible blocks with the highest index scores
            HI, DI = self.index_heads, self.index_dim
            x_index, c_q_index = x.detach(), c_q.detach()  # the indexer is trained only by its own loss
            q_index = self.index_wq(c_q_index).view(B, S, HI, DI)             # [B, S, E/2] -> [B, S, HI, DI]
            w_index = self.index_w(x_index)                                   # [B, S, E] -> [B, S, HI]
            k_index = self.index_compressor(x_index)                          # [B, S, E] -> [B, N, DI]
            index_scores = lightning_index_scores(q_index, w_index, k_index)  # [B, S, N]
            if self.training:  # attention logits over the entries: [B, H, S, h] @ [B, 1, h, N] -> [B, H, S, N]
                entry_scores = q @ entries.transpose(-1, -2).unsqueeze(1) / h ** 0.5
                self.indexer_loss = indexer_loss(index_scores, entry_scores, block_mask)
            index_scores = index_scores.masked_fill(~block_mask, float('-inf'))             # [B, S, N]
            top = top_k_indices(index_scores, min(self.top_k, N))                           # [B, S, N] -> [B, S, top_k]
            block_mask = torch.zeros_like(block_mask).scatter_(-1, top, True) & block_mask  # [B, S, N]

        # multi-query attention over the visible entries and window tokens, as in scaled_dot_product_attention,
        # plus the attention sink: a logit with no value, which takes part of the weight
        kv = torch.cat([entries, window], dim=1)[:, None]                    # [B, N, h], [B, S, h] -> [B, 1, N+S, h]
        mask = torch.cat([block_mask, window_mask.expand(B, S, S)], dim=-1)  # [B, S, N], [B, S, S] -> [B, S, N+S]
        scores = q @ kv.transpose(-1, -2) / h ** 0.5  # [B, H, S, h] @ [B, 1, h, N+S] -> [B, H, S, N+S]
        scores = scores.masked_fill(~mask[:, None], torch.finfo(scores.dtype).min)
        sink = self.sink.view(1, H, 1, 1).expand(B, H, S, 1)                    # [H] -> [B, H, S, 1]
        probs = F.softmax(torch.cat([scores, sink], dim=-1), dim=-1)[..., :-1]  # [B, H, S, N+S+1] -> [B, H, S, N+S]
        attn = probs @ kv  # [B, H, S, N+S] @ [B, 1, N+S, h] -> [B, H, S, h]

        # grouped output projection, with G = out_groups
        attn = attn.permute(0, 2, 1, 3).contiguous().view(B, S, G, -1)  # [B, H, S, h] -> [B, S, G, H/G*h]
        attn = torch.einsum('bsgi,gio->bsgo', attn, self.w_group)       # [B, S, G, H/G*h] -> [B, S, G, E/G]
        return self.out(attn.reshape(B, S, -1))                         # [B, S, G, E/G] -> [B, S, E] -> [B, S, E]
Summary of attention methods
The following table compares the methods of this post:
| Method | Exact? | Needs training? | What it reduces | Best for |
|---|---|---|---|---|
| FlashAttention 1-4 | yes | no | memory traffic, quadratic memory | prefill |
| FlashDecoding | yes | no | idle GPU during decode | long-context decode |
| SageAttention | almost (quantized) | no | compute, memory traffic | prefill, diffusion models |
| MQA, GQA, MLA | changes the model | uptraining or pre-training | KV cache size and reads | decode, large batches |
| Sliding window with attention sinks | no | no | KV cache size | streaming generation |
| H2O, SnapKV, Quest | no | no | KV cache size or reads | long-context decode |
| NSA, MoBA | no (learned sparsity) | yes | compute, KV cache reads | long contexts |
| DSA (DeepSeek-V3.2) | no (learned sparsity) | continued training | compute, KV cache reads | long contexts |
| Linear and hybrid attention (Kimi Linear) | changes the model | pre-training | KV cache, quadratic cost | very long contexts |
| CSA and HCA (DeepSeek-V4) | changes the model | pre-training | KV cache, compute | very long contexts |
| SLA | no (learned) | a few fine-tuning steps | compute | image and video diffusion |
For more details, Efficient Attention Mechanisms for Large Language Models: A Survey (Sun et al., 2025) reviews the more recent linear and sparse attention methods, and the language models that use them, alone or in hybrid designs.