Variable sequence lengths, curriculum learning, adaptive batch size and LR
Many datasets include samples of variable length, such as audio tracks of different durations, text sentences with different numbers of tokens, and videos with different numbers of frames. To train a model on such data, it is common to trim the long samples and to pad the short ones with padding tokens to a fixed length (padding), so that batch shapes are static, at the cost of the compute and memory spent on the padding tokens. The techniques below train on the original sample sizes instead, which adds complexity, especially in distributed (multi-node, multi-GPU) environments.
Curriculum Learning
Curriculum learning is a training method that presents samples to the model in order of increasing difficulty (e.g., noise level, human score or length). This can improve stability and final performance. The rationale is that presenting very difficult samples early in training can produce large gradients and abrupt parameter updates, which may destabilize learning. For GPT models, Sequence Length Warmup starts with short sequences, whose gradients vary less, and lengthens them during training, which allows larger batches and learning rates.
Curriculum learning can also improve efficiency for variable-length data. Mixing short and long sequences in the same batch forces padding up to the longest sequence, which adds substantial compute and memory overhead. A curriculum ordered by length instead puts samples of similar lengths in the same batch, with little padding. This is also the idea of bucketing, which groups samples of similar lengths into the same batches, without ordering the batches.
On a single process, curriculum learning only needs to sort the samples by difficulty. In distributed runs with large datasets, however, this becomes non-trivial. Samples are typically assigned to ranks in an interleaved fashion (e.g., via PyTorch’s DistributedSampler; see (a) and (b) below), which can lead to load imbalance if each rank sorts only its local shard. The following picture illustrates this problem and the two approaches detailed next:
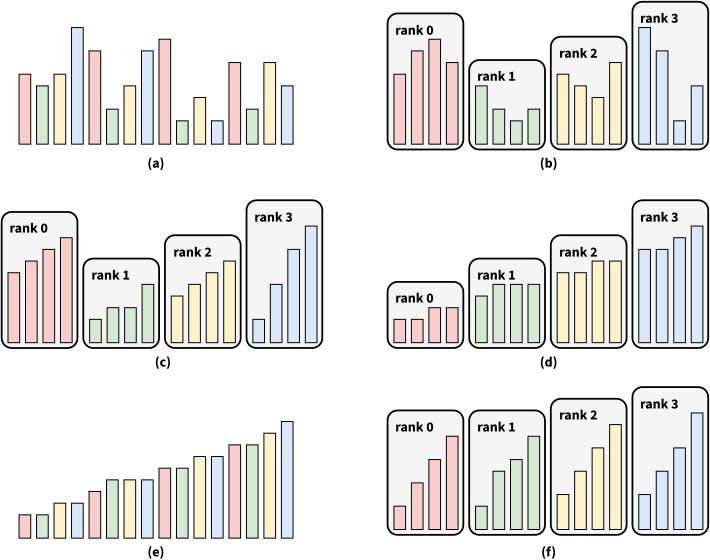
The curriculum dataset setup problem, on a network of 4 ranks and a dataset of 16 samples. (a) Original dataset, with an interleaved assignment of the 16 samples (bars) of variable lengths (bar heights) to the 4 ranks (color-coded). (b) Dataset in (a) after distributed data loading. (c) Dataset in (b) after local sorting. (d) Dataset in (b) after distributed sorting. (e) Dataset in (d) with an interleaved assignment of the 16 samples to the 4 ranks (color-coded). (f) Dataset in (e) after distributed data loading.
There are two main approaches:
- Simple (but potentially imbalanced and non-deterministic): each rank loads its shard, sorts locally, and applies curriculum learning on its local order (diagram (c)), which makes results dependent on the number of ranks.
- Complex (but balanced and deterministic): all ranks perform a distributed sort (diagram (d)), then reassign the globally sorted dataset in an interleaved fashion (diagram (e)), which balances the ranks almost perfectly (diagram (f)).
In practice, the simple approach needs no communication, while the complex one needs a distributed sort of the whole dataset, which runs once, before training. The next section details the latter.
Distributed sample sort
The tricky part is the distributed sort that transforms (b) into (d). The distributed sample sort (detailed in a previous post) is used here, as it scales well to many processes: each element is sent only once, in a single all-to-all exchange. On \(p\) ranks, it runs in four steps:
- each rank sorts its local data;
- each rank picks \(p-1\) equally spaced samples of its sorted data, and sends them to rank 0;
- rank 0 sorts the samples, takes every \(p\)-th one as a splitter, and broadcasts the \(p-1\) splitters to all ranks, which divide the range of values into \(p\) intervals, one per rank;
- each rank sends each element to the rank of its interval (the all-to-all), and sorts the elements it receives.
As the intervals follow the order of the ranks, the data is then sorted across all ranks. The workflow is illustrated below:
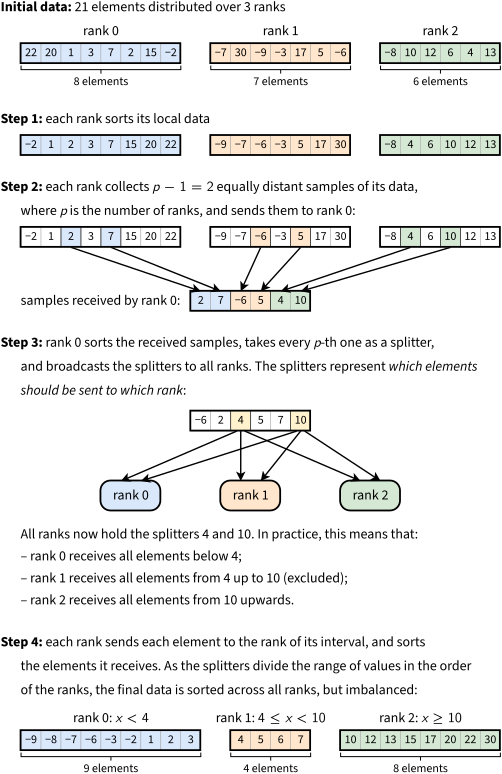
Distributed sample sort of 21 elements on \(p = 3\) ranks, colored by rank. Each rank sends \(p-1 = 2\) samples to rank 0, which sorts them and picks every \(p\)-th one as a splitter (yellow): 4 and 10. The last interval is open: rank 2 receives every element from 10 upwards.
A Python implementation is provided below. Unlike the picture, it takes 100 samples per rank by default, which brings the splitters closer to the quantiles of the data and balances the ranks better. It also uses an all-gather instead of a gather and a broadcast, so that every rank computes the same range boundaries:
def sample_sort(tensor, comm_group, num_workers, n_samples=100):
    # Perform a distributed sample sort of a tensor and return this rank's sorted shard.
    device, dims = tensor.device, tensor.size()[1]

    # 1 - sort rows lexicographically (by col0, then col1, ...)
    tensor = torch.tensor(sorted(tensor.tolist()), dtype=tensor.dtype, device=tensor.device)

    # 2 - collect a few samples per rank (use the first column as key)
    idx = torch.round(torch.linspace(0, len(tensor) - 1, n_samples)).to(int)
    samples = tensor[idx][:, 0].contiguous().to(device)

    # 3 - all-gather samples
    all_samples = [torch.zeros(n_samples, dtype=samples.dtype, device=device) for _ in range(num_workers)]
    dist.all_gather(all_samples, samples, group=comm_group)
    all_samples = torch.cat(all_samples, dim=0).to(device)

    # 4 - sort all samples and choose range boundaries for each rank
    all_samples = all_samples.sort()[0]
    idx = torch.round(torch.linspace(0, len(all_samples) - 1, num_workers + 1)).to(int)
    ranges = all_samples[idx]  # rank r owns: ranges[r] <= x < ranges[r+1]
    ranges[-1] += 1  # ensure the last bucket includes the max value

    # 5 - bucket local rows by their key range
    send = []
    for rank in range(num_workers):
        mask = (tensor[:, 0] >= ranges[rank]) & (tensor[:, 0] < ranges[rank + 1])
        send.append(tensor[mask])

    # 6 - all-to-all to communicate send/recv sizes (in number of scalars)
    send_count = [torch.tensor([len(s) * dims], dtype=torch.int64, device=device) for s in send]
    recv_count = list(torch.empty([num_workers], dtype=torch.int64, device=device).chunk(num_workers))
    dist.all_to_all(recv_count, send_count, group=comm_group)

    # 7 - all-to-all-v to exchange the flattened payloads
    send = torch.cat(send, dim=0).flatten().to(device)
    recv = torch.zeros(sum(recv_count), dtype=send.dtype).to(device)
    send_count = [s.item() for s in send_count]
    recv_count = [r.item() for r in recv_count]
    dist.all_to_all_single(recv, send, recv_count, send_count, group=comm_group)
    del send

    # 8 - reshape and sort locally again
    recv = recv.view(-1, dims)
    recv = torch.tensor(sorted(recv.tolist()), dtype=recv.dtype, device=recv.device)
    return recv
The remaining code can be found in the author’s DeepSpeed PR 5129.
Adaptive batch size and learning rate
When training on variable-length datasets, it is common to batch by token count instead of by sample count, i.e., to group samples so that the sum of sequence lengths in the batch stays near a target. For example, in Attention is all you need, section 5.1:
Sentence pairs were batched together by approximate sequence length. Each training batch contained a set of sentence pairs containing approximately 25000 source tokens and 25000 target tokens.
This helps equalize work across batches (and across ranks), in particular in curriculum learning: a batch of shape \(B \times S \times E\) (batch size × sequence length × embedding size) has a high \(B\) and a low \(S\) early in the curriculum (many short samples), and a low \(B\) and a high \(S\) later (fewer long samples).
However, varying the batch size \(B\) typically requires adjusting the learning rate (LR). Two widely used scaling rules are:
- Linear scaling: when the mini-batch size is multiplied by \(k\), multiply the LR by \(k\), so that one step on the large batch gives about the same update as \(k\) steps on the small ones (e.g., Accurate, Large Minibatch SGD: Training ImageNet in 1 Hour, Goyal et al.).
- Square-root scaling: multiply the LR by \(\sqrt{k}\) instead, to keep the noise of each update the same, as the standard deviation of the mini-batch gradient falls by \(\sqrt{k}\). Malladi et al. derive this rule for adaptive optimizers such as Adam, while Krizhevsky finds linear scaling to work better with SGD.
In practice, the hyperparameters are: (1) a target token count per batch, (2) a reference learning rate, and (3) a reference batch size. During training, each batch is packed until it reaches the token budget, and the LR is scaled based on the realized batch size.
Illustrative example
With a limit of 30 tokens per batch, batches early in curriculum learning (short sequences) contain more samples than later ones (long sequences), as shown below:
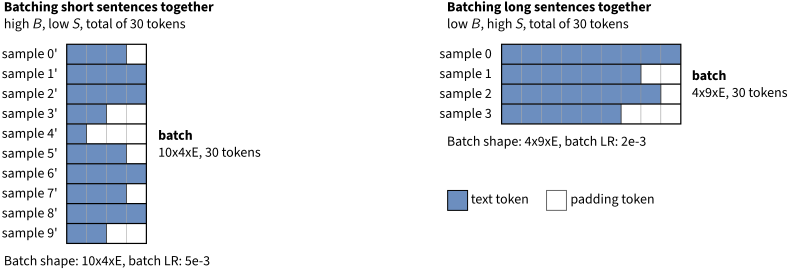
Batches of at most 30 tokens, of shape BxSxE (batch size x sequence length x embedding size), with a reference batch size of 2 and a reference learning rate (LR) of 1e-3. Short sentences (left) give a larger batch, and thus a larger LR, than long sentences (right). White cells are padding tokens.
Pipeline parallelism
Pipeline parallelism requires the same batch size and sequence length across all micro-batches within a batch, because activation shapes must stay fixed during gradient accumulation. Since version 0.15, DeepSpeed lifts this constraint with the option PipelineModule(dynamic_shape=True), at a possible cost in performance. The following picture contrasts Distributed Data Parallel (DDP, left) with pipeline parallelism (right) for 2 data-parallel ranks (each a whole pipeline) and 2 gradient accumulation steps (4 micro-batches total):
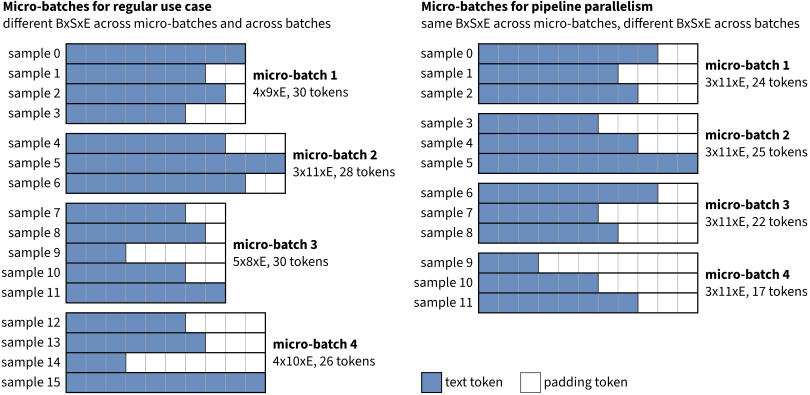
In the pipeline case (right), fewer samples are packed per micro-batch than in the non-pipeline case (left), and padding is used when needed.
Attention masks and sequence packing
With fixed shapes, an input of shape \(B \times S \times E\) often uses a 2D attention mask of shape \(S \times S\), broadcast over the batch dimension. With variable lengths, a per-sample mask is needed, a \(B \times S \times S\) tensor. For example, for the non-pipeline micro-batch 1 above (top-left; 4 sentences), the mask can be illustrated as:
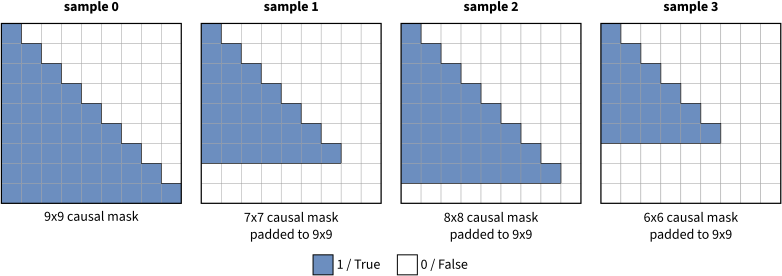
3D attention mask (BxSxS) of the non-pipeline micro-batch 1 above: its 4 samples of lengths 9, 7, 8 and 6 give a mask of size 4x9x9, with one causal mask per sample, padded to the length of the longest sample.
The cost of attention grows linearly with \(B\) and quadratically with the maximum \(S\) in the batch. Allowing \(S\) to vary (and adapting \(B\) accordingly) can therefore improve utilization by avoiding padding to an unnecessarily large \(S\).
Two related methods remove the padding tokens altogether. Sequence packing concatenates the samples of a batch into one sequence, with a block-diagonal attention mask (one causal mask per sample), so that each token attends only to the tokens of its own sample. With a dense mask, however, the packed sequence computes the attention scores of all pairs of its tokens, more than the padded batch. Variable-length (varlen) attention kernels, such as the function flash_attn_varlen_func of the FlashAttention library, take the concatenated tokens and the cumulative lengths of the samples, and compute only the blocks on the diagonal of the mask.
Implementation
First, the variable learning rate is implemented as a scheduler wrapper that scales the LR of an underlying scheduler at each step based on the realized batch size:
class VariableBatchSizeLR(LRScheduler):
    # An LR scheduler wrapper that scales LR based on the realized batch size.

    @property
    def optimizer(self):
        return self.base_lr_scheduler.optimizer

    def __init__(self, lr_scheduler, base_batch_size, batch_sizes, dataloader,
                 lr_scaling_method="linear", last_epoch=-1, verbose=False):
        self.batch_sizes = batch_sizes
        self.base_batch_size = base_batch_size
        self.lr_scaling_method = lr_scaling_method
        self.dataloader = dataloader
        self.base_lr_scheduler = lr_scheduler
        self.base_lrs = self.base_lr_scheduler.get_lr()
        self.last_epoch = last_epoch
        self.verbose = verbose
        self.step(0)

    # [...]

    def step(self, epoch=None):
        # call the base scheduler's step method to get LR for next epoch
        # Note: optimizer.step() precedes lr_scheduler.step(), so:
        # init: lr_scheduler.step(0) --> set LR for epoch 0
        # epoch 0: optimizer.step(); lr_scheduler.step(1) --> set LR for epoch 1
        # epoch 1: optimizer.step(); lr_scheduler.step(2) --> set LR for epoch 2

        # reset unscaled LRs (to the base scheduler's values) for the current epoch
        # Note: epoch==0: reset LR scheduler; epoch==None: scale LR for next epoch;
        unscaled_lrs = self.base_lrs if epoch == 0 else self.get_last_lr()
        for group, lr in zip(self.base_lr_scheduler.optimizer.param_groups, unscaled_lrs):
            group['lr'] = lr

        self.base_lr_scheduler.step(epoch)

        # scale the learning rate for the next epoch for each parameter group
        self.last_epoch = self.last_epoch + 1 if epoch is None else epoch
        batch_size = self.batch_sizes[self.last_epoch % len(self.batch_sizes)]
        for group in self.base_lr_scheduler.optimizer.param_groups:
            group['lr'] = scale_lr(self.base_batch_size, batch_size, group['lr'], self.lr_scaling_method)
Then, the adaptive batch size is implemented as a data loader with a collate function that packs samples into token-budgeted micro-batches, whose sample ids (microbatch_ids) are computed beforehand. When the micro-batches of a batch must have the same sequence length, as in pipeline parallelism, it also pads the samples to the longest sequence of their batch (batch_max_seqlens):
def dataloader_for_variable_batch_size(dataset, microbatch_ids, batch_max_seqlens,
    dataloader_rank=0, dataloader_batch_size=1, dataloader_num_replicas=1,
    dataloader_collate_fn=None, dataloader_num_workers=2, dataloader_pin_memory=False,
    required_microbatches_of_same_seqlen=False, sample_padding_fn=None,
):

    # Equidistantly distribute the microbatches across replicas (interleaved).
    sampler = DistributedSampler(
        dataset=microbatch_ids,
        num_replicas=dataloader_num_replicas,
        rank=dataloader_rank,
        shuffle=False,
        drop_last=False,
    )

    # Wrap the user-defined collate function to handle variable-batch packing.
    def collate_fn_wrapper(list_microbatch_ids):
        # Each batch element is a list of sample ids that fills up to max tokens.
        # We return the collated batch over all dataset samples referenced in the microbatches.
        batch = []
        for batch_id, microbatch_ids in list_microbatch_ids:
            batch_data = [dataset[idx] for idx in microbatch_ids]
            if required_microbatches_of_same_seqlen:
                assert sample_padding_fn is not None,                     "sample_padding_fn must be provided if required_microbatches_of_same_seqlen is True"
                pad_len = batch_max_seqlens[batch_id]
                batch_data = [sample_padding_fn(sample, pad_len) for sample in batch_data]
            batch += batch_data
        return dataloader_collate_fn(batch) if dataloader_collate_fn else batch

    return DataLoader(
        dataset=microbatch_ids,
        batch_size=dataloader_batch_size,
        sampler=sampler,
        num_workers=dataloader_num_workers,
        collate_fn=collate_fn_wrapper,
        pin_memory=dataloader_pin_memory,
    )
A complete example can be found in DeepSpeed PR 7104.
Kernel compilation and static shapes
Static shapes are important on GPUs because they maximize the execution speed: they remove runtime overheads and allow compilers to optimize the memory and compute kernels. With static shapes, memory is allocated in advance, without fragmentation, and each kernel keeps a fixed signature, i.e., one function definition for a given size, without the overhead of managing dynamic shapes. Static shapes also allow loop unrolling and CUDA graphs, which speed up small models by removing the overhead of launching their many small kernels, and they avoid recompilations in just-in-time compilers, such as that of PyTorch.
Just-in-time compilation of ML kernels via torch.compile can lead to substantial speedups. TorchDynamo captures the PyTorch operations of the model into a graph, AOTAutograd derives the graph of the backward pass, and TorchInductor fuses the operations of these graphs into fewer kernels, written in Triton on GPUs. With dynamic=False, these graphs and kernels are specialized to the shapes they see, so a new batch size or sequence length triggers a new compilation. PyTorch provides limited support for compiling variable-shaped tensors via torch.compile(dynamic=True).
Static compilation is ideal, but how to make it work with variable shapes? A practical approach is to ensure that each rank executes at least one forward+backward pass for every shape it will see later, near the beginning of training, so that the compiler can generate (and cache) a binary per shape. The idea is illustrated below:
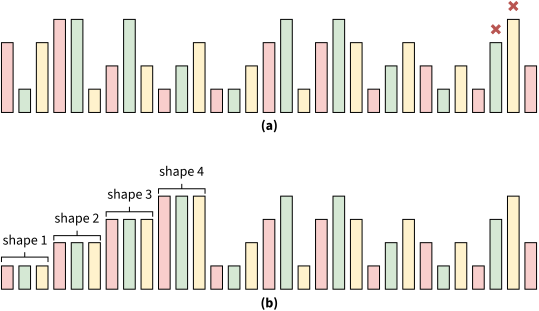
Dataset setup that allows static compilation for variable-length training on 3 processes. Top (a): original dataset of 31 samples (bars) of 4 different lengths (bar heights), with the default interleaved assignment to the processes (color-coded). The green and yellow ranks encounter a new shape later in training (red cross). This triggers a recompilation and, depending on the settings, possibly a runtime failure. Bottom (b): after reshuffling, each rank sees one sample of each shape (shapes 1 to 4) early on. One binary is compiled per shape, and no recompilation happens afterwards.
Compilation behavior can be inspected by setting TORCH_LOGS=recompiles, which logs a recompilation whenever a new length appears, e.g., 20 after 10:
Recompiling function forward in train.py:145 triggered by the following guard failure(s):
    - tensor 'L['timestep']' size mismatch at index 0. expected 10, actual 20
Note that each new shape produces a compiled variant that consumes memory, and many shapes can lead to out-of-memory (OOM) issues. Also, torch.compile keeps at most torch._dynamo.config.cache_size_limit compiled variants of a function (8 by default), and runs any further shape without compilation. Two practical mitigations are:
- Pad/bucket lengths to reduce the number of distinct shapes.
- Order inputs by size and call
torch.compiler.reset()after a set of compilations to free cached variants that will not be needed again.
Compiled graphs on single- vs multi-process runs
The graphs of torch.compile also affect how multi-GPU runs overlap communication with computation. Consider first a feed-forward network with 3 linear layers and 3 activations on a single GPU. The data loading, forward pass, backward pass, and optimizer step can be illustrated as:
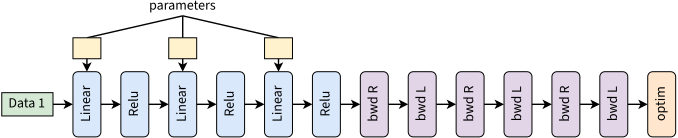
Adapted from: TorchDynamo Update 9: Making DDP Work with TorchDynamo
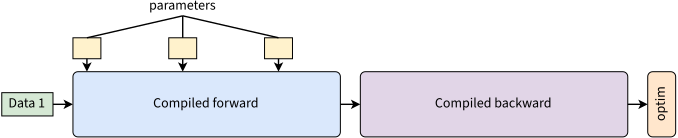
In this example, the GPU executes many separate kernels in the forward and backward passes. The following picture illustrates the same iteration with a compiled model, where the forward and the backward passes each run as one compiled graph:
Now consider a 2-GPU DDP run. During backpropagation, DDP performs all_reduce operations to synchronize gradients across ranks. The gradients of the last layers, which are computed first, can be reduced while the gradients of the earlier layers are still being computed, as illustrated below:
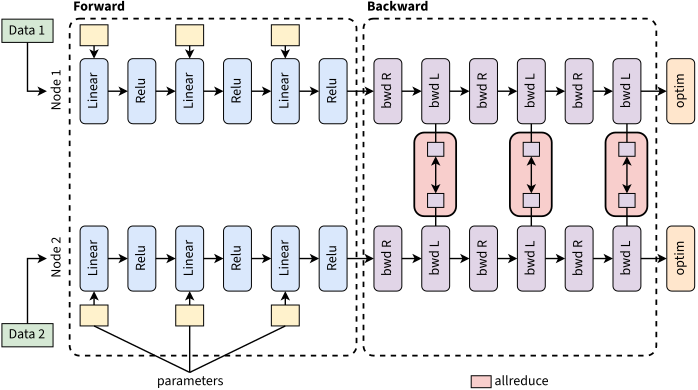
DDP execution workflow on 2 GPUs. The optimizer waits for all asynchronous all_reduces of gradients to finish.
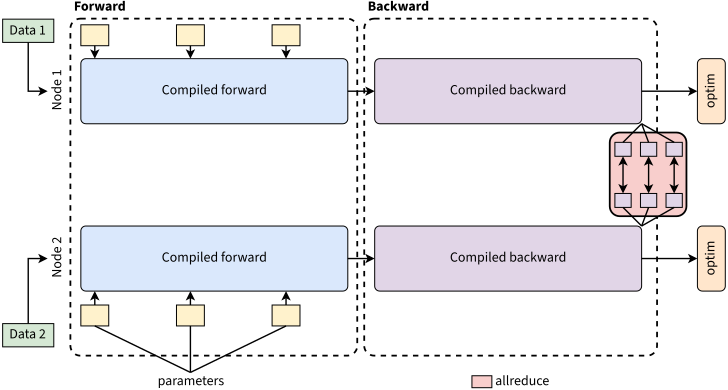
In a compiled setting, intermediate communication steps can introduce graph breaks, i.e., points where the compiler splits the model into several graphs. One naïve option is to compile a large graph and run the all_reduces only at the end, but that reduces overlap and increases the time the optimizer waits:
PyTorch’s DDPOptimizer addresses this by compiling around graph breaks into subgraphs and triggering asynchronous synchronization at subgraph boundaries:
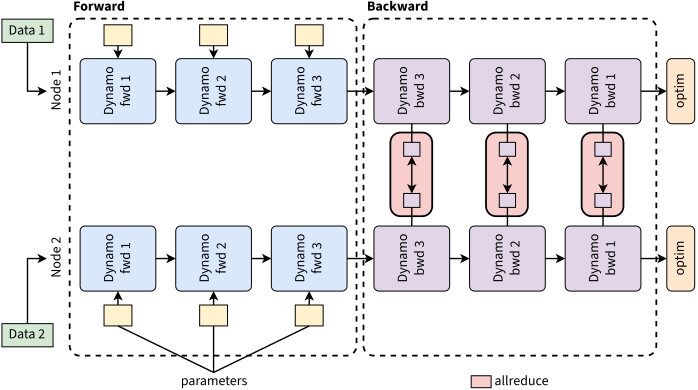
Note that the subgraph boundaries follow the DDP gradient buckets, which are built from the parameter sizes, so they do not change with input shapes. In the author’s tests, DeepSpeed ZeRO-0 (i.e., with ZeRO sharding disabled) did not achieve the speedups of PyTorch DDP, possibly for lack of an equivalent of DDPOptimizer.
Kernel compilation and CUDA graphs
The graphs of torch.compile describe the computation, but the CPU still launches their kernels one by one. CUDA graphs remove this launch overhead: they record a sequence of kernels once, with their launch parameters and memory addresses, and replay it entirely on the GPU with a single launch from the CPU. They do not optimize the kernels themselves, so they help little when large kernels keep the GPU busy.
Compilation via torch.compile uses a mode that controls optimization aggressiveness. The modes reduce-overhead and max-autotune capture the compiled kernels in a CUDA graph. As a CUDA graph replays its kernels on fixed shapes and memory addresses, each new shape needs a new graph, even with dynamic=True. Padding or bucketing the lengths, as above, thus also limits the number of CUDA graphs.
Also, CUDA graphs can increase memory usage, and the subgraphs of DDPOptimizer, each with its own CUDA graph, add to it, so DDP runs often turn CUDA graphs off. Finally, arguments like the following are passed to torch.compile for static compilation, with CUDA graphs on single-GPU runs only:
world_size = torch.distributed.get_world_size()
mode = "max-autotune" if world_size == 1 else "max-autotune-no-cudagraphs"  # single vs multi-GPU
dynamic = False  # force static compilation
model = torch.compile(model, backend="inductor", mode=mode, dynamic=dynamic)