Data parallelism, sharding and CPU offloading
Data parallelism trains a model on several GPUs, each with a full copy of the model and a different part of the batch. Sharding removes these redundant copies, and CPU offloading and activation checkpointing reduce the memory that is left.
Data parallelism
Data parallelism refers to the parallel execution of different input samples across processors. Consider any data input of shape \(B \times S \times E\) (batch size, sequence/temporal size and embedding/feature size): data parallelism refers to the use case where the data is split across \(P\) processes along the batch dimension, leading to a local input of shape \(B/P \times S \times E\):
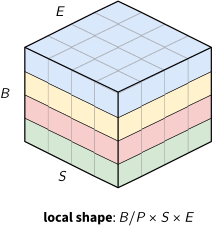
There are two main data parallelism approaches, which differ in what each process stores: a full copy of the model, or only a part of it.
Distributed Data Parallel (DDP)
Distributed Data Parallel (DDP) keeps a full copy of the model (weights, optimizer states and gradients) on each processor. All copies are initialized equally. Each processor takes a different mini-batch as input and performs a forward pass to compute the loss of that batch.
On the backward pass, at every layer of the model, all processes compute the gradients of their batch and perform an all-reduce to get the mean gradients across all processors. These are then used to update the parameters and the optimizer states. Because parameters are initialized equally, gradients are mean-reduced and all processes perform the same updates, the models across all processors are kept in an identical state throughout the execution. The following diagram illustrates this workflow:
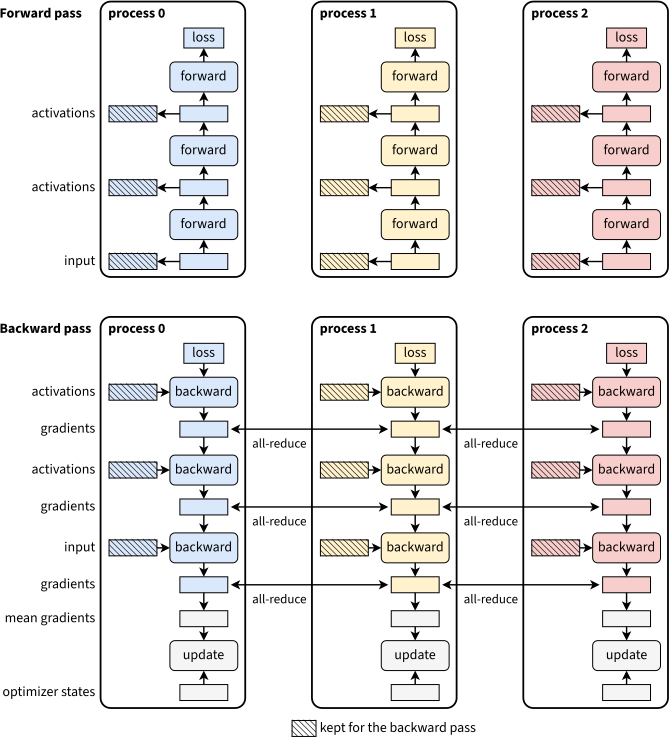
Distributed data parallelism (DDP) on 3 processes, each holding a full copy of a 3-layer model and taking its own input. The forward pass computes the activations and the loss of each process with no communication, and keeps the input and the activations for the backward pass. In the backward pass, an all-reduce averages the gradients of each layer across the processes, so that every process applies the same update to its copy (grey: identical on all processes).
The backward pass overlaps computation and communication: it computes the gradients of some layers while the gradients of other layers are sent across the network, which hides the communication latency behind the computation. This is possible because the gradients of a layer are final as soon as the backward pass leaves that layer, while the layers before it are still being computed.
The diagram above shows that each processor holds a copy of the model, so the model states (the parameters, gradients and optimizer states) are stored \(P\) times, which leads to superfluous memory usage. That is where sharding comes into play.
Sharding with FSDP and ZeRO
Fully Sharded Data Parallel (FSDP), a.k.a. sharding, is a distributed setup where processors do not hold a full copy of the model, but only a part (a shard) of its parameters, optimizer states and gradients, e.g. those of a subset of layers. As before, each processor takes a different mini-batch as input.
In the terminology of DeepSpeed, a library built on PyTorch, sharding goes by the name of ZeRO (Zero Redundancy Optimizer), introduced in the paper ZeRO: Memory Optimizations Toward Training Trillion Parameter Models. ZeRO has several alternative execution modes (stages). Each stage represents a different level of memory redundancy, corresponding to different variable types being distributed or replicated across processes:
- ZeRO stage 0: no sharding of any variables, equivalent to DDP.
- ZeRO stage 1 (ZeRO-1): the optimizer states (e.g., for Adam in mixed precision, an FP32 copy of the weights and the first and second moment estimates) are partitioned across the processes, so that each process updates only its part of the parameters. The forward pass does not change.
- ZeRO stage 2 (ZeRO-2): the gradients used to update the model weights are also partitioned, so that each process retains only the gradients corresponding to its portion of the optimizer states. The forward pass does not change either.
- ZeRO stage 3 (ZeRO-3): the model parameters are also partitioned across the processes. Adds a communication overhead to both the forward and backward passes.
An important remark is that activations are not sharded, i.e. they are kept in full shape on each processor. In modern models, a huge chunk of memory is allocated to the residual states, as the ZeRO paper calls them (activations, temporary buffers, fragmented memory, buffers of normalization layers, etc.), which FSDP does not shard. With that in mind, the following diagram illustrates the workflow of stage 3 sharding (of parameters, gradients and optimizer states):
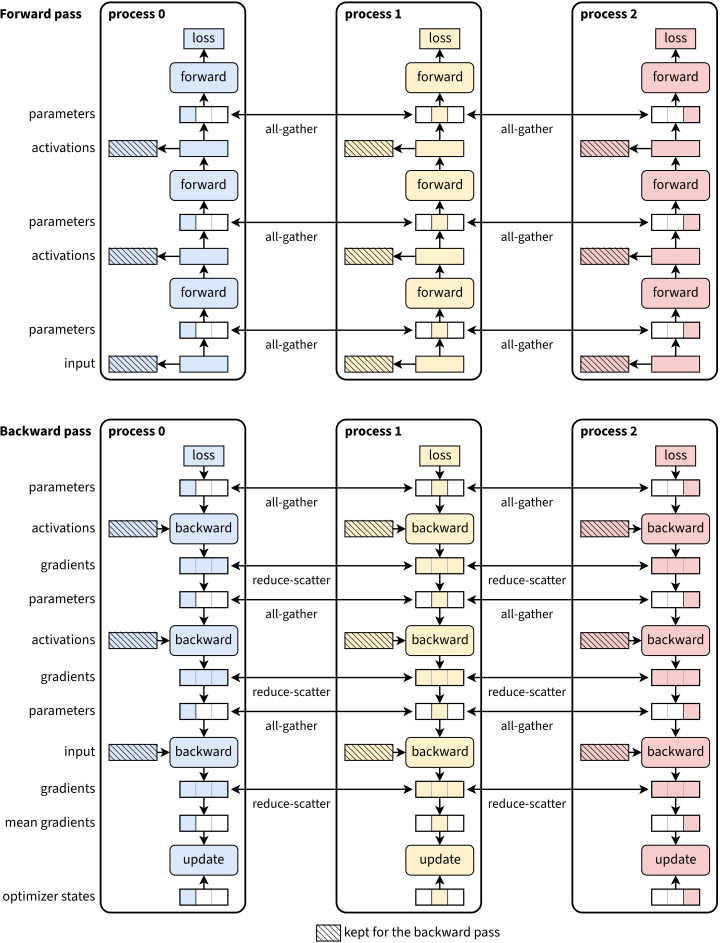
Stage 3 sharding (ZeRO-3) on 3 processes. Each process holds one third of the parameters, gradients and optimizer states of every layer (in its color; the white cells are held by the other processes). It takes its own input, and keeps the input and its activations for the backward pass. The processes all-gather the parameters of each layer before computing it, in the forward and in the backward pass. In the backward pass, a reduce-scatter averages the gradients of each layer and leaves each process the mean gradients of its third, which it updates with its optimizer states. Inspired by: ZeRO: Memory Optimizations Toward Training Trillion Parameter Models
Instead of a single all-reduce of the gradients, sharding uses two collective operations. The all-gather temporarily brings together the shards of the parameters, so that each process rebuilds the full weights of the layer it computes, in the forward and in the backward pass. The reduce-scatter, in the backward pass, sums the gradients across all processes and scatters the result, so that each process only stores and updates the gradient shard of its optimizer states. Note that DeepSpeed ZeRO-3 and PyTorch FSDP split the parameters of every layer into \(P\) shards, one per process.
Memory and communication of the ZeRO stages
With mixed-precision Adam, each parameter takes 16 bytes of model states: 2 bytes for its FP16 weight, 2 for its FP16 gradient, and 12 for its optimizer states (an FP32 copy of the weight and the two moments of Adam). On a large number of processes, ZeRO-1 keeps a single copy of the optimizer states, split across the processes, which cuts this memory about 4 times. ZeRO-2 also keeps a single copy of the gradients (about 8 times), and ZeRO-3 a single copy of the parameters too, which divides the memory by the number of processes. The savings are not free. ZeRO-1 and ZeRO-2 communicate as much as DDP: an all-reduce is a reduce-scatter followed by an all-gather, and they run these two collectives on the gradients and on the updated parameters (ZeRO paper, section 7). ZeRO-3 communicates 1.5 times as much, as it gathers the parameters in both the forward and the backward passes.
CPU offloading
Sometimes the model is so big that, even with sharding, it does not fit in the memory of the GPUs. A common technique to handle such memory limitations is CPU offloading, also referred to as virtualized Deep Neural Networks by vDNN (Rhu et al.) and vDNN+ (Shriram et al.).
The main goal of this method is to iteratively move to the GPU only the portions of activations and model that are required for the current and next computation steps. Previously processed layers are moved from GPU to CPU, while upcoming layers are moved from CPU to GPU. vDNN offloads only the activations (the feature maps), as they take most of the GPU memory of convolutional neural networks.
This is possible because the loss (and its derivative) can be written as a composition of the functions of the layers, e.g. for the mean absolute error (MAE):
\[\mathcal{L} = \frac{1}{N} \sum_{n=1}^N | y_n - f^{(L+1)} \circ ... \circ f^{(2)} \circ f^{(1)} (x_n^{(0)}) |\]where \(f^{(l)}\) is the function implemented by layer \(l\), \(L\) is the number of hidden layers, \(y\) is the ground truth, \(x_n^{(0)}\) is the input of sample \(n\) and \(N\) is the number of samples.
The important concept here is the composition of the functions \(f\) across layers. The computation of a layer needs only its weights, its input and its output (and, in the backward pass, the gradient coming from the next layer), so the data of all other layers can be kept in CPU memory.
To reduce the time spent waiting to push (pull) a layer to (from) the GPU, the computation of the current layers can be overlapped with the communication of the upcoming ones. This overlap matters, as the link between the CPU and the GPU is tens of times slower than the memory of the GPU. The following picture illustrates vDNN on 3 layers:
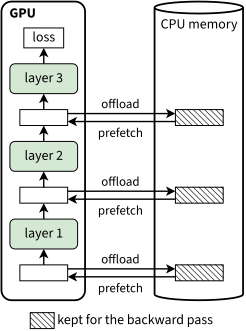
CPU offloading in vDNN. The input of each layer is offloaded to the CPU memory during its forward pass, and prefetched back to the GPU before its backward pass. Inspired by: vDNN: Virtualized Deep Neural Networks for Scalable, Memory-Efficient Neural Network Design
Activation checkpointing
ZeRO and FSDP shard the model states, but not the activations that the backward pass needs, which grow with the batch size and the sequence length. Activation checkpointing (or gradient checkpointing) trades computation for this memory. Instead of storing the output of every layer for the backward pass, only a few layers (the checkpoints) keep their inputs. The backward pass then computes the activations of the other layers again, with a forward pass from the closest checkpoint. The following picture illustrates activation checkpointing on 4 layers, with a checkpoint every 2 layers:
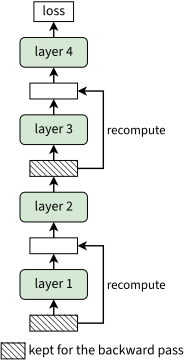
The paper Training Deep Nets with Sublinear Memory Cost showed that checkpointing an \(n\)-layer network every \(\sqrt{n}\) layers stores \(O(\sqrt{n})\) activations instead of \(O(n)\), for the cost of one extra forward pass per mini-batch. As the backward pass takes about twice as long as the forward pass, this is about a third more computation. In practice, the memory freed allows larger batches, longer sequences or a lower ZeRO stage, which recover part of that cost. With ZeRO-3, it also adds communication: the recomputation of a layer all-gathers its parameters, and the backward pass of the layer gathers them again if they were released in between.
PyTorch implements it in torch.utils.checkpoint, in two versions, and recommends the non-reentrant one (use_reentrant=False). Through saved tensor hooks, it keeps a reference instead of each activation of a checkpointed function, and computes the activations again when the backward pass needs them, stopping as soon as these are ready. The reentrant version runs the function without recording its graph, and repeats it in full in the backward pass, inside a custom autograd function with a graph of its own. It only supports backward(), not torch.autograd.grad, and at least one input of the function must require gradients, or its part of the model gets no gradients.
PyTorch implementation
PyTorch implements data parallelism in two wrappers of a model: DistributedDataParallel (DDP) and FullyShardedDataParallel (FSDP). The sharding_strategy of FSDP plays the role of the ZeRO stage: NO_SHARD replicates all variables as DDP does, SHARD_GRAD_OP shards the gradients and optimizer states as ZeRO-2, and FULL_SHARD (the default) also shards the parameters, as ZeRO-3. The PyTorch DDP paper describes how DDP overlaps communication and computation: it groups the gradients into buckets of 25 MiB (bucket_cap_mb), and all-reduces each bucket as soon as its gradients are computed, while the backward pass goes on.
To show what FSDP does under the hood, this section implements ZeRO-3 by hand, on a multi-layer perceptron (MLP) with the forward and backward passes of the post on backpropagation, without biases. Each process keeps \(1/P\) of the rows of the weights \(W\) of each layer. In the forward pass, each layer all-gathers its full weights, computes its output \(XW\), and frees the weights before the next layer gathers its own. In the backward pass, each layer gathers its weights again to compute the gradient of its input, \(\delta W^T\), where \(\delta\) is the gradient of its output. A reduce-scatter then sums the gradients of the weights, \(X^T \delta\), across the processes, and leaves each process with the rows of its own shard.
First, all_gather() rebuilds the full weights of a layer from the shards of all processes:
import torch
import torch.distributed as dist

def all_gather(shard):
  W = shard.new_empty(shard.shape[0] * dist.get_world_size(), shard.shape[1])
  dist.all_gather_into_tensor(W, shard)  # the shards of all processes, in rank order
  return W
Then, the MLP keeps only its shards. Its forward() gathers the weights of each layer just before using them, and its backward() gathers them again, from the last layer to the first, and reduce-scatters their gradients:
class MLP:

  def __init__(self, sizes):
    rank, P = dist.get_rank(), dist.get_world_size()
    self.shards = []  # the rows of the weights of each layer that this process keeps
    for n_in, n_out in zip(sizes[:-1], sizes[1:]):
      W = torch.randn(n_in, n_out, device="cuda")
      self.shards.append(W.chunk(P)[rank].clone())

  def forward(self, x):
    self.x = []  # the input of each layer, saved for the backward pass
    for l, shard in enumerate(self.shards):
      W = all_gather(shard)  # gather the full weights of layer l
      self.x.append(x)
      x = x @ W
      del W  # free them before the next layer gathers its own
      if l < len(self.shards) - 1:
        x = torch.relu(x)
    return x

  def backward(self, delta):
    self.grads = [None] * len(self.shards)
    for l in reversed(range(len(self.shards))):
      W = all_gather(self.shards[l])  # gather the full weights of layer l again
      dW = self.x[l].T @ delta  # gradient of the full weights, on the local samples
      delta = delta @ W.T  # gradient of the input of layer l
      del W
      if l > 0:
        delta = delta * (self.x[l] > 0)  # derivative of the ReLU before layer l
      grad = torch.empty_like(self.shards[l])
      dist.reduce_scatter_tensor(grad, dW)  # sum over processes, keep this shard
      self.grads[l] = grad / dist.get_world_size()  # mean over processes, as in DDP
    return delta
Note that the MLP saves only the input of each layer for the backward pass, never the full weights, and that the division by \(P\) averages the gradients across the processes, as DDP does. A training step calls forward(), computes the gradient of the loss with respect to the output, passes it to backward(), and updates each shard with its gradient (e.g. shard -= lr * grad with SGD). Each process thus keeps and updates only its shard of the weights, gradients and optimizer states, as in ZeRO-3. FSDP also overlaps the all-gather of the weights of a layer with the computation of the previous one (prefetching), which this example leaves out for simplicity.
Finally, the application is launched with torchrun, which spawns one process per GPU on each node and sets the environment variables that identify each process (RANK, LOCAL_RANK and WORLD_SIZE). dist.init_process_group() reads them to connect the processes, and torch.cuda.set_device(local_rank) gives each process its own GPU. A DistributedSampler in the DataLoader gives each process different samples. The usage is simple:
$ torchrun --standalone --nproc_per_node=4 train.py
where nproc_per_node is the number of GPUs on each node.
Model and dataset setup
The DeepSpeed implementation trains the GPTlite model of the previous post, with specs matching the GPT-3 Small model in Language Models are Few-Shot Learners (Table 2.1):
n_layer = 12   # depth of the network as number of decoder blocks.
n_embd = 768   # size of the embeddings (d_model)
n_head = 12   # number of attention heads in the Multi-Attention mechanism
block_size = 2048   # block size, i.e. the maximum sequence length, the n_ctx in the paper
dropout = 0.1   # dropout rate (variable p) for dropout units
It then defines the methods get_model() and get_dataset() that return the model and the tiny shakespeare dataset:
## gptlite.py

def get_dataset():

  class GPTliteDataset(torch.utils.data.Dataset):

      def __init__(self, train_data, block_size):
        self.train_data = train_data
        self.block_size = block_size

      def __len__(self):
        return len(self.train_data)

      def __getitem__(self, idx):
        # generate 1 random offset on the data
        ix = torch.randint(len(self.train_data)-self.block_size , size=())
        # input is a random subset of tokens
        x = self.train_data[ix   : ix+self.block_size]
        # target is just x shifted right (ie the next predicted word)
        y = self.train_data[ix+1 : ix+1+self.block_size]
        return x, y

  train_data, valid_data, vocab_size = load_tiny_shakespeare_data()
  train_dataset = GPTliteDataset(train_data, block_size)
  valid_dataset = GPTliteDataset(valid_data, block_size)
  return train_dataset, valid_dataset, vocab_size


def get_model(vocab_size):
  return GPTlite(vocab_size)
This code applies to any model of type torch.nn.Module and any dataset of type torch.utils.data.Dataset.
DeepSpeed Data Parallelism, sharding and optimizations
Porting existing code to DeepSpeed is pretty simple. To start, DeepSpeed features can be activated via the DeepSpeed API or its Configuration JSON. The number of possible optimizations is large, as the config can define parallelism, floating-point precision, logging, communication parameters, etc.
This implementation starts with a simple config file. The file configures the DeepSpeed logger to output memory and throughput info every 10 steps (steps_per_print), sets the batch size to 256 and (optionally) defines the settings of the optimizer (optimizer) and learning rate scheduler (scheduler):
{
  "train_batch_size": 256,
  "steps_per_print": 10,
  "optimizer": {
    "type": "AdamW",
    "params": { "lr": 0.001, "betas": [ 0.8, 0.999  ], "eps": 1e-8, "weight_decay": 3e-7 }
  },
  "scheduler": {
    "type": "WarmupLR",
    "params": { "warmup_min_lr": 0, "warmup_max_lr": 0.001, "warmup_num_steps": 1000 }
  }
}
Note that, in DeepSpeed terminology, train_micro_batch_size_per_gpu refers to the batch size loaded per dataloader (i.e. per GPU, per gradient accumulation step), while train_batch_size refers to the batch size across all gradient accumulation steps and processes in the network, i.e.:
train_batch_size = train_micro_batch_size_per_gpu * num_gpus * num_nodes * gradient_accumulation_steps
Therefore, as train_batch_size is already set, gradient accumulation can be enabled by setting train_micro_batch_size_per_gpu, or gradient_accumulation_steps (1 by default). Gradient accumulation, also known as micro-batching, simulates a large mini-batch as an iteration across several micro-batches: each micro-batch runs a forward and a backward pass, its gradients are added to those of the previous ones, and the optimizer updates the parameters once, after the last micro-batch. It is particularly relevant when the whole mini-batch does not fit into memory. The following picture illustrates gradient accumulation with 3 micro-batches:
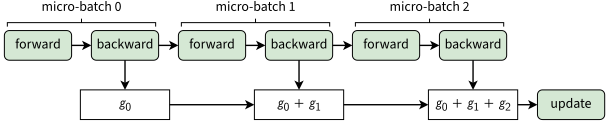
The configs of this post use a micro-batch of 1 sample per GPU, which accumulates up to the batch of 256 samples across the 8 GPUs in \(256 / (1 \times 8) = 32\) gradient accumulation steps, the value that engine.gradient_accumulation_steps() returns at runtime:
{
  "train_batch_size": 256,
  "train_micro_batch_size_per_gpu": 1
}
Sharding with ZeRO is enabled by setting its stage in the config file. If omitted, or when passing stage 0, ZeRO is disabled and the execution follows a regular distributed data parallel workflow:
{
  "zero_optimization": { "stage": 3 }
}
CPU offloading in DeepSpeed is called ZeRO-Offload, introduced in the ZeRO-Offload paper: it offloads the optimizer states and the gradients to the CPU memory, and runs the optimizer step on the CPU. On top of stage 3, ZeRO-Infinity, also an offloading engine, extends ZeRO-Offload with the offloading of the parameters and with support for NVMe memory. They are enabled with the entries offload_optimizer and offload_param, where pin_memory places the offloaded data in pinned (page-locked) CPU memory, from which the GPU copies data faster and asynchronously:
{
  "zero_optimization": {
    "stage": 3,
    "offload_optimizer": { "device": "cpu", "pin_memory": true },
    "offload_param": { "device": "cpu", "pin_memory": true }
  }
}
Almost everything is ready now. Once the config file is properly calibrated, the implementation is straightforward. All boilerplate that PyTorch requires for parallelism and data loaders is managed internally by DeepSpeed, so the code only needs to set up DeepSpeed as:
def main_deepspeed(n_epochs=100, random_seed=42):

  torch.manual_seed(random_seed)  #set random seed (used by DataLoader)
  deepspeed.runtime.utils.set_random_seed(random_seed) #set DeepSpeed seed
  deepspeed.init_distributed()  # initialize distributed DeepSpeed
  config = 'ds_config.json'  # load the DeepSpeed config
  criterion = torch.nn.CrossEntropyLoss()  # initialize loss function
  train_dataset, _, vocab_size = gptlite.get_dataset()  # initialize GPTlite dataset
  model = gptlite.get_model(vocab_size)  # initialize GPTlite model

  engine, optimizer, train_dataloader , _ = deepspeed.initialize(
    config=config, model=model, training_data=train_dataset,) # initialize deepspeed
The training loop is then written as a regular PyTorch training loop, with the engine in place of the model and the optimizer. The gradients are not zeroed, as DeepSpeed does it internally. Also, initialize() already returns a train_dataloader that assigns disjoint subsets of data to each process, so there is no need to fiddle with distributed dataloaders and samplers.
  for epoch in range(n_epochs):
    for step, data in enumerate(train_dataloader):
      inputs = data[0].to(engine.device)
      labels = data[1].to(engine.device)

      outputs = engine(inputs)  # fwd pass
      loss = criterion(outputs, labels)
      engine.backward(loss)  # backprop
      engine.step()  # update weights, no need for zero-ing
Finally, the run is launched with the torchrun launcher as before, or with the launcher included in DeepSpeed as:
$ deepspeed --num_gpus=8 train.py --deepspeed --deepspeed_config ds_config.json
DeepSpeed also offers several options that save memory or communication, and estimators of the memory that each ZeRO stage needs.
Mixed precision. Mixed precision training stores the parameters, activations and gradients in a 16-bit format, and keeps an FP32 copy of the weights for the optimizer step, which is part of the 12 bytes of optimizer states counted above. It reduces the memory of the activations and the compute time. In FP16, small gradients underflow to zero, so the loss is multiplied by a scale factor before the backward pass (loss scaling), and the gradients are divided by it before the optimizer step. With "loss_scale": 0, DeepSpeed adjusts this factor dynamically, starting from \(2^{16}\) (initial_scale_power):
{
  "fp16": { "enabled": true, "loss_scale": 0, "initial_scale_power": 16 }
}
BF16 has the 8 exponent bits of FP32, against the 5 of FP16, so it has the range of FP32 and needs no loss scaling. When the hardware supports it, BF16 should be used instead, with "bf16": {"enabled": true}, which cannot be combined with fp16. Recent GPUs also multiply in FP8 and FP4, which need a scale per tensor or per block of values: Perez et al. scale each FP8 tensor by its absolute maximum, and NVFP4, used to pre-train Nemotron 3 Super, gives each block of 16 values its own scale.
Communication buffers and overlap. Each collective that reduces the gradients or gathers the parameters needs buffers for the data that it sends and receives. By default, DeepSpeed reduces the gradients in buckets of 5e8 elements, i.e. 1 GB for 16-bit values. ZeRO-1 and ZeRO-2 gather the updated parameters in buckets of the same size, and ZeRO-3 prefetches the parameters in buckets of 5e7 elements. Smaller buckets need less memory, but split each collective into several smaller ones, which use the network less efficiently. The configs of this post use buckets of 5e4 elements, and overlap the reduction of the gradients with the backward pass (overlap_comm):
{
  "zero_optimization": {
    "reduce_bucket_size": 5e4,
    "allgather_bucket_size": 5e4,
    "stage3_prefetch_bucket_size": 5e4,
    "overlap_comm": true
  }
}
Communication quantization (ZeRO++). ZeRO++ cuts the communication of ZeRO-3 between nodes 4 times, with three methods. The all-gather of the forward pass sends the weights in INT8 instead of FP16, quantized by blocks, each with its own scale (qwZ). Each node keeps a copy of the weights, sharded across its GPUs, so that the all-gather of the backward pass runs inside the node, over its faster links (hpZ). Finally, the reduce-scatter of the gradients becomes an all-to-all of gradients quantized to INT4, which are dequantized before they are summed, to keep the accuracy (qgZ). ZeRO++ suits slow networks between nodes and small batches per GPU, whose computation is too short to hide the communication, at the cost of the memory of the copy of hpZ. As in the ZeRO++ tutorial, zero_hpz_partition_size is ideally the number of GPUs per node, and its default, 1, disables hpZ:
{
  "zero_optimization": {
    "zero_hpz_partition_size": 8,
    "zero_quantized_weights": true,
    "zero_quantized_gradients": true
  }
}
Activation checkpointing. The layers to checkpoint are wrapped with deepspeed.checkpointing.checkpoint, the reentrant version described above, or with deepspeed.checkpointing.non_reentrant_checkpoint. For simplicity, the forward() of GPTlite iterates over its layers with to_layers(), and checkpoints one layer in every activation_checkpoint_interval, given by the command line argument --activation_checkpoint_interval (0 disables it):
## gptlite.py

class GPTlite(nn.Module):
  #...

  def forward(self, idx, targets=None):

    if self.activation_checkpoint_interval > 0:
      x=idx
      for l, layer in enumerate(self.to_layers()):
        is_checkpoint = l % self.activation_checkpoint_interval == 0
        x = deepspeed.checkpointing.checkpoint(layer, x) if is_checkpoint else layer(x)
      return x
Note that this scheme recomputes only the checkpointed layers, while the other layers keep all their activations, as without checkpointing. With ZeRO-3, DeepSpeed does not release a parameter that is reused within stage3_max_reuse_distance parameters (1e9 in the configs of this post), which avoids gathering it again for the recomputation, at the cost of memory. The benchmarks of this post run without activation checkpointing (run.sh sets the interval to 0).
Memory estimation. The DeepSpeed memory estimators give the memory of the model states per GPU with ZeRO-2 and ZeRO-3, with and without offloading. They are called at the start of the execution:
def measure_parameters_memory(model):
  param_size_GB = sum([p.nelement() * p.element_size() for p in model.parameters()])/1024**3
  print(f"Native model parameters size: {round(param_size_GB, 2)}GB.")

  from deepspeed.runtime.zero.stage_1_and_2 import estimate_zero2_model_states_mem_needs_all_live
  estimate_zero2_model_states_mem_needs_all_live(model, num_gpus_per_node=8, num_nodes=1)

  from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live
  estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=8, num_nodes=1)
The 86.7 million parameters of GPTlite take 0.323 GB in FP32. Per GPU, ZeRO-2 needs 0.484 GB without offloading and 0.161 GB with it, and ZeRO-3 needs 0.190 GB and 0.009 GB: with offloading, only the 16-bit parameters and gradients of the largest layer stay on the GPU, to compute it. These estimates are fast to compute, but count only the model states, with mixed-precision Adam, and ignore the activations, the temporary buffers and the communication buffers.
Results
To measure performance, the DeepSpeed logger was used to extract the following metrics from different runs every 10 steps: model throughput as the average number of samples per second, the average allocated memory, and the maximum allocated memory. The runs used pytorch==2.0.1, CUDA 11.7 and deepspeed==0.10.3.
All implementations use the same numerical precision, communication bucket sizes, and other config parameters, and none uses activation checkpointing. The following implementations (and configs) were benchmarked:
- The distributed data parallel (DDP) implementation, i.e. no DeepSpeed (
ds_config.jsonwith'stage': 0); - The fully-sharded data parallel implementation with ZeRO 1, 2 and 3 (
ds_config.jsonwith'stage' :1,2or3); - The ZeRO-3 implementation with ZeRO-Infinity for CPU offloading (
ds_config_offload.json).
The GPTlite model was tested with a micro-batch size of 1 sample per GPU, and the results are:
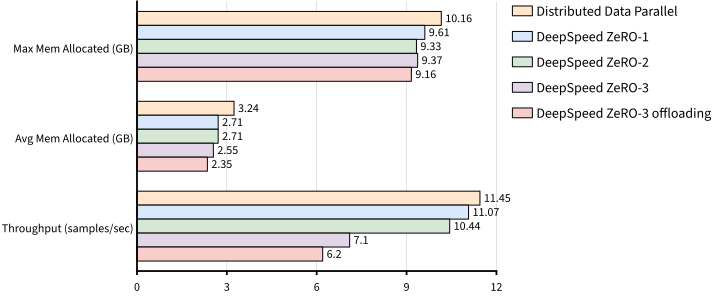
Memory overhead from communication buffers. Looking at the max vs average memory, note that, in theory, the max memory should be much higher at high ZeRO stages than at low ZeRO stages and DDP. This is because more parameters are communicated, which requires more communication buffers. However, setting the communication bucket sizes (the number of elements communicated at a time) to a low value in the config file overcomes this effect: the max memory stays between 9.16 GB and 10.16 GB in all runs, and it is lowest with ZeRO-3 and offloading. In fact, several runs were also benchmarked with the default communication bucket sizes (5e8), which led to higher memory usage, as expected (approximately double in stages 2 and 3), and became prohibitive for some runs.
Communication vs computation trade-off from different stages in ZeRO. As expected, as the execution moves from DDP to ZeRO-1, ZeRO-2, ZeRO-3 and ZeRO-Infinity, both the memory consumption and the throughput are reduced. Compared to DDP, ZeRO-1 and ZeRO-2 reduce the average memory by 16%, for 3% and 9% of the throughput, while ZeRO-3 reduces it by 21%, for 38% of the throughput. Data locality is traded for communication of parameters, and a price in performance is paid for the communication and offloading of parameters. In practice, the fastest choice is therefore the lowest stage that fits the model in memory.
Offloaded vs in-memory parameters. Offloading proved to be a consistent way to reduce memory usage, with the drawback of a reduction in throughput, as expected: compared to ZeRO-3 without offloading, it reduces the average memory by 8% and the throughput by 13%.
Lack of superlinear speedup. A small improvement in memory efficiency was observed, but still far from the claims of the original DeepSpeed team. One explanation is that a small network of 8 GPUs was used, compared to the 64 to 400 GPUs used by the authors in their benchmarks, so the memory reduction is much smaller. Moreover, most of the memory of a model as small as GPTlite is taken by its activations, which are not sharded: its model states take about 1.3 GB per GPU with DDP, out of a peak of 10 GB. A large network of GPUs also underlies their claim of superlinear speedup (with more GPUs, each GPU holds fewer model states and fits a larger batch, at a higher throughput), which was not observed here.
Finally, communication quantization (ZeRO++) was not used, as it did not result in any improvement. This is in line with the ZeRO++ paper, which claims this method is applicable to small batch sizes per GPU or low-bandwidth networks.
The code of all experiments is available in the distributed-ml repo.