Building a GPT model in PyTorch from scratch
In 2017, the Transformer model was presented in the paper Attention is all you need. It introduced a translation tool based on an attention mechanism that was not recurrent (unlike RNNs), but handled the dependency among tokens in a sequence by learning an attention matrix that exposed every token to all other tokens.
Like other translation methods, it had two main components: an encoder that learns the structure of the source language, and a decoder that learns the translation mechanism to the new language. The fundamental differences between the encoder and the decoder are the mask in the decoder’s attention matrix, and the cross-attention, through which the decoder attends to the output of the encoder. The mask hides the subsequent tokens of a sequence in the decoding phase, so that the guess of which token comes next is computed only from previous tokens.
It soon became clear that the Transformer had much more to offer and could be used with many data types (time series, images, etc.). Most importantly, its components could be stacked as a sequence of blocks to perform higher-level cognitive tasks. So much so that the Transformer is now the base model of most of the large and best-performing ML models. An example of such models is BERT, a stack of Transformer encoders used for regression and classification tasks.
This post dissects and details the implementation of a small language model, GPTlite, based on a stack of decoder-only modules, a la GPT-2, used for generating long sentences from a given input. A decoder-only model keeps the decoder of the transformer only, without the encoder and the cross-attention to its output. The following picture illustrates how this model is derived from the original transformer:
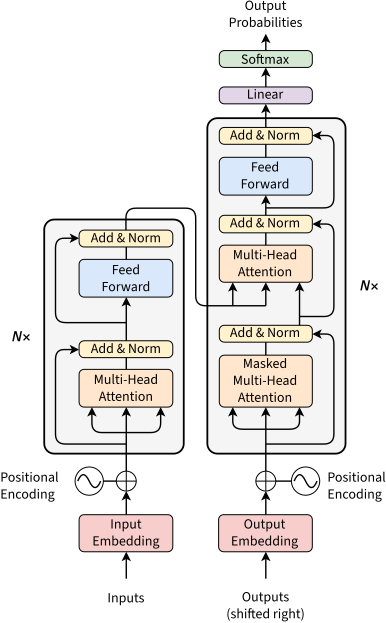
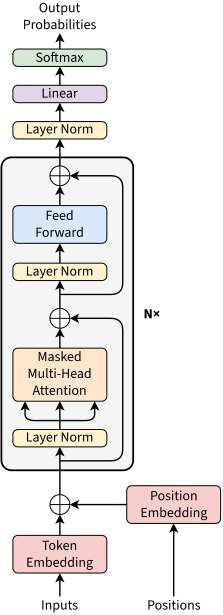
Left: the original transformer, with an encoder and a decoder. Right: the GPT decoder-only model detailed in this post: the decoder of the transformer without its cross-attention, with pre-norm blocks, a final layer normalization and a learned position embedding. Adapted from: Attention Is All You Need.
Hyperparameters
The basic imports and the ML hyperparameters are:
import torch
import torch.nn as nn
import torch.nn.functional as F

# set the random seed, for reproducibility
torch.manual_seed(42)

# device: where to execute computation
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")

# how often to do an evaluation step
eval_interval = 100

# number of training iterations
max_iters = 500

# optimizer's learning rate
learning_rate=1e-4

# minibatch size, how many inputs to 'pack' per iteration
batch_size = 3
and the ones specific to the GPT model are:
# block size is the maximum sequence length used as input.
# E.g. for block_size 4 and input ABCD, we have training samples A->B, AB->C, ABC->D, ABCD->E
block_size = 4

# size of the embeddings
n_embd = 16

# number of attention heads in the multi-head attention mechanism
n_head = 4

# depth of the network as number of decoder blocks (the Nx in the GPT decoder diagram).
# Each block contains a normalization, an attention and a feed forward unit
n_layer = 6

# dropout rate (variable p) for dropout units
dropout = 0.2
As the input dataset, this post uses the tiny shakespeare text. First, it is downloaded from a console:
$ wget https://raw.githubusercontent.com/karpathy/char-rnn/master/data/tinyshakespeare/input.txt
and then loaded in Python:
with open("input.txt") as f:
    text = f.read()
Tokenization
The first step is to map the input characters to a numerical representation of tokens. There are several possible tokenizers, the simplest being one that maps characters to integers directly:
# collect sorted list of input characters and create
# string-to-int (stoi) and int-to-string (itos) representations:
chars = sorted(list(set(text)))
stoi = { ch:i for i,ch in enumerate(chars) }
itos = { i:ch for i,ch in enumerate(chars) }

# define encode and decode functions that convert strings to arrays of tokens and vice-versa
encode = lambda x: torch.tensor([stoi[ch] for ch in x], dtype=torch.long) #encode text to integers
decode = lambda x: ''.join([itos[i] for i in x]) #decode integers to text
vocab_size = len(stoi)
The vocabulary size vocab_size is the number of distinct tokens. In this case, 65 characters:
!$&',-.3:;?ABCDEFGHIJKLMNOPQRSTUVWXYZabcdefghijklmnopqrstuvwxyz
, where the first character is the line break character \n and the second one is the space. Each token is then mapped to a vector of n_embd values by the token embedding, a table that is learned during training (created in the next section), as illustrated below:
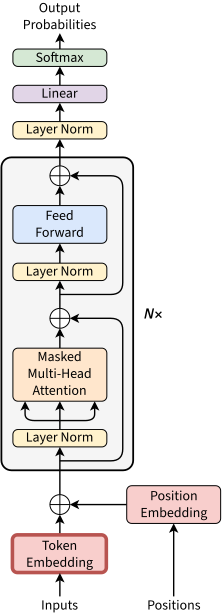
The token embedding module in the GPTlite model, emphasized in red. Adapted from: Attention Is All You Need.
For better context and shorter sequences, several characters can be packed into each token, instead of encoding one character per token, at the cost of a larger vocabulary and embedding table. For example, a token can encode entire words or subwords. Other existing tokenizers are Google’s sentencepiece, the word or subword tokenizers by Hugging Face, or the Byte-Pair Encoding (BPE) tiktoken used by OpenAI’s GPT:
import tiktoken
enc = tiktoken.encoding_for_model("gpt-4")
print(enc.n_vocab)
print(enc.encode("Hello world"))
print(enc.decode(enc.encode("Hello world")))
This would output the vocabulary size 100277, the encoding of "Hello world" as the tokens [9906, 1917], and its original string representation.
Positional Encodings
The position embedding is added to the token embedding before the first block, as illustrated below:
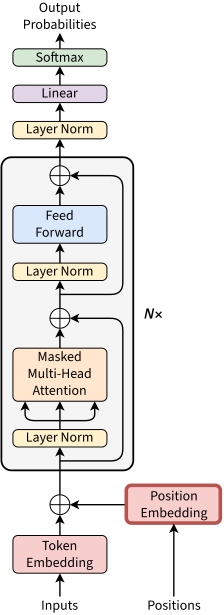
The position embedding module in the GPTlite model, emphasized in red. Adapted from: Attention Is All You Need.
The attention mechanism returns a set of vectors. Only by adding positional encodings to each token can the notion of sequence be introduced. In the original paper, the authors use a positional embedding based on sine and cosine frequencies (see the previous Transformer post for details).
For simplicity, this implementation instead uses the Embedding function in PyTorch, a table of positional embeddings that is learned during training, as in GPT-2. The original paper found that learned and sinusoidal positional embeddings give nearly identical results, and chose the sinusoidal version because it may allow the model to extrapolate to sequences longer than the ones seen during training. The token and position embedding tables are then created as:
token_embedding_table = nn.Embedding(vocab_size, n_embd)    # from tokens to embedding
position_embedding_table = nn.Embedding(block_size, n_embd) # from position to embedding
Batching and dimensionality
First, a train-validation data split of 90% and 10% is performed:
data = encode(text)  #use any encoder here
n = int(0.9*len(data))
train_data, valid_data = data[:n], data[n:]
For this input, the full, train and validation datasets have 1115394, 1003854 and 111540 elements, respectively.
Batching in the attention mechanism is tricky. The model needs to accept a batch of several inputs, and each input will have a maximum size of block_size. For this to be possible, for a given input, the dataset includes all sequences from size 1 to size block_size. A single input of block_size tokens holds all of them: thanks to the mask of the attention (see below), the output at position t depends only on the tokens 0 to t.
For each input sequence from position 0 to t, the respective output is given by the element in position t+1. This logic is better detailed by the following code:
def get_batch(source):
  """ get a batch of batch_size sequences of length block_size from source """

  # generate `batch_size` random offsets on the data
  ix = torch.randint(len(source)-block_size, (batch_size,) )
  # collect `batch_size` subsequences of length `block_size` from source, as data and target
  x = torch.stack([source[i:i+block_size] for i in ix])
  # target is just x shifted right (ie the predicted token is the next in the sequence)
  y = torch.stack([source[i+1:i+1+block_size] for i in ix])
  return x.to(device), y.to(device)


# test get_batch()
xb, yb = get_batch(train_data)
print("input:\n",xb)
print("target:\n",yb)

for b in range(batch_size): #for every batches
  print(f"\n=== batch {b}:")
  for t in range(block_size): #for each sequence in block
    context = xb[b,:t+1]
    target = yb[b,t]
    print(f"for input {context.tolist()} target is {target.tolist()}")
this would output, for block_size=4 and batch_size=3:
input:
 tensor([[45, 57,  1, 59],
        [ 1, 40, 43,  1],
        [39, 52, 42,  1]])

target:
 tensor([[57,  1, 59, 54],
        [40, 43,  1, 56],
        [52, 42,  1, 52]])

=== batch 0:
for input [45] target is 57
for input [45, 57] target is 1
for input [45, 57, 1] target is 59
for input [45, 57, 1, 59] target is 54

=== batch 1:
for input [1] target is 40
for input [1, 40] target is 43
for input [1, 40, 43] target is 1
for input [1, 40, 43, 1] target is 56

=== batch 2:
for input [39] target is 52
for input [39, 52] target is 42
for input [39, 52, 42] target is 1
for input [39, 52, 42, 1] target is 52
Feed Forward Network
In the GPTlite model, the feed-forward network (FFN) is the second module of each block, after the attention, as illustrated below:
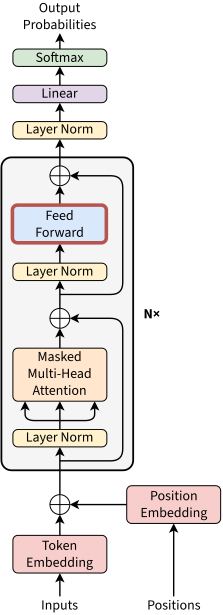
The feed forward network in the GPTlite model, emphasized in red. Adapted from: Attention Is All You Need.
The FFN is a single-hidden-layer Deep Neural Network, applied to each token separately, and is pretty straightforward to implement:
class FeedForward(nn.Module):
  """ the feed forward network (FFN) in the paper"""

  def __init__(self, n_embd):
    super().__init__()
    # Note: in the paper (section 3.3) we have d_{model}=512 and d_{ff}=2048.
    # Therefore the inner layer is 4 times the size of the embedding layer
    self.net = nn.Sequential(
        nn.Linear(n_embd, n_embd*4),
        nn.ReLU(),
        nn.Linear(n_embd*4, n_embd),
        nn.Dropout(dropout)
      )

  def forward(self, x):
    return self.net(x)
The Causal Mask
The multi-head attention is the first module of each block, as illustrated below:
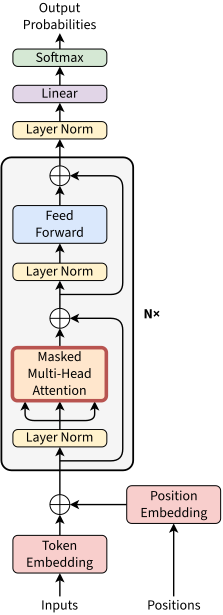
The multi-head attention module in the GPTlite model, emphasized in red. Adapted from: Attention Is All You Need.
The point of the attention mask is to define which elements are “visible” to other elements in the attention matrix, and by how much. A common example is to use a lower-triangular attention matrix, which presents to each row (token) the current and previous tokens in the sentence. This is the causal mask of the decoder: the guess of the next token may only depend on the tokens before it. Each value in the attention matrix holds the “importance” that the column token has, compared to all other columns of that row, when the row token needs to make a decision. Thus, the simplest implementation of an attention matrix is to assign uniform weights across each row, so that all tokens have the same weight/importance.
For simplicity, the following letters are used for the shapes of arrays:
- size
Bfor the batch size, defined above bybatch_size; - size
Sfor the sequence dimension, or input sequence length, defined byblock_size; - size
Efor the embedding size of each token, defined above byn_embd; - size
Cfor the vocabulary size, defined above byvocab_size.
Given a random input value x of shape [B, S, E]:
B, S, E, = 4, 8, 2
x = torch.randn(B,S,E) #shape (B,S,E)
A uniform attention matrix can be computed as:
#attention matrix (lower triangular), a mask used to only show previous items to predict next item
wei = torch.tril(torch.ones((S,S), dtype=torch.float32, device=device))
#normalize mask so that it sums to one. use keepdim to make broadcast operation work later
wei /= wei.sum(dim=1, keepdim=True)
or in an alternative notation (useful later):
tril = torch.tril(torch.ones(S,S))
wei = wei.masked_fill(tril==0, float('-inf'))
wei = F.softmax(wei, dim=-1) #equivalent to the normalization above
where both notations output as wei the following:
tensor([[1.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
        [0.5000, 0.5000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
        [0.3333, 0.3333, 0.3333, 0.0000, 0.0000, 0.0000, 0.0000, 0.0000],
        [0.2500, 0.2500, 0.2500, 0.2500, 0.0000, 0.0000, 0.0000, 0.0000],
        [0.2000, 0.2000, 0.2000, 0.2000, 0.2000, 0.0000, 0.0000, 0.0000],
        [0.1667, 0.1667, 0.1667, 0.1667, 0.1667, 0.1667, 0.0000, 0.0000],
        [0.1429, 0.1429, 0.1429, 0.1429, 0.1429, 0.1429, 0.1429, 0.0000],
        [0.1250, 0.1250, 0.1250, 0.1250, 0.1250, 0.1250, 0.1250, 0.1250]])
Again, the wei matrix indicates how much attention each token should give to itself and previous tokens, normalized to 1. In this case, it is uniform.
A dot product of the attention wei by the input x gives the output of the attention head for the given x:
out = wei @ x # dot product shape: (B,S,S) @ (B,S,E) = (B,S,E) ie ([4, 8, 2])
Both x and out have dimensionality [B, S, E], i.e. [4, 8, 2]. Each output is thus the average of the current and previous inputs. However, a token usually depends more on some tokens than on others: the attention of the next section learns these weights from the data.
Scaled Dot-Product Attention
Consider now the non-uniform attention matrix, whose weights are computed from the tokens themselves.
The weights come from three vectors that three learned linear layers compute from the vector of each token: a query, a key and a value. Think of the query as what a token looks for, the key as what a token offers, and the value as the information that a token passes on. The weight that a token gives to each visible token grows with the dot product of its query and the key of that token.
As an example, take three tokens with the keys \([1, 0]\), \([0, 1]\) and \([1, 1]\), and the query \([2, 0]\) of the third token. Its dot products with the three keys are 2, 0 and 2. Their softmax, after a division by \(\sqrt{2}\) (the square root of the size of the keys, explained below), gives the weights 0.45, 0.11 and 0.45. So the third token attends to the first token and to itself, and little to the second, and its output is the weighted average of the three values. The second token, with the query \([0, 1]\), sees only the first two keys: its weights are 0.33 and 0.67, and the causal mask gives the third token a weight of zero.
The original paper formulates the attention of one head, the scaled dot-product attention, as:
\[\text{Attention}(Q, K, V) = \text{softmax} \left( \frac{Q K^T}{\sqrt{d}} \right) V\]where \(Q\), \(K\) and \(V\) are the \(S \times d\) matrices of the queries, keys and values of the \(S\) tokens of a sequence, and \(d\) is their size (head_size, called \(d_k\) in the paper and in the comments of the code). In the decoder, the causal mask is applied to the scores \(QK^T/\sqrt{d}\) before the softmax.
The implementation starts with the \(W^Q\), \(W^K\) and \(W^V\) matrices, the weights of a simple projection (linear layer) to the head size \(d\) (head_size):
head_size=4
key   = nn.Linear(E, head_size, bias=False)
query = nn.Linear(E, head_size, bias=False)
value = nn.Linear(E, head_size, bias=False)
The scaled scores \(QK^T/\sqrt{d}\) of \(\text{Attention}(Q,K,V)\) can now be computed as:
k = key(x) #shape (B,S, head_size)
q = query(x) #shape (B,S, head_size)
wei = q @ k.transpose(-2, -1) #shape (B,S, head_size) @ (B,head_size,S) = (B,S,S)
wei *= head_size**-0.5 #scale by sqrt(d_k) as per paper, so that variance of the wei is 1
The (alternative) notation of the uniform attention above is then adapted, and the output of the non-uniform attention matrix is computed as:
tril = torch.tril(torch.ones(S,S))
wei = wei.masked_fill(tril==0, float('-inf')) #tokens only "talk" to previous tokens
wei = F.softmax(wei, dim=-1) #equivalent to the normalization above (-inf in upper diagonal will be 0)
v = value(x) # shape (B,S, head_size)
out = wei @ v # shape (B,S,S) @ (B,S,head_size) --> (B,S,head_size)
Note that out = wei @ v is the same inner dot product as the previous out = wei @ x, but this time the attention weights are not uniform: they are computed from learned parameters and change per query and over time. And this is the main property and the main problem that self-attention solves: non-uniform attention weights per query. This is different from the uniform attention matrix, where weights were uniform across all previous tokens, i.e. aggregation was a raw average of all tokens in the sequence. Here, they are aggregated by a “value of importance” for each token.
Also, without the \(\sqrt{d}\) normalization, the values in wei would have a high variance (of \(d\), for queries and keys with independent components of zero mean and unit variance). The softmax would then approximate a one-hot vector and have very small gradients. This normalization creates a more diffuse (less sparse) wei vector. In numbers, the scores would have a standard deviation of 2 with the heads of size 4 of GPTlite, and of 11.3 with the heads of size 128 of GPT-3.
The mechanism coded here is called self-attention because \(K\), \(Q\) and \(V\) all come from the same input x. But attention is more general: the queries may come from one sequence and the keys and values from another one, which is called cross-attention. In the encoder-decoder attention of the original transformer, the queries come from the decoder and the keys and values from the output of the encoder.
As final remarks, note that elements across batches are always independent, i.e. there is no cross-batch attention. And in many cases, e.g. a string representation of chemical compounds, or sentiment analysis, there can be no attention mask (i.e. all tokens can attend to all tokens). Other tasks use a custom mask that fits them (e.g. the main, upper and lower diagonals, to allow tokens to see only their closest neighbors). Also, here there is no cross-attention between the encoder and decoder, as the model is decoder-only.
Multi-Head Attention
A multi-head attention runs \(H\) such heads in parallel, each with its own projections, and concatenates their outputs. The original paper formulates it as:
\[\text{MultiHead}(Q, K, V) = \text{Concat}(\text{head}_1, ..., \text{head}_H) \, W^O\] \[\text{where } \text{head}_i = \text{Attention}(Q W^Q_i, K W^K_i, V W^V_i)\]In these formulas, \(H\) is the number of heads (n_head, called \(h\) in the paper), \(W^Q_i\), \(W^K_i\) and \(W^V_i\) are the \(E \times d\) projections of head \(i\), and \(W^O\) is the \(Hd \times E\) output projection. The inputs \(Q\), \(K\) and \(V\) are \(S \times E\) matrices, which the projections turn into the \(S \times d\) queries, keys and values of each head. In self-attention, all three are the input x.
In GPTlite, the head size is \(d = E/H\) (head_size = n_embd // n_head in the Block module below), so that the concatenated outputs of the heads have the size \(E\) of the embedding. The configuration of this post has 4 heads of size 4. Each head can then learn its own attention pattern, and the \(H\) heads together cost about as much as a single head of size \(E\) (Section 3.2.2 of the Transformer paper). The Head module, i.e. the masked attention of one head above, is implemented as:
class Head(nn.Module):

  def __init__(self, head_size):
    super().__init__()
    self.key   = nn.Linear(n_embd, head_size, bias=False)
    self.query = nn.Linear(n_embd, head_size, bias=False)
    self.value = nn.Linear(n_embd, head_size, bias=False)
    self.head_size = head_size
    self.register_buffer('tril', torch.tril(torch.ones(block_size, block_size)))
    self.dropout = nn.Dropout(dropout)
    #Note: this dropout randomly prevents some tokens from communicating with each other

  def forward(self, x):
    B,S,_ = x.shape
    k = self.key(x) #shape (B,S, head_size)
    q = self.query(x) #shape (B,S, head_size)
    v = self.value(x) #shape (B,S, head_size)

    #compute self-attention scores
    wei = q @ k.transpose(-2, -1) #shape (B,S, head_size) @ (B,head_size,S) --> (B,S,S)
    wei *= self.head_size**-0.5 #scale by sqrt(d_k) as per paper, so that variance of the wei is 1
    wei = wei.masked_fill(self.tril[:S,:S]==0, float('-inf')) # (B,S,S)
    wei = F.softmax(wei, dim=-1) # (B, S, S)
    wei = self.dropout(wei)

    #perform weighted aggregation of values
    out = wei @ v # (B, S, S) @ (B, S, head_size) --> (B, S, head_size)
    return out
and the MultiHeadAttention module as:
class MultiHeadAttention(nn.Module):
  """ Multi-head attention as a collection of heads with concatenated outputs."""
  def __init__(self, num_heads, head_size):
    super().__init__()
    self.heads = nn.ModuleList([Head(head_size) for _ in range(num_heads)])
    self.proj  = nn.Linear(head_size*num_heads, n_embd) # combine all head outputs
    self.dropout = nn.Dropout(dropout)

  def forward(self, x):
    out = torch.cat([head(x) for head in self.heads], dim=-1)
    out = self.proj(out)
    out = self.dropout(out)
    return out
The GPT Block
The sequence of a multi-head attention and a feedforward module is called here a GPT block. The model stacks n_layer such blocks, the N× of the following picture:
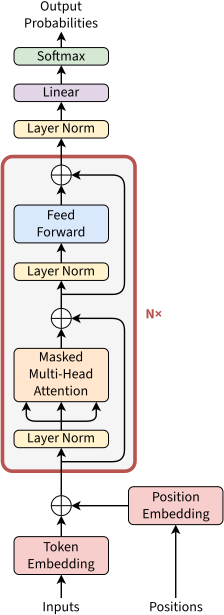
The GPT block(s) in the GPTlite model, emphasized in red. Adapted from: Attention Is All You Need.
There are some subtle improvements worth emphasizing. Because the network can become too deep (and hard to train) with a high number of sequential blocks, skip connections (or residual connections) are added to each block. The attention and the FFN add their output to their input (x = x + ... in the code below), so that the gradients flow directly through the stack of blocks.
Also, in the original paper, the layer normalization operation is applied after the attention and the feed-forward network, and after the skip connection is added. Nowadays, it is common to apply it in the pre-norm formulation, where normalization is applied before the attention and the FFN. The pre-norm formulation keeps the gradients well-behaved at initialization, so the training does not need the learning-rate warm-up stage of the original post-norm formulation, as shown in the paper On Layer Normalization in the Transformer Architecture. That is also what the following code does:
class Block(nn.Module):
  """ Transformer block: communication (attention) followed by computation (FFN) """

  def __init__(self, n_embd, n_head):
    # n_embd: embedding dimension
    # n_head: the number of heads we'd like to use
    super().__init__()
    head_size = n_embd // n_head
    self.sa = MultiHeadAttention(n_head, head_size)
    self.ffwd = FeedForward(n_embd)
    self.ln1 = nn.LayerNorm(n_embd)
    self.ln2 = nn.LayerNorm(n_embd)

  def forward(self, x):
    x = x + self.sa(self.ln1(x))
    x = x + self.ffwd(self.ln2(x))
    return x
Final Model
Putting it all together, the main model is wrapped as:
class GPTlite(nn.Module):

  def __init__(self, vocab_size):
    super().__init__()

    # vocabulary embedding and positional embedding
    self.token_embedding_table = nn.Embedding(vocab_size, n_embd)
    self.position_embedding_table = nn.Embedding(block_size, n_embd)

    #sequence of attention heads and feed forward layers
    self.blocks = nn.Sequential( *[Block(n_embd, n_head) for _ in range(n_layer)])

    #one layer normalization layer after transformer blocks
    #and one before linear layer that outputs the vocabulary
    self.ln = nn.LayerNorm(n_embd)
    self.lm_head = nn.Linear(n_embd, vocab_size, bias=False)


  def forward(self, idx):
    """ call the model with idx, for training or generation """

    #idx is of shape (B,S)
    B, S = idx.shape
    tok_emb = self.token_embedding_table(idx) #shape (B,S,E)
    pos_emb = self.position_embedding_table(torch.arange(S, device=idx.device)) #shape (S,E)
    x = tok_emb + pos_emb #shape (B,S,E)
    x = self.blocks(x)
    x = self.ln(x)
    logits = self.lm_head(x) #shape (B,S,C)
    logits = torch.swapaxes(logits, 1, 2) #shape (B,C,S) to comply with CrossEntropyLoss
    return logits
The model outputs the logits: one unnormalized score per token of the vocabulary, at each position of each sequence, of shape [B, C, S]. The inference (token generation) function is autoregressive: it samples one token at a time from the softmax of the logits of the last position, and appends it to the input sequence of the next step:
  def generate(self, idx, max_new_tokens):
    """ given a context idx, generate max_new_tokens tokens and append them to idx """
    for _ in range(max_new_tokens):
      idx_cond = idx[:, -block_size:] #we can never have any idx longer than block_size
      logits = self(idx_cond) #call fwd without targets
      logits = logits[:, :, -1] # take last token. from shape (B, C, S) to (B, C)
      #convert logits to probabilities
      probs = F.softmax(logits, dim=-1) # shape (B, C)
      #randomly sample the next tokens, 1 for each of the previous probability distributions
      #(one could take instead the argmax, but that would be deterministic and boring)
      idx_next = torch.multinomial(probs, num_samples=1) # shape (B, 1)
      #append next token ix to the solution sequence so far
      idx = torch.cat([idx, idx_next], dim=-1) # shape (B, S+1)
    return idx
Train loop
Now the model can be instantiated and copied to the compute device:
m = GPTlite(vocab_size).to(device)
The Adam optimizer is then initialized and the train loop is performed, with a cross-entropy loss between the logits and the next tokens (targets):
# train the model
optimizer = torch.optim.Adam(m.parameters(), lr=learning_rate)
for steps in range(max_iters):
  idx, targets = get_batch(train_data)   #get a batch of training data
  logits = m(idx)   #forward pass
  loss = F.cross_entropy(logits, targets)
  loss.backward()   #backward pass
  optimizer.step()   #update parameters
  optimizer.zero_grad(set_to_none=True)  #sets to None instead of 0, to save memory

  #print progress
  if steps % 100 == 0: print(f"step {steps}, loss {loss.item():.2f}")

  @torch.no_grad()
  # eval loop: no backprop on this data, to avoid storing all intermediate variables
  def eval_loss():
    idx, targets = get_batch(valid_data)   #get a batch of validation data
    logits = m(idx)   #forward pass
    loss = F.cross_entropy(logits, targets)
    print(f"step {steps}, eval loss {loss.item():.2f}")
    return loss

  if steps % eval_interval == 0: eval_loss().item()
Size matters
The model is now tested. A single token (the \n character, encoded as token 0) is passed to the model as the initial character, and the model generates a sequence of 500 tokens:
#a 1x1 tensor with batch size 1 and sequence length 1 and starting value 0 (0 is the \n character)
idx = torch.zeros((1,1), dtype=torch.long, device=device)

# test the same generate() function, now with the trained model
print(decode(m.generate(idx, max_new_tokens=500).tolist()[0]))
and this will start babbling some text, which looks a bit random for now:
IVINILCHIUKI noes hereseoke

PIV:
Ansto not 'dk thit, lighinglest in, the tole Himpams witecoond My me,
Cothe pill cthermandunes
The yould hankenou sonogher dovings age's eenat orshe:
And? Camer ou heithande, sonteas
Ans d th sonce;s ee e a
Bet n severe ay an kin nthely; wid, min. se garfitin d,
s I at nd d tlineay hanoro f;'s ikeff t maleanta t t'san bus weleng, c,
Ther coressoonerves se ivenind s,
An then, e g
Anand nvienowhin, an somend tisefffospup thid meewgonevand s,
pe
Anony a onaneyou ynuplot fouthaies angen hr imoupe?

E CAsinoveatot toooven
A cevet heplig tsest were sis d whelen fen CLUny cer:
Aid: a d?
UFrrand age thak?

CEDUKINIG m.
Hak's; te!
This is because, for the sake of this tutorial, the GPTlite model uses very small hyperparameters: it has only 21,568 parameters. Each of its 500 training steps reads 3 sequences of 4 tokens, only 6,000 tokens in total, less than 1% of the training data. Better results can be achieved by increasing several of the hyperparameters above, such as the batch size, the sequence length, the embedding size and the number of GPT blocks. As an example, the following hyperparameters:
eval_interval = 100
max_iters = 5000
learning_rate=3e-4
batch_size = 128
block_size = 256
n_embd = 300
n_layer = 10
dropout = 0.2
lead to a significant performance improvement:
Pettience! if Tybalt ally kny to the waywards
That we renow't I have satic I fain.
Provotest the office Paul wains up the dudght.

And MOLEO:
Then me findy,
I do from the king him. How going in him.

TRANIO:
Good mind beherd at the world hold I pray
Toke you remect. If all my vernant youth I bear you
Dod forth.

DUKE VINCENTIO:
And ambibed, my lords I am not thence unnat;
Why, how said, too determoly fear is mercy,
But whether by my swalind
Tless and Rome: what guess the catter
Than thou not pro
With these hyperparameters, GPTlite has 10.9 million parameters instead of 21,568, and its 5,000 training steps read 164 million tokens, 163 times the size of the training data. As for the size of real-scale models, the paper Language Models are Few-Shot Learners provides several details about GPT-3. Its largest model has 175 billion parameters, about 8 million times the default GPTlite, in 96 blocks with an embedding size of 12,288 and 96 heads of size 128. It reads sequences of 2,048 tokens, and was trained on 300 billion tokens (Section 2.1 and Table 2.1 of the paper).
To find more about this particular GPT implementation or about GPT in general, the original tutorial video builds the same model step by step, and the nanoGPT repo trains GPT models at a larger scale. The video State of GPT gives an overview of the 4-step training process (pre-training, supervised fine-tuning, reward modeling and reinforcement learning), detailed in the papers Training language models to follow instructions with human feedback and Proximal Policy Optimization Algorithms.
All done! The full Python implementation of the code presented is in the GPTlite repo.