Kernel Fusion for MoE Expert Parallelism
A Mixture-of-Experts (MoE) layer holds many experts, of which each token activates only a few, so that the number of parameters of a model grows without growing its compute cost per token. In 2020, GShard placed the experts of such a layer on different accelerators, with expert parallelism, and both are now standard in large language models. The cost of expert parallelism is communication: every MoE layer sends each token to the accelerators that hold its experts, and brings their outputs back. According to COMET, these two transfers take on average 47% of the execution time of popular MoE models and frameworks.
The usual remedies are of two kinds:
- scheduling the layer in chunks, so that the communication of one chunk overlaps the computation of another, as in the two-microbatch overlap of DeepSeek-V3;
- fusing the communication into the compute kernels, so that the arrival of a chunk starts its matrix multiplication, as in COMET.
However, both run the transfers on the accelerator’s own compute units, as a transfer must be issued by some execution unit of the device. A kernel that communicates must therefore reserve some of its units for it: thread blocks in COMET, and a configurable number of streaming multiprocessors (SMs) in DeepSeek’s DeepEP library. As an example, DeepSeek-V3 gives about 15% of the SMs of each GPU to communication, and calls for hardware that takes this work off them. In practice, every unit given to communication is taken from the experts.
This post describes a kernel that takes the transfers off the compute units. It first compares the two common implementations of the MoE collectives, AllGather-ReduceScatter and All-to-All, and their forms on an in-network computing (INC) switch, i.e. a network switch that computes. It then covers two INC methods for the MoE layer, the INC all-to-all and its phased variant for switches with little memory, and a kernel that fuses the whole layer into a single launch of eight stages, pipelined over microbatches so that three classes of hardware units work at the same time. The post ends with the results on a node with four compute devices.
Expert parallelism: dispatch and combine
Consider \(W\) compute ranks, i.e. devices, and an MoE layer of \(E\) experts, where each token selects its top-\(k\) experts. With expert parallelism, each rank holds \(E_{\text{loc}} = E/W\) experts, and the layer processes \(N\) tokens of width \(H\), split into microbatches of \(m_b\) tokens. Every MoE layer then runs two collectives:
- the dispatch sends each token to the ranks that hold its \(k\) experts, and each rank runs its local experts on the tokens it receives;
- the combine returns the weighted outputs of the experts to the rank that owns each token, where the \(k\) contributions are summed.
Each rank is therefore the token rank of its tokens and the expert rank of its experts. The following table shows a small example of \(W=3\) ranks, each holding one token and one expert, with top-\(k=2\). The router produces this routing table, which maps each token to its experts and to the ranks that hold them. Each row is a token rank, and each column the expert of a rank:
| Token rank | \(E_0\) on \(P_0\) | \(E_1\) on \(P_1\) | \(E_2\) on \(P_2\) |
|---|---|---|---|
| \(P_0\) | A | A | |
| \(P_1\) | B | B | |
| \(P_2\) | C | C |
The INC all-to-all phased, described later, uses an INC barrier, at which every rank waits until all ranks have joined.
Two implementations of the dispatch and combine, or backends, are common: AllGather-ReduceScatter and All-to-All. Each of them runs through a regular switch that relays packets, or through an INC switch, so there are four communication models, and the last of them also has a phased variant. In this post, the dispatch (one-to-many) always follows a push model, in which each sender writes its data to the receiver. Without INC, the combine (many-to-one) follows a push model too, and the owner of each token sums the partial results that it receives (rank reduce); with INC, it follows a pull model, in which the INC switch reads the partial results itself and sums them (INC reduce).
The pictures below count the steps of each model, i.e. the transfers on the critical path from the data being ready to its delivery. The relays are the packets that cross the switch for each rank.
AllGather-ReduceScatter
AllGather-ReduceScatter (AGRS) broadcasts all tokens to all ranks, and reduce-scatters the results. On the dispatch, every rank pushes its whole microbatch to every rank through the switch, so each rank holds all tokens. Each rank runs its experts on the tokens routed to them and sums their outputs per token, ignoring the tokens not routed to its experts and writing zero outputs (\(\emptyset\)) for them. On the combine, every rank pushes its outputs for the tokens of each token rank to that rank, \(\emptyset\) where it holds none, and the token rank computes the final sum. The following picture illustrates both collectives on the example:
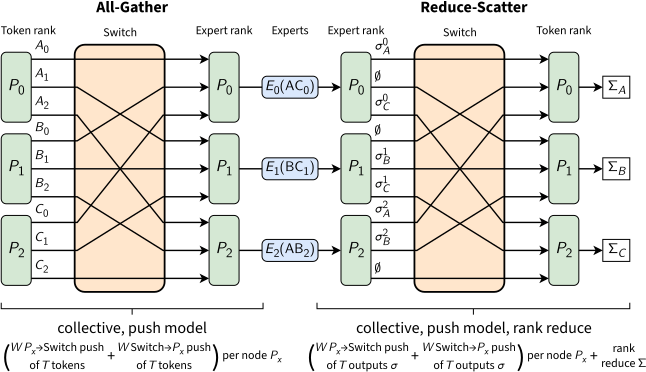
AllGather-ReduceScatter through a switch that relays each packet, with the dispatch (All-Gather) on the left and the combine (Reduce-Scatter) on the right. \(A_0\) is token A sent to the expert rank \(P_0\), \(E_0(\text{AC}_0)\) the expert \(E_0\) of \(P_0\) processing tokens A and C, \(\sigma^y_t\) the partial sum of the expert outputs of \(P_y\) for token \(t\), \(\Sigma_t = \sigma^0_t + \sigma^1_t + \sigma^2_t\) their sum across all ranks, i.e. the final output of token \(t\), and \(\emptyset\) a token without output. Under each collective, a bracket names its model and counts its steps per node \(P_x\).
AllGather-ReduceScatter does not depend on the routing, which makes it simple, but it moves up to \(W\) times more data than needed: each rank pushes its tokens \(W\) times on the dispatch, once per destination, and its outputs \(W\) times on the combine.
All-to-All
All-to-All (A2A) avoids the worst case that AllGather always pays, i.e. sending every token to every rank whatever the routing. Its clear benefit is a selective send and receive: each token goes only to the ranks that hold its experts, so a token whose experts lie on \(d \le \min(k,W)\) distinct ranks leaves its owner \(d\) times, as many times as with AllGather only when \(d=W\). Its combine is the reverse all-to-all, followed by a sum on the owner of each token:

All-to-All through a switch that relays each packet, with the dispatch on the left and the combine on the right, in the notation of AllGather-ReduceScatter. \(\emptyset\) on a dotted arrow is a signal alone, sent where a rank has no data for the destination.
The cost of the selective send is that the message sizes depend on the routing, so every receiver must know how much data it gets from each sender. Two-sided libraries such as MPI therefore need an additional all-to-all beforehand, in which the ranks trade their send and receive counts, as in the distributed implementation of the MoE post. This setup step adds the latency of one more collective to every layer, although the setup of a step can sometimes be overlapped with the computation of the previous one. The one-sided implementation of this post sends the counts with the tokens instead: the first chunk that a token rank puts to each rank holds the number of chunks and bytes and the top-\(k\) experts of its tokens, and a rank with no tokens for a destination sends it a put_signal* with no payload, i.e. a signal alone (\(\emptyset\) in the picture above), so that no receiver waits forever. One bit of the signal tag says whether a payload came with it. Thus, each collective still puts a packet from every rank to every rank, i.e. \(W^2\) packets into the switch and \(W^2\) packets out of it, although only those with tokens carry a payload, and the owner of each token sums the partial results that it receives.
On the other hand, AllGather-ReduceScatter needs no setup step, as the number of tokens and outputs that each rank sends and receives is known beforehand. It is simpler to implement, and for small MoE models, or on a small number of ranks, where each token is needed on most ranks anyway, it may be faster. All-to-All suits larger groups of ranks, where the selective send saves more than the setup costs.
In-network computing
In-network computing is not new. In 2016, SHArP offloaded the reductions of MPI collectives into the switches of an InfiniBand network, and its second version, SHARPv2, added the streaming aggregation of large messages, which the gradients of deep learning need. In 2019, SwitchML aggregated the gradients of data-parallel training inside programmable switches, training up to 5.5 times faster. Inside a node, NVLink SHARP brings the same capabilities to the switches between the GPUs, which accelerate the all-reduce, all-gather and reduce-scatter collectives of the GPUs’ collective communication library.
An INC switch accelerates the gather, scatter and reduce operations in two ways:
- multicast of unique tokens: each rank sends a token to the switch only once, and the switch replicates it to every rank that needs it, instead of the sender sending one copy per destination;
- in-switch reduction: the switch sums the partial results that it receives, instead of forwarding all of them to the destination rank, which sums them there.
In practice, both lower the bandwidth that each rank needs and the number of packets that the switch relays. The overview In-Network Collective Operations: Game Changer or Challenge for AI Workloads? covers the benefits of INC for AI workloads and the obstacles to its adoption in more detail.
INC AllGather-ReduceScatter
An INC switch improves AllGather-ReduceScatter with fewer relays and less bandwidth. On the dispatch, each rank pushes a single copy of its tokens to the INC switch, which broadcasts their concatenation to all ranks once every rank has arrived. On the combine, the INC switch pulls the outputs of each rank once the rank signals them ready, sums them as they arrive, and returns to each token rank the outputs of its tokens:
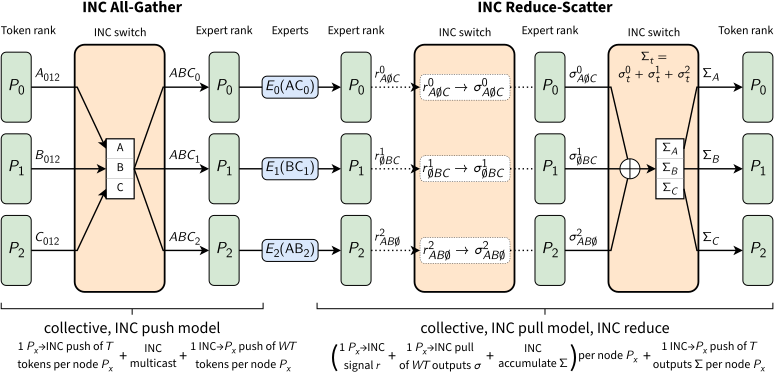
INC AllGather-ReduceScatter, with INC All-Gather on the left and INC Reduce-Scatter on the right. \(A_{012}\) is token A for the expert ranks \(P_0\), \(P_1\) and \(P_2\), \(\text{ABC}_0\) the tokens A, B and C for \(P_0\), \(\sigma^0_{A\emptyset C}\) the partial sums of \(P_0\) for the tokens A and C, with no output for B, and \(r^0_{A\emptyset C}\) the signal that they are ready (dotted). The first INC switch of the combine maps each ready signal, in a dashed box, to the pull of the partial sums that it names, \(r^y_t \rightarrow \sigma^y_t\); the expert ranks are drawn again where the INC switch pulls from them.
Compared with AllGather-ReduceScatter, each rank issues one operation per collective instead of \(W\), and one packet per rank crosses the switch in each direction, instead of \(W\). As INC switches such as NVLink SHARP support it already, and as it is a single-step communication, with no setup step to exchange counts as in All-to-All, AllGather-ReduceScatter is still used for the dispatch and combine of many production systems. As an example, the MoE layers of Megatron-Core can dispatch and combine for inference with an all-gather and a reduce-scatter on NVLink SHARP, and vLLM offers an AllGather-ReduceScatter backend next to its all-to-all ones.
DeepSeek considers both sides. DeepSeek-V3 runs its dispatch and combine as an all-to-all without INC, with point-to-point transfers that its SMs issue, and asks for hardware that takes over this work, i.e. a network co-processor like SHARP, with read, write, multicast and reduce operations. The Insights into DeepSeek-V3 paper names both INC opportunities, a dispatch that “resembles a small-scale multicast” and a combine that could use in-network aggregation, but judges a flexible combine hard to implement in the network, because of its small reduction scope and its imbalanced load. The pull model of the INC combine below, which adds the partial results in whatever order they become ready, is a response to this concern. Similarly, a deployment of DeepSeek-V4-Pro in SGLang runs the MoE layers of the prefill with an all-gather and a reduce-scatter, whose communication is predictable, and those of the decode with the all-to-all of DeepEP.
INC all-to-all
The MoE collectives differ from the dense and symmetric collectives of training in every respect that matters to a switch. The dispatch is a multicast that depends on the routing, and the combine is a sparse sum, weighted per token and expert, and interleaved with a permutation. In practice, the opportunity is not to aggregate gradients, but to replicate each dispatched token inside the network rather than at its sender, and to fold the sum of the combine into the transfer that carries it. This is what the two methods of this post do. The first, the INC all-to-all, replaces the dispatch and the combine with two new INC collectives, INC All-to-All-Dispatch and INC All-to-All-Combine; the second, the INC all-to-all phased, runs them over phases of ranks, for switches with little memory.
INC All-to-All-Dispatch
The dispatch is replaced by INC All-to-All-Dispatch, an all-to-all extended with an in-network multicast: a one-to-many collective on an INC push model, in which each sender sends a single copy of each token, however many ranks need it, as in INC All-Gather. Each token rank writes its microbatch, in token order and with its routing metadata, into its own slot on the INC switch, with one put_signal*. The switch finds the senders with wait_until_some, in whatever order their flags rise, and regroups the tokens of each sender by expert rank as they arrive.
Once every sender has arrived, the switch sends each expert rank the tokens that its experts need, in one coalesced packet with one put_signal*, which the rank waits for with wait_until_some. Thus, the replication and the permutation of the tokens run entirely on the switch.
INC All-to-All-Combine
The conventional combine is wasteful in two ways: the \(W\) partial results of a token cross the network independently, and their sum on the owner cannot start until all of them have arrived.
The transfer and the sum are fused into INC All-to-All-Combine, an all-to-all extended with an in-network selective reduction: a many-to-one collective on an INC pull model, as in INC Reduce-Scatter. Each expert rank writes its partial results into its own symmetric heap, a memory region allocated at the same offset on every rank and reachable by the switch, raises its ready flag on the INC switch with one signal, and goes back to the experts. The switch serves the flags in the order they rise, found with wait_until_some: it pulls the partial results of the rank that signaled with one get, completes the pull with a quiet, and adds them to the sum as they land. Once all ranks are in, it sends each token rank its rows of the sum with one put_signal*, which the rank waits for with wait_until.
The combine needs no metadata of its own, as it reuses the counts per sender of the dispatch, transposed, and the compute ranks run no cross-rank arithmetic. Note that each expert rank applies the routing weights to its expert outputs before it publishes its partial results, so the switch only adds them. The following picture shows both collectives on the example above:

The dispatch and combine of the example through the INC switch, with \(W\) transfers in and \(W\) out per collective. Left: INC All-to-All-Dispatch. Right: INC All-to-All-Combine. \(A_{02}\) is token A for the expert ranks \(P_0\) and \(P_2\), \(\text{AC}_0\) the tokens A and C for \(P_0\), \(\sigma^y_{AC}\) the partial sums of \(P_y\) for tokens A and C, and \(r^y_{AC}\) the signal that they are ready (dotted). The INC switch maps each ready signal to the pull of the partial sums that it names, \(r^y_t \rightarrow \sigma^y_t\), and adds them into \(\Sigma_t\).
Every flag is a 32-bit integer, into which each sender writes the magic of its step, a value that strictly increases from step to step, so that a flag left from an earlier step never reads as an arrival. Slots are indexed by the microbatch modulo the pipeline depth, and a slot is written again only after the combine of the microbatch that used it has completed. As this combine follows every read of the slot, no further flow control is needed: in INC All-to-All-Combine, each rank receives its sums only after the switch has pulled the partial results of every rank. The INC switch also starts the next sum only after a quiet has completed the puts that read the previous one.
The timeline below follows the three tokens of the example through both collectives, with the operations of each device:

The dispatch and combine of the example through INC All-to-All-Dispatch and INC All-to-All-Combine, with the token ranks on the left and the expert ranks on the right. Once every token rank has put its tokens, the INC switch multicasts them grouped per expert rank, \(\text{AC}_0\) to \(P_0\), \(\text{BC}_1\) to \(P_1\) and \(\text{AB}_2\) to \(P_2\). Then, as each expert rank signals its partial sums ready, \(r^0_{AC}\), \(r^1_{BC}\) and \(r^2_{AB}\), the switch pulls that rank’s sums, runs a quiet and accumulates them, and it finally returns \(\Sigma_C\), \(\Sigma_B\) and \(\Sigma_A\). The asterisk marks nonblocking calls, dotted arrows flags raised alone with signal, and a dot a flag awaited with wait_until.
No switch implements these two collectives today. Therefore, the implementation of this post emulates the INC switch with two extra devices of the same type as the compute ranks, one for the dispatch and one for the combine, which run the one-sided operations above on the symmetric heap. They hold no model parameters and run no experts.
Bandwidth and packet count
With a conventional all-to-all dispatch, a token whose experts lie on \(d\) distinct ranks is sent \(d\) times by its owner, so each rank sends up to \(\min(k,W) \cdot m_b\) rows per microbatch, and the network carries \(\mathcal{O}(W^2)\) point-to-point flows. The conventional combine mirrors this, with each owner receiving up to \(\min(k,W)\) partial results per token, and each rank issues \(W\) operations per collective.
INC All-to-All-Dispatch and INC All-to-All-Combine remove the duplicates at either end. On the dispatch, each rank sends each token exactly once, in token order and with no packing per destination; on the combine, the switch sums the partial results in flight, and each owner receives one result per token. Therefore:
- the rows that a rank sends on the dispatch, and receives on the combine, fall from up to \(\min(k,W) \cdot m_b\) to \(m_b\), i.e. by up to a factor of \(W\) when \(k \ge W\), as in the setup below (\(k=8\) and \(W=4\));
- the packets that cross the switch fall from \(2W^2\) to \(2W\) per collective, over links whose endpoints are known in advance, so that the transfers can be scheduled ahead;
- the operations that each rank issues fall from \(W\) to one per collective.
Why the combine pulls
An INC switch can get its data in the two ways above. With a push model, the senders write their data into the memory of the switch with a put_signal*; with a pull model, they only signal, and the switch reads the data itself with a get. A pusher knows its own byte count, so a push needs no agreement on sizes beforehand, whereas a puller must know how much to read. Therefore, the dispatch, whose sizes only the sender knows, pushes.
The combine pulls, because pulling lets the switch add each partial result to the sum as soon as it lands, instead of holding all \(W\) partial results before summing them. This keeps the reduction within the limited memory of the switch. Pulling also lets the switch choose the order, so that a late rank does not stall the sum of the ranks already present. Moreover, it gives the switch flow control: it reads a rank only when it can fold it in, so a burst of partial results cannot overflow its memory.
The cost is that the switch starts transfers itself, rather than being a purely reactive switch, which departs from SHArP and from other in-switch designs. This is the price of fusing a reduction that is permuted, rather than symmetric.
INC all-to-all phased
The weak point of the INC all-to-all is the memory of the switch. INC All-to-All-Dispatch and INC All-to-All-Combine, as INC All-Gather and INC Reduce-Scatter, are collectives: they are asynchronous on the compute ranks, but synchronous on the switch, which relays nothing until all \(W\) ranks have sent their data into it, and holds all of it meanwhile. However, switches have limited memory for multicast and reduction.
For such switches, the second method of this post, the INC all-to-all phased, runs INC All-to-All-Dispatch (Phased) and INC All-to-All-Combine (Phased): the variant of the INC all-to-all that executes both collectives iteratively, as phased collectives over \(G\) ranks each, so that the switch multicasts to and reduces over one phase at a time, and holds only the data of that phase. \(G\) ranges from 1 to \(W\), where \(G=W\) is the INC all-to-all, and the results below are for \(G=1\). The dispatch multicasts the tokens of each token rank as they arrive. The combine serves one phase per request of a token rank, in the order the requests land: each request carries the expert metadata of its tokens, which tells the switch from how many expert ranks to pull with get for its sum \(\Sigma\), and to which token rank to return it. Because of industry confidentiality, the specific implementation cannot be detailed; its details will be released in the near future. A phased INC All-Gather and Reduce-Scatter, which follows the same logic, was also implemented.
The following picture shows the INC all-to-all phased on the example, in a simplified view:
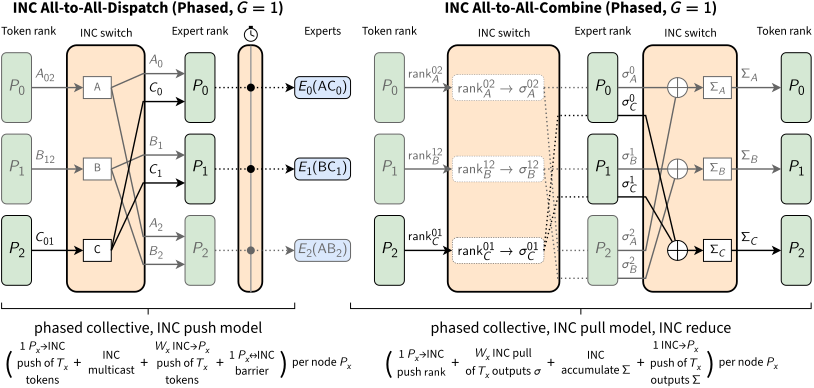
INC All-to-All-Dispatch (Phased) on the left and INC All-to-All-Combine (Phased) on the right, with \(G=1\), following token C of \(P_2\) (black; the other phases are faded). The INC switch multicasts C to \(P_0\) and \(P_1\), which join an INC barrier (stopwatch), and once every token rank has sent its request, \(\text{rank}^{01}_C\) for \(P_2\), which names the expert ranks of token C, it pulls their partial sums for C and returns \(\Sigma_C\) to \(P_2\). Because of industry confidentiality, the drawing omits the details of the implementation. Brackets count the steps per node \(P_x\), where \(W_x \le W\) is the number of ranks that hold the experts of its tokens.
The timeline below follows the three tokens of the example through the INC all-to-all phased, in the same simplified view:
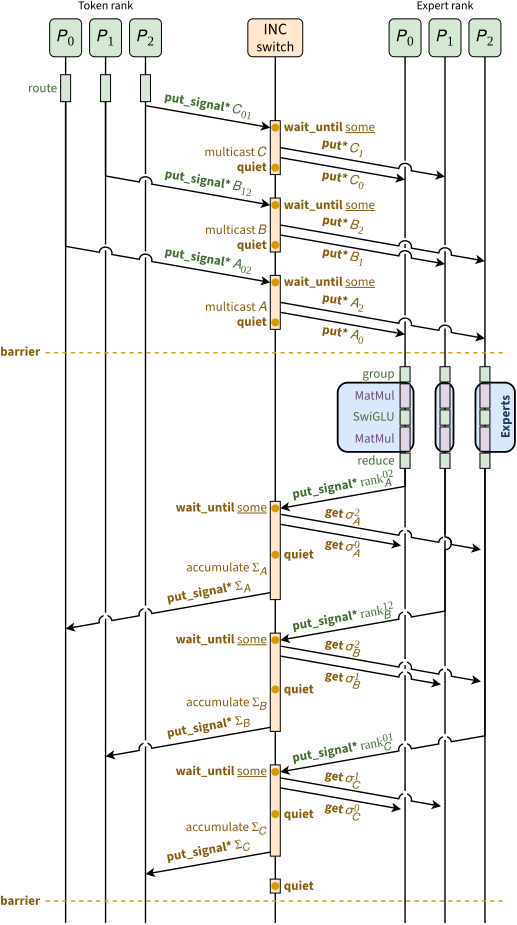
The dispatch and combine of the example through INC All-to-All-Dispatch (Phased) and INC All-to-All-Combine (Phased), with \(G=1\), in the notation of the timeline of the INC all-to-all. The INC switch multicasts each token as it lands, every rank joins an optional INC barrier (dashed line), and the switch then serves one phase per request, as each request lands, as \(\text{rank}^{02}_A\) for \(P_0\): it pulls the partial sums, runs a quiet, accumulates them and returns their sum. A final quiet and barrier end the collective.
The phased collectives need up to \(W\) times less switch memory, their main benefit, which suits them to larger batches and to switches with little memory. Their dispatch also helps with expert load imbalance, as it multicasts the tokens as they arrive. The price is latency: they take more steps and relays than the INC all-to-all. The optional INC barrier after the dispatch guarantees that all tokens have been delivered, so that each expert still runs one large matrix multiplication over all its tokens, rather than several small ones that leave the matrix units under-utilized as the tokens of each phase arrive.
The routing density and the memory of the switch decide which method to use. Under uniform routing, each of the \(k\,m_b\) expert choices of a microbatch misses a given rank with probability \(1-1/W\), so the number of distinct ranks that the microbatch selects is approximately given by:
\[W_x \approx W \left( 1 - \left( 1 - \frac{1}{W} \right)^{k\, m_b} \right)\]where \(W_x\) tends to \(W\) once \(k\,m_b \gg W\): at \(k=8\) and \(W=4\), even a single token selects 3.6 ranks on average. Each phase then relays to all \(W\) ranks, as the collective does. Thus, the INC all-to-all is the default, both in prefill, where the wait for every rank hides behind the matrix units, and in decode, where the latency of the network is the bottleneck. The INC all-to-all phased is the choice for a switch with little memory, at a cost that the results below measure.
The hardware
The kernel is described in hardware-agnostic terms, which apply to the accelerators of different vendors. Compute blocks (e.g. the SMs of a GPU) schedule parallel threads and hold two classes of arithmetic units, which a single kernel launch programs and which run at the same time:
- matrix units (MUs) for two-dimensional matrix operations, such as matrix multiplications;
- vector units (VUs) for elementwise work, gathers, scatters and data movement.
Memory is divided into the off-chip global memory (GM), i.e. the high-bandwidth memory (HBM) of large capacity, and the on-chip local memory (LM), a scratchpad managed by software (e.g. the shared memory of a GPU). An interconnect fabric links the devices into one logical node, and a collective communication library (CCL) provides the collectives over it, next to the one-sided operations of the collectives above.
Note that a cross-rank transfer is issued by a vector unit and staged through its local memory, so a rank that communicates always spends vector unit cycles on it. This hardware fact motivates the whole design.
Fusing the layer into one kernel
Fusion is worth its effort because of what a non-fused layer costs. A conventional layer is a sequence of kernels, each loading its inputs from global memory, computing, and writing its outputs back. Fusion collapses this sequence into one launch and keeps the intermediate results on-chip, as FlashAttention did for attention, and megakernels extend it to a whole model, as in a low-latency megakernel for Llama-1B.
In a distributed layer the case is stronger, as each synchronous collective breaks the layer into separate kernels, with buffers sized for the whole batch in global memory between them. The MoE dispatch and combine are the hardest collectives to fuse: their transfers are sparse, their sizes depend on the routing, and the combine carries a weighted sum.
The MoE layer is split into eight stages, chosen so that each stage runs entirely on one class of unit, and consecutive stages alternate between classes wherever a dependency allows. The stages are:
routecomputes the routing metadata of a microbatch, and ends with oneput_signal*of its tokens and metadata into the INC switch;dispatchis an INC All-to-All-Dispatch: once the tokens of every compute rank have arrived, the INC switch sends each rank the tokens that its experts need;groupgathers the received rows into the expert-contiguous order that the grouped matrix multiplication needs;MatMulis the gate and up projection of the experts, on the matrix units;SwiGLUis the activation function (SwiGLU), on the vector units;MatMulis the down projection of the experts, on the matrix units;reducescales each expert output by its routing weight, accumulates it into the partial result of the rank, and signals the INC switch;combinesums the partial results of each token and returns the sum to its owner, as an INC All-to-All-Combine on the INC switch.
Only two of the eight stages are collectives, and both run on the INC switch. The following picture shows the stages in dependency order:

The eight stages of the fused MoE layer, in dependency order, each on the class of unit that runs it: matrix multiplications on the matrix units (purple), all other computation on the vector units (green), and both collectives on the in-network element (orange). The blue frame holds the experts. The time axis sketches the decode step, whose batch is too small to be split into microbatches, so the matrix units idle while the network works. The orange boxes draw the INC all-to-all phased, whose dispatch and combine run in phases, one per rank, the bold box being the phase of this rank.
Note that the INC switch puts the final result into the symmetric heap rather than into the output tensor of the layer, so one local copy to global memory remains. This copy is left out of the stages: it crosses no link of the network, its measured cost is close to zero, and it fuses into the next route, which reads those rows anyway.
Three forms of the layer are compared in this post, from no fusion to fusion with INC:
- Baseline: each stage is its own kernel, so every boundary is a store to global memory followed by a load, and ten tensors are stored, among them the two intermediate results of the experts, the largest of the layer. Two extra stages are needed: a
packbefore the dispatch, which lays out a copy of each token contiguously per destination, and aglobal reduceafter the combine, which sums the \(W\) partial results of each token on its owner. The collectives are calls to the CCL, issued by the vector units of the rank. - MegaKernel: the ten stages of the Baseline in one launch. The intermediate results of the experts stay in local memory, which cuts the round trips to global memory from ten to seven. However, the plain all-to-all still needs the
packand theglobal reduce, and its transfers become one-sided operations relayed by a switch, still issued by the vector units of the rank: oneput_signal*per destination, i.e. \(W\) per collective. - MegaKernel INC: the eight stages in one launch, with both collectives run by the INC switch, as the INC all-to-all or as its phased variant. INC removes the two extra stages: the
packdisappears, as each rank sends one copy of each token, in token order, and theglobal reducedisappears, as the sum is folded into the transfer. Only four regions of global memory remain visible to the network, all in the symmetric heap. The layer needs one launch and five round trips to global memory, with oneput_signal*and onesignalper microbatch issued by each compute rank.
The following picture follows one microbatch through the memories that an MoE layer touches (the local memory of a rank, its global memory, and the far side of the network) in the Baseline and in MegaKernel INC, and shows how INC simplifies the layer:

Data movement for one microbatch. Left: Baseline, one kernel per stage. Right: MegaKernel INC, one fused kernel with the INC transfers, without the pack and the global reduce stages. Each row is a stage (colored box) and the tensor it stores in global memory (white box), and \(\star\) marks the symmetric heap. The blue frame holds the experts, dashed lines mark kernel boundaries, and the bracket one kernel launch. Each INC stage runs as the INC all-to-all or as its phased variant.
Pipelining and three-way overlap
A single microbatch uses one class of unit at a time, as its chain of stages is strictly sequential. However, the chain crosses from one class of unit to another seven times, and every crossing frees the unit it leaves for another microbatch. Therefore, the kernel runs \(M\) microbatches through the chain at the same time, each one stage behind the previous one, so that at any instant the matrix units, the vector units and both INC devices work on different microbatches. The following picture shows the resulting schedule during the prefill step:

Pipelined execution of four microbatches (mb 0 to 3) during prefill, with time to scale from the cost of each stage. Each microbatch has three rows, one per class of unit, colored as in the stages above. A kernel uses all matrix and all vector units, so no two purple and no two green boxes overlap; the dispatch and the combine run on two independent INC devices, so a dispatch may overlap a combine. Both run in phases, one per rank, as in the stages above.
In the schedule above, each microbatch is routed and put into the INC dispatch device, which fans it out once the copies of all ranks have arrived. The microbatch then passes through group, the two matrix multiplications, SwiGLU and reduce, before the combine device sums the partial results and returns them. While the matrix units multiply microbatch \(m\), the vector units run the group stage of microbatch \(m+1\). Note that stage \(s\) of microbatch \(m\) waits only on stage \(s-1\) of the same microbatch, so there is no global barrier.
The microbatch size is the knob of this pipeline, and its best value depends on the implementation rather than being a fixed size or a fixed number of microbatches. MegaKernel is fastest with microbatches of 512 to 2,048 tokens for batches below 8,192 tokens, and of 2,048 to 4,096 tokens above, with a flat optimum. MegaKernel INC, with and without phases, prefers smaller microbatches that grow with the square root of the batch, about \(9\sqrt{N}\) tokens, i.e. 256 tokens at a batch of 1,024 and 2,048 tokens at 65,536. This is the optimum of a pipeline that splits \(N\) tokens into \(M=N/m_b\) microbatches through an effective number \(S\) of overlapping stages, where each microbatch costs a fixed \(o\) and a \(c\) per token in each stage: minimizing \(T=(M+S-1)(o+c\,m_b)\) gives the optimal microbatch size as:
\[m_b^\ast = \sqrt{\frac{o\,N}{(S-1)\,c}}\]which is the optimal packet size of pipelined communication (Table 5 of Optimum Broadcasting and Personalized Communication in Hypercubes). Microbatches that are too large cost the most: without microbatching at all, the MoE layer of MegaKernel INC takes 1.9 to 2.1 times as long at 8,192 tokens as with microbatches of 1,024 tokens. Each implementation is therefore reported below at its best microbatch size.
The schedule extends the two-microbatch overlap of DeepSeek-V3, which hides the dispatch and combine of one microbatch behind the computation of another. Here, a vertical cut through the schedule shows a dispatch, a computation and a combine in flight at once, each for a different microbatch, with both collectives on dedicated INC devices. Pipelining also bounds the memory: the buffers of a microbatch are alive only between its first and its last stage. Therefore, the number of buffer sets alive at once is the pipeline depth \(D\), not the number of microbatches \(M\), nor the whole batch that a non-fused layer holds at once.
Results
The kernel was evaluated on OLMoE-1B-7B, an open model with 7 billion parameters in total and 1 billion active per token, \(E=64\) experts, top-\(k=8\), \(H=2048\), an intermediate width of 1024, and 16 MoE layers in bfloat16, served with vLLM. One node holds four devices as compute ranks, i.e. \(E_{\text{loc}}=16\) experts per rank at \(W=4\), plus the two devices that emulate the INC switch, one for the dispatch and one for the combine. These two serve the INC implementations only: the Baseline and the two MegaKernels without INC exchange through the switch of the fabric itself, which forwards each packet as it lands and computes nothing.
Five implementations are compared: the three above, with the INC all-to-all in MegaKernel INC, plus the two phased ones, MegaKernel INC Phased, with the INC all-to-all phased at \(G=1\), and MegaKernel Phased, which runs the plain all-to-all of MegaKernel over the same phases, so that it differs from MegaKernel INC Phased only in the role of the switch. Baseline and MegaKernel use a plain all-to-all, and MegaKernel Phased its phased form, each followed by a global reduction on the owner of each token. Thus, the Baseline against MegaKernel isolates the effect of fusion, MegaKernel against MegaKernel INC Phased adds in-network computing in phases, MegaKernel INC Phased against MegaKernel INC removes the phases, and each phased implementation against its non-phased counterpart gives the price of the phases.
Prefill runs a single forward pass over the whole batch, from 1,024 to 65,536 tokens per compute rank, which covers chunked prefill, with chunks of typically 1,024 to 4,096 tokens, and the large batches of training. Decode runs 32 steps of 1 to 64 concurrent sequences of 1,024 tokens per rank, with a KV cache, so its runtime is expected to stay quasi-constant. The MoE layer is timed as the mean over the 16 layers, and the whole model in prefill, in decode and in both; each time reported is the mean of five iterations after warm-up. In the Baseline, the MoE layers take 74% to 86% of the prefill time of the model. The runtimes of the five implementations are displayed below:

Runtime of one MoE layer in prefill (top left) and of the whole model in prefill, in decode and in both, against the input tokens per compute rank, on \(\log_2\) axes; in decode, those tokens are 1 to 64 concurrent sequences of 1,024 tokens, over 32 steps. The two phased implementations carry a line and a filled marker, and their non-phased counterparts the same marker, open and without a line, so that each pair reads as one. Each implementation uses, at each point, the microbatch size with its fastest MoE prefill.
Note that on a \(\log_2\) axis a constant speedup is a constant vertical offset. The three improvements are independent, and the following table applies them in turn to the MoE layer in prefill: fusing the layer into one kernel, adding in-network computing in phases, and removing the phases.
| Speedup of the MoE layer in prefill | 1k | 2k | 4k | 8k | 16k | 32k | 64k |
|---|---|---|---|---|---|---|---|
| Baseline \(\rightarrow\) MegaKernel | 1.85 | 1.75 | 1.66 | 1.52 | 1.29 | 1.31 | 1.28 |
| MegaKernel \(\rightarrow\) MegaKernel INC Phased | 1.02 | 1.10 | 1.27 | 1.33 | 1.44 | 1.44 | 1.52 |
| MegaKernel INC Phased \(\rightarrow\) MegaKernel INC | 1.02 | 1.02 | 1.06 | 1.05 | 1.03 | 1.02 | 1.03 |
The gap between the Baseline and MegaKernel is the return on fusion alone, on the same network and relay switch: one launch per layer, and intermediate results of the experts that never leave the local memory. It narrows as the batch grows: 1.85 times at 1k tokens, and 1.28 to 1.31 times from 16k, because the CCL collectives of the Baseline are optimized for bandwidth and the one-sided operations of MegaKernel for latency, so large payloads start to favor the CCL. The gap between MegaKernel and MegaKernel INC Phased is the return on in-network computing, with the same kernel: it removes the \(W^2\) relayed flows of the plain all-to-all, as it sends each token once and folds the sum into the transfer. This second gap widens with the batch: 1.02 times at 1k tokens, and 1.44 to 1.52 times from 16k, since in-network computing saves relays and bandwidth, whose cost grows with the payload. The network speedup therefore takes over from the software one, which it exceeds from 16k tokens, and together they run the MoE layer 1.87 to 2.11 times faster than the Baseline in prefill and the whole model 1.63 to 1.84 times faster, which at 65,536 tokens raises the prefill throughput of the model from 23,692 to 39,366 tokens per second per compute rank.
Removing the phases is worth a further 2% to 6%, as MegaKernel gains 2% to 7% over MegaKernel Phased. The phases cost latency rather than bandwidth: at \(W=4\) they move the same bytes over the same links, only serialized, and the fabric fragments a large payload into many small packets anyway, so their extra steps and relays add few packets to the many that each phase already moves. From 8k tokens the gap stays within 2% to 5%, which is why the phased variant, with its \(W\) times smaller switch memory, is the one to prefer where switch hardware is the constraint.
In prefill, computation and communication overlap fully: apart from the dispatch of the first microbatch and the combine of the last, which fill and drain the pipeline, no communication step adds to the runtime, as each rank issues only one put_signal* and one signal per microbatch and no units are reserved for communication. The two grouped matrix multiplications dominate and the schedule fits everything else under them, so the matrix units are busy 75% of the time, against 57% for the vector units and 22% for each INC device: the layer is compute-bound (see the roofline model), and the INC devices have headroom for a larger \(W\). Large prefills and training are therefore the hardest regime to accelerate, as the speedup comes almost entirely from overlap: from 16k tokens, MegaKernel INC Phased holds a steady 1.87 to 1.95 times on the MoE layer, while MegaKernel falls back to about 1.3 times.
Decode is the opposite extreme. Each step adds one token per sequence, so its payload is a handful of rows: the grouped matrix multiplications shrink to skinny GEMMs that still read the weights of every expert from global memory, and with too few tokens to split into microbatches the collectives sit on the critical path. A step is thus bound by latency rather than by work, and fusion pays most there, as it removes the per-stage launches, the round trips to global memory and the latency-exposed collective calls: the 32 steps of the model take 1.34 to 1.64 s in the Baseline and 0.74 to 1.00 s with MegaKernel INC Phased, i.e. 1.64 to 1.85 times faster, from 1 to 64 sequences per rank. Over prefill and decode together, the whole model runs 1.66 to 1.85 times faster. Note that decode ranks the fused implementations poorly: a rank reads 192 MiB of expert weights per microbatch against about 1% of that in communication, so the four fused implementations lie within 9% of each other at every point, in no consistent order, and they are therefore ranked on prefill.
Finally, the setup understates in-network computing in three ways and favors the Baseline in a fourth. The INC switch is emulated by devices, so an INC collective takes two steps in sequence, to the device and from it, where a switch that multicasts and reduces in its forwarding path removes the second. The plain all-to-all of MegaKernel is the most efficient one that could be implemented, as its relay switch forwards each packet as it lands, \(W\) parallel direct relays per rank in effectively one step, where a realistic all-to-all at scale runs as a pairwise exchange or a Bruck-style algorithm and is much slower, so the results of MegaKernel are inflated and those of the INC methods deflated. At \(W=4\) the 16 relayed flows per collective are not yet a bottleneck next to the linear relays of the INC methods, a gap expected to widen with \(W\). The collectives of the Baseline are, moreover, calls to a CCL highly optimized for this fabric, while the one-sided collectives and the emulated switch are a prototype. The gains are therefore expected to grow on switch hardware and at a larger \(W\).
Communication volume and memory
At \(W=4\), the peak number of rows that a rank sends per microbatch falls from about \(4m_b\) to exactly \(m_b\). Moreover, the symmetric heap becomes a function of the shape of the layer rather than of the routing, i.e. \(W+2\) buffer units per microbatch, which removes the over-allocation for the worst case that data-dependent routing forces.
The working set follows the pipeline, not the batch. A non-fused layer holds at once, each sized for the whole batch, the send buffer packed per destination, the receive buffer, the rows grouped by expert, the two intermediate results of the experts, and the \(W\) partial results per token. Three mechanisms remove them:
- fusion keeps the two intermediate results of the experts, the largest tensors of the layer, in local memory;
- INC All-to-All-Dispatch removes the send buffer packed per destination, as each rank sends one copy per token, in token order;
- INC All-to-All-Combine removes the receive buffer of \(W\) partial results, as each owner receives one finished result.
What remains belongs to one microbatch, and is alive only between its route and its combine, so at most \(D\) sets are alive at once in a pipeline of depth \(D\). The resident memory is therefore given by:
i.e. a function of the \(D\,m_b\) tokens in flight, not of the \(N\) tokens of the batch, so doubling \(N\) at fixed \(m_b\) and \(D\) leaves it unchanged. It grows linearly with the microbatches in flight, the same knob that buys the overlap of the pipeline.
However, the prototype allocates the buffers of all \(M\) microbatches: in the sweep above, \(M\) ranges from 2 to 64 against a depth of 5. An allocator bounded by the depth would hold five buffer sets where the current one reserves \(M\). This allocator is not implemented, and its saving is not measured.
Final remarks
Several directions remain open: INC collectives in switch hardware at a larger \(W\), an allocator bounded by the pipeline depth, a dispatch in reduced precision, shared or cloned experts, and an evaluation under continuous batching. The closest work is DySHARP (ISCA 2026), which removes the same two redundancies with multicast and reduction inside the switch, in simulation, while its SMs still issue the dispatch and the combine; on the software side, DeepEP, COMET, the Mega MoE kernel of DeepGEMM and Triton-distributed speed up or fuse the dispatch and the combine on the compute units.