Kernel Fusion for Tensor Parallelism and MoE Expert Sharding
In 2019, the paper Megatron-LM showed how to split the layers of a Transformer across GPUs with tensor parallelism, with a single collective communication per pair of linear layers. Inference engines commonly use the same scheme to serve large language models (LLMs) on the GPUs of a node. Each layer then follows the bulk synchronous parallel (BSP) model: a compute kernel runs to completion, a collective kernel (e.g. an all-reduce) exchanges its full output, and only then does the next layer start. Thus, communication sits on the critical path of every layer.
This post describes a kernel that removes these barriers from the feedforward network (FFN) of a Transformer. The kernel fuses the two linear layers of the FFN and their communication into a single GPU kernel, and runs the all-reduce inside the network switch that connects the GPUs. The same kernel then applies to the experts of a Mixture-of-Experts layer.
Kernel fusion and collective communication
An LLM runs as a long sequence of GPU kernels, where one or more kernels implement each layer. Each kernel loads its inputs from the global memory of the GPU, the high-bandwidth memory (HBM), into the on-chip memory (registers and shared memory) of the Streaming Multiprocessors (SMs), and writes its outputs back. This repeated data movement costs both time and memory.
Kernel fusion combines a sequence of kernels into a single kernel, so that the intermediate results stay on chip and are consumed directly by the next operation, without being written to global memory. Fusion is trickier than it seems, as the on-chip memory of an SM holds hundreds of kilobytes, while the HBM holds tens of gigabytes. Therefore, automatic fusion is restricted to kernels whose intermediate results are local, i.e. the partial result computed by one SM does not depend on the results of other SMs.
This is the approach of the PyTorch compiler, torch.compile, which converts a sequence of layers written in Python into fused Triton kernels, and compiles them just in time. On a single GPU, it reduces both the number of kernels launched and the memory of the intermediate tensors.
However, on several GPUs, a collective communication is not fused with the computation around it. It acts as a fusion boundary, which splits the program into separate kernels, with a synchronous collective between them and its large communication buffers in HBM. As a result, the speedup of fusion shrinks when a model moves from one GPU to several: there are fewer kernels to fuse, and the communication adds its own cost.
Megatron-LM tensor parallelism
Consider an FFN of two linear layers, with an activation in between. For an input \(X \in \mathbb{R}^{M \times N}\) of \(M\) tokens of dimension \(N\), the output of the FFN is computed as:
\[H = \text{activation}(X W_1 + b_1), \quad Y = \text{activation}(H W_2 + b_2)\]where \(W_1 \in \mathbb{R}^{N \times O}\) and \(b_1 \in \mathbb{R}^{O}\) are the weights and the bias of the first layer, \(W_2 \in \mathbb{R}^{O \times P}\) and \(b_2 \in \mathbb{R}^{P}\) those of the second layer, \(O\) is the hidden dimension and \(P\) the output dimension. The activation is applied elementwise, and the second one is optional: the FFNs of Transformers omit it.
Take 2 GPUs as an example. Megatron-LM gives the whole input \(X\) to both GPUs, and gives each GPU half of the columns of \(W_1\), with the matching half of \(b_1\), and the matching half of the rows of \(W_2\). Each GPU computes its half of the columns of \(H\) and multiplies it by its half of \(W_2\). Its result has the full shape \(M \times P\) of the output, but holds only the products over its half of the hidden dimension: the sum of the results of the two GPUs is \(H W_2\).
With tensor parallelism on \(G\) GPUs, Megatron-LM replicates \(X\) on all GPUs, and splits \(W_1\) column-wise and \(W_2\) row-wise. Each GPU \(g\) holds \(W_1^{(g)} \in \mathbb{R}^{N \times (O/G)}\), the matching slice \(b_1^{(g)}\) of the first bias, and \(W_2^{(g)} \in \mathbb{R}^{(O/G) \times P}\). It computes its slice of the hidden activations, \(H^{(g)} = \text{activation}(X W_1^{(g)} + b_1^{(g)}) \in \mathbb{R}^{M \times (O/G)}\), without any communication, as each column of \(H\) depends only on \(X\) and on one column of \(W_1\). The output is then given by:
\[Y = \text{activation} \left( \sum_{g=1}^{G} H^{(g)} W_2^{(g)} + b_2 \right)\]where the sum of the partial outputs \(H^{(g)} W_2^{(g)} \in \mathbb{R}^{M \times P}\) of all GPUs is an all-reduce. Note that the all-reduce must finish before \(b_2\) and the second activation are applied: the bias is added once, and the activation is not linear, so it cannot be applied to the partial outputs. Thus, this layout needs only one communication step per pair of layers. The tensor parallelism post illustrates this layout on 2 GPUs, with the names of the Megatron-LM paper: \(A\) and \(B\) for \(W_1\) and \(W_2\), \(Y\) for \(H\), and \(YB\) for the sum of the partial outputs.
As an example, consider an FFN with the dimensions of Llama 3 70B, i.e. an input dimension \(N\) and an output dimension \(P\) of 8,192, and a hidden dimension \(O\) of 28,672, on \(G = 8\) GPUs. Each GPU holds 3,584 of the 28,672 columns of \(W_1\), and as many rows of \(W_2\). For a batch of 8,192 tokens, its slice \(H^{(g)}\) holds \(8{,}192 \times 3{,}584\) values, i.e. 56 MiB in BF16. Its partial output holds \(8{,}192 \times 8{,}192\) values, i.e. 128 MiB, which the all-reduce sums across the 8 GPUs.
A regular implementation of this FFN launches 7 kernels: a matrix multiplication, a bias addition and an activation for each layer, plus the all-reduce, or 6 without the second activation. Each kernel loads its inputs from global memory and stores its outputs there, as displayed at the top of the timeline below. In the example above, the first layer alone stores three tensors of 56 MiB (after the matrix multiplication, the bias and the activation), and loads them back. The kernel of this post runs the whole FFN as one kernel, with a single load and a single store to global memory (bottom), and with many small all-reduce steps that overlap the computation:

Execution timeline of an FFN with Megatron-LM tensor parallelism. Top: the regular execution, with 7 kernels that load from (arrow up) and store to (arrow down) global memory. Bottom: the fused kernel, with several small, overlapping all-reduce steps performed in the network switch.
The fused kernel is built in three steps, each adding to the gains of the previous ones: the fusion of the two linear layers, the overlap of their computation with the communication, and an all-reduce executed in the switch.
Step 1: fusing the two linear layers
Two linear layers without a nonlinearity in between collapse into a single one, as the product of two matrices is a matrix:
\[(X W_1 + b_1) W_2 + b_2 = X (W_1 W_2) + (b_1 W_2 + b_2)\]and the intermediate tensor \(H\) is never needed. With an activation in between, this collapse is no longer possible, and the usual approach materializes (i.e. stores) the full tensor \(H\) in global memory, from where a second kernel reads it back.
A matrix multiplication (GEMM, for general matrix multiply) on a GPU is computed in tiles, i.e. small submatrices of the output. Each thread block, a group of threads that runs on one SM, computes a tile by iterating over the matching tiles of its inputs. The fused kernel keeps this tiling for the first layer. In this section, \(H\), \(W_2\) and \(Y\) stand for the slices \(H^{(g)}\) and \(W_2^{(g)}\) of one GPU and for its partial output \(H^{(g)} W_2^{(g)}\), as in the next picture.
The activation does not prevent the fusion, as it applies to each tile of \(H\) on its own. The difficulty is the second matrix multiplication, which sums over the hidden dimension: each tile of its output adds up the products of many thread blocks and, with tensor parallelism, the partial outputs of all GPUs.
The key idea is that, as soon as a tile \(H_{i,j}\) is computed (with its bias and activation), it is multiplied by every tile in row \(j\) of \(W_2\). The products are added to the tiles in row \(i\) of \(Y\). This follows from the product of block matrices, where each tile of the output is given by:
\[Y_{i,k} = \sum_{j} H_{i,j} \, (W_2)_{j,k}\]When all tiles of \(H\) are processed, \(Y\) holds the full product \(H W_2\), and \(H\) was never stored in global memory, as illustrated below:

Top: the regular execution computes all tiles of \(H\), stores \(H\) in global memory, and a second kernel computes \(Y\). Bottom: the fused kernel multiplies each tile of \(H\) by a row of tiles of \(W_2\) and accumulates the results in a row of tiles of \(Y\).
Many blocks add their products to the same tile of \(Y\) at the same time, so the additions must be atomic. However, blocking atomic additions quickly become a bottleneck, as the contention on \(Y\) grows with the number of tiles. Instead, the kernel accumulates the tiles with the asynchronous tile reductions of the GPU, which add a tile of on-chip memory to a tile of global memory without blocking the thread block that issues them.
These reductions overlap the next matrix multiplications in a ping-pong pattern. For a tile of \(H\) and the row of tiles of \(W_2\) that it multiplies, the execution proceeds as:
- first tile: compute the product, and issue its asynchronous reduction;
- intermediate tiles: compute the product, wait for the reduction of the previous tile to complete, and issue the reduction of the current tile;
- final tile: compute the product, issue its reduction, and wait for the last two reductions to complete.
Thus, the latency of the accumulation is mostly hidden behind the computation of the next tile.
The kernel also needs to know when a tile of \(Y\) is complete. A per-tile counter, which each contributing block increments atomically, counts the contributions to the tile, and the block that makes the last contribution marks the tile as ready with a per-tile flag in global memory. Each tile of \(Y\) receives \(\lceil (O/G)/T \rceil\) contributions, one per tile of \(H^{(g)}\) along the hidden dimension for tiles of width \(T\), which is a small number for the FFNs of this post. With tiles of width 128, for example, the 3,584 columns of the Llama 3 70B example give 28 contributions. As a side note, a variant that replaces the counter by an array of flags, one per contributing block, removes the contention on the counter, but gives no measurable speedup, as the counter is not on the critical path.
Note that a ready tile is final, and can be sent to the other GPUs right away, without waiting for the rest of \(Y\). Therefore, the communication happens per tile, with buffers of 32 KiB (a tile of \(128 \times 128\) values in BF16), instead of a buffer for the whole \(Y\), which takes 128 MiB in the Llama 3 70B example and up to 2.5 GiB for the largest batch of the benchmarks below.
The fusion of consecutive matrix multiplications on a single GPU is not new. Back-to-back GEMM kernels, as generated by BOLT, keep the intermediate tiles in on-chip memory, which limits the hidden dimension to what fits on chip. In this kernel, the partial products are accumulated in global memory by many blocks, so the hidden dimension has no such limit, and each tile of \(Y\) is handed to the all-reduce as soon as it is final. Also, the accumulation of partial tiles from several blocks with completion flags follows Stream-K.
Step 2: overlapping computation and communication with block specialization
How to communicate the ready tiles? In a regular kernel, all blocks do the same work, and synchronize only at the end of the kernel. If every block computes and then communicates, the blocks that finish early must spin-wait until all tiles of a region are ready before the region is reduced across GPUs, which leaves SMs idle. Block specialization splits the blocks of the kernel into two groups instead:
- compute blocks run the matrix multiplications of step 1, and mark the tiles of \(Y\) as ready;
- communication blocks each own a band, i.e. a contiguous range of tiles of \(Y\). A communication block polls the ready flags of its band, all-reduces the band across GPUs as soon as all its tiles are ready, applies the bias \(b_2\) and the second activation, and writes the result to the output.
Thus, compute blocks never wait for communication, and communication blocks never run matrix multiplications. The price is that the matrix multiplications run on fewer SMs, which makes them slower, although only marginally on a GPU with many SMs. In return, the idle time disappears, as the following example on a GPU with 6 SMs shows:

An example on a GPU with 6 SMs. (a) Without block specialization, all SMs compute and then spin-wait before each band is all-reduced. (b) With block specialization, SM1 and SM2 all-reduce each band as soon as SM3 to SM6 have computed it.
Looking at the diagram above, the bands of (b) take longer to compute than those of (a), as they run on four SMs instead of six. However, the all-reduce of each band runs on SM1 and SM2 while SM3 to SM6 compute the next band, so the kernel finishes earlier.
Similar specializations exist at other levels. Inside a thread block, FlashAttention-3 uses warp specialization, where some warps, the groups of threads that an SM schedules together, load data from global memory while the others compute. Across the GPU, DeepSeek-V3 gives about 15% of the SMs to the communication of its Mixture-of-Experts layers. Here, the specialized blocks run the all-reduce of the tensor-parallel FFN, one band at a time.
Step 3: all-reduce with in-network computing
In-network computing (INC) performs the reductions of a collective while the data traverses the network switches, instead of on the end devices. In 2019, SwitchML used it to sum the gradients of data-parallel training inside programmable switches. Within a node, the switch that connects the GPUs also offers reductions and multicasts, which the threads of a GPU kernel can issue directly.
The all-reduce of the collective communication library (CCL) is launched from the CPU, as a separate kernel that operates on full tensors, so it cannot be called on single tiles from inside a running kernel. A GPU-side shmem library can be called from inside a kernel, but it uses only part of the operations of the switch. It does not use the switch reductions for its barriers, and it imposes fixed layouts of threads and buffers, which prevent the best overlap at the tile level. Therefore, the kernel implements its own all-reduce, issued by the communication blocks and executed by the switch, on top of three operations on memory addresses that are mapped on all GPUs:
- a load-reduce reads a value from all GPUs and returns their sum (all-to-one);
- a multicast store writes one value to all GPUs (one-to-all);
- an in-place reduction adds one value to the same address on all GPUs.
These operations run in the switch, not on the cores or the memory of the GPUs, so the data is summed while it traverses the interconnect. The all-reduce of a band is then a reduce-scatter followed by an all-gather: each GPU first load-reduces its \(1/G\) share of the band, and then multicast-stores the result to all GPUs. However, a GPU cannot tell by itself when the other GPUs have finished their stores. So each GPU adds 1 to a shared flag with an in-place reduction, and when the flag reaches \(G\), all GPUs know that the band is complete.
This acts as a lightweight barrier that the GPUs run on their own, without the CPU. Note that the switch operations act on global memory, so the communication buffers of the tiles are staged there, which explains the small loads and stores around each all-reduce step of the fused kernel in the timeline above.
Expert sharding
In a Mixture-of-Experts (MoE) layer, each expert is a small FFN, with an input matrix \(W_i\) and an output matrix \(W_o\), i.e. the \(W_1\) and \(W_2\) above. With expert parallelism, each GPU holds a few whole experts, and processes only the tokens routed to them. However, the router rarely spreads the tokens evenly, so the GPU with the most tokens finishes last, and the other GPUs wait for it.
In 2025, the paper Accelerating MoE Model Inference with Expert Sharding proposed expert sharding, which splits every expert across all GPUs instead, as Megatron-LM splits the FFN. Each GPU holds a \(1/G\) share of the columns of \(W_i\) and the matching rows of \(W_o\) of every expert, and processes all the tokens of each expert with these slices. The partial outputs of all GPUs are then summed, so each expert is an FFN with Megatron-LM tensor parallelism, and runs with the fused kernel of this post.
Most importantly, expert sharding removes the load imbalance of expert parallelism: every GPU holds the same share of every expert and processes all the tokens, so all GPUs do the same amount of work, whatever the routing. Therefore, no GPU waits for another, no tokens are dropped, and popular experts need no replicas.
Compared to expert parallelism, expert sharding adds communication: every GPU needs all the tokens, and the partial outputs must be all-reduced. The fused kernel makes this communication cheap, as the all-reduce runs one band at a time on the communication blocks, overlaps the computation, and is executed by the switch. The next section measures the fused kernel on the FFNs of recent models, experts included.
Results
The fused kernel was compared to a baseline, a tuned implementation of the same FFN without fusion, block specialization or in-network computing, which uses the all-reduce of the CCL. The benchmarks run FFNs with the dimensions of Llama, DeepSeek, GPT, Mistral and Qwen models, i.e. with their input and hidden dimensions, on 8 GPUs in one node, in BF16, with batches of 8,192 to 262,144 tokens. They time one pass of the FFN, i.e. two matrix multiplications, two bias additions and one activation. Each latency is the mean of 100 runs, and the error bars of the chart show their standard deviation.
Note that the labels of the chart below name the FFNs of Llama 3 after their activation, SwiGLU. A SwiGLU FFN has a third weight matrix, whose product with the input gates the activation, and no biases. The benchmarks keep the two-layer FFN of this post, with the dimensions of each model.
The fused kernel reduces the latency by 22% to 62% (a speedup of 1.3 to 2.6 times), roughly halves the memory of the activations, and shrinks the communication buffer from gigabytes to 32 KiB. Seven of these FFNs are compared below:

Latency of the regular (baseline) and fused FFNs, sorted by improvement.
Looking at the chart above, the gains depend on the size of the FFN:
- Small FFNs (the two expert FFNs of DeepSeek V3, and Llama 3 8B) gain the most, 46% to 62%. Their hidden dimensions (2,048 and 14,336) keep the matrix multiplications cheap, and their baselines take 5.6 to 17.1 ms. In this regime, the fixed costs of the baseline dominate, i.e. the separate bias and activation kernels, the stores of \(H\) and an all-reduce that does not overlap the computation, and the fused kernel removes or hides them.
- Large FFNs (Llama 3 70B and the dense FFN of DeepSeek V3) gain 29% and 37%. Their runtime is dominated by the two large matrix multiplications, so the relative gain is smaller, but the absolute savings grow with the size of the FFN: 7.5 ms for Llama 3 70B and 91 ms for DeepSeek V3.
- The expert and shared FFNs of Llama 4 Scout combine a batch of 262,144 tokens with hidden dimensions of 8,192 and 16,384, which increases the memory traffic of the baseline. They gain 45% and 38%, and the shared FFN saves 122 ms, the largest absolute saving.
An ablation study shows that the three steps are needed together. Each variant of the following table removes one step, and is compared to the baseline over all the FFNs of the benchmarks:
| Variant | Fusion | Block specialization | INC | Latency, compared to the baseline |
|---|---|---|---|---|
| Without fusion | No | No | Yes | 2% to 15% slower: the all-reduce runs on full tensors |
| Without block specialization | Yes | No | Yes | 17% to 84% slower, the slowest variant: the communication is exposed, i.e. not hidden behind the computation. Exception: 16% and 33% faster for the two expert FFNs of DeepSeek V3 |
| Without INC | Yes | Yes | No (shmem) | 19% to 45% faster, but slower than the fused kernel: shmem adds synchronization and memory traffic that the overlap does not hide |
| Fused kernel | Yes | Yes | Yes | 22% to 62% faster |
Thus, fusion, overlap and in-network computing are complementary rather than interchangeable, and only their combination gives the gains above.
Finally, the expert FFNs of these benchmarks are split across the 8 GPUs with expert sharding, as pictured below for one expert on 2 GPUs:
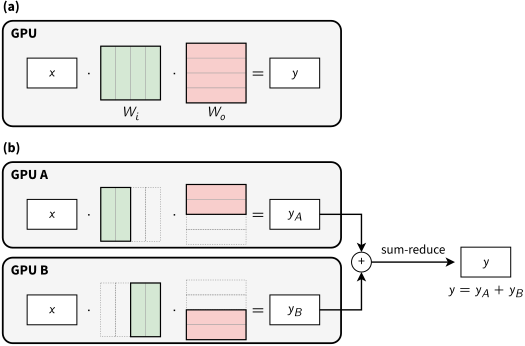
One expert, with \(W_i\) in green and \(W_o\) in red. The activation is omitted. (a) Without parallelism, one GPU holds the whole expert. (b) With expert sharding, GPU A holds the first half of the columns of \(W_i\) and of the rows of \(W_o\), and GPU B the second half. The dashed slices are on the other GPU. Both GPUs process all the tokens \(x\), and a sum-reduce adds their partial outputs \(y_A\) and \(y_B\). Inspired by Figure 2 of Accelerating MoE Model Inference with Expert Sharding.
With this split, the fused kernel reduces the latency by 55% and 62% for the two expert FFNs of DeepSeek V3, 45% for the experts of Llama 4 Scout and 42% for those of Mixtral 8×7B.
Final remarks
Several directions remain open: a fused backward pass for training, where the roughly halved activation memory would allow larger batches or models; the same fusion for distributed attention, which also chains two matrix multiplications with a softmax in between, as FlashAttention fuses on a single GPU; the dispatch and combine of expert parallelism, described in the post Kernel Fusion for MoE Expert Parallelism; compilers such as Triton-distributed that generate such kernels; and the switches between nodes, as all experiments run on a single node of 8 GPUs. The closest work overlaps the computation and the communication of tensor parallelism inside kernels, one operation at a time (CoCoNet, Flux, TileLink, TokenWeave, mKernel), while megakernels such as MPK fuse a whole forward pass on several GPUs into one kernel. This post summarizes the paper Towards Efficient LLM Inference via Full-Stack Fusion of Computation, Communication, and In-Network Computing.