Variable Timestep Simulation of the Electrical Activity of Neurons
The previous post solved simple neuron models, whose linear and unrelated state ODEs form a system of linear equations. Non-linear state ODEs and correlations between states, as in extra-cellular mechanisms and capacitors between nodes, require a fully-implicit resolution instead.
A fully-implicit method that is commonly used to resolve this problem is the Backward (Implicit) Euler with Newton iterations, where:
\[y_{n+1} - y_n = \Delta t \, f (t_{n+1}, y_{n+1})\]where \(\Delta t\) is the timestep, \(y\) is the array of states and \(f\) is the right-hand side function of the ODE. Can one do better?
CVODE for fully-implicit adaptive-order adaptive-step integration
The main principle supporting adaptive time stepping is its particular efficiency, due to large step sizes during long periods of slowly varying states, e.g. interspike intervals. NEURON’s adaptive integrator, the CVode class, can use separate variable-step integrators for individual neurons in the network. It is an interface to the CVODES and IDA (Integrator for Differential-Algebraic problems) integrators of the SUNDIALS package, a SUite of Nonlinear and DIfferential/ALgebraic Equation Solvers. CVODES extends the CVODE solver of ordinary differential equations with a sensitivity analysis, and the method described below is that of CVODE.
Backward differentiation formulas for stiff equations
NEURON employs the Backward Differentiation Formula (BDF), a family of implicit linear multistep methods for the numerical integration of (stiff) ordinary differential equations, introduced by Curtiss and Hirschfelder in Integration of Stiff Equations. For a given function and time, the BDF approximates its derivative using information from previously computed times, thus increasing the accuracy of the approximation. BDF methods are implicit, and thus require computing the solution of nonlinear equations at every step. For non-stiff problems, CVODE offers the Adams–Moulton methods instead.
The BDF multistep method is suitable for stiff problems, such as those that define neuronal activity. The main idea behind a stiff equation is that it includes terms that may lead to rapid variation of the solution, making certain numerical methods unstable, unless the step size is taken to be extremely small. A neuron mixes fast processes, such as the opening of its sodium channels during a spike, within a fraction of a millisecond, with slow ones, such as the change of its voltage between two spikes, over tens of milliseconds.
As an example, take the Dahlquist test equation \(\dot{y} = \lambda y\) with \(\lambda = -1 / \tau\): a state that decays to zero with a time constant \(\tau\), such as the gate of a fast ion channel. The Forward (explicit) Euler method computes the next value from the current one:
\[y_{n+1} = y_n + \Delta t \, \lambda \, y_n = (1 + \lambda \Delta t) \, y_n\]so, for a step \(\Delta t > 2 \tau\), the solution changes sign and grows at every step, while the exact solution decays. Backward Euler computes the next value from an equation that holds it on both sides:
\[y_{n+1} = y_n + \Delta t \, \lambda \, y_{n+1} \Leftrightarrow y_{n+1} = \frac{y_n}{1 - \lambda \Delta t}\]which decays for any step size, as the exact solution does. Therefore, the step of Forward Euler is limited by the fastest time constant of the system, even when that component has decayed and the solution varies slowly. This is what makes an equation stiff, and why the equations of neurons are solved with implicit methods, which pay for their stability with the solution of an equation at every step.
CVODE is a solver for the Initial Value Problem (IVP), an ODE together with an initial condition of the unknown function at a given point in the domain of the solution, that can be written abstractly as:
\[\dot{y} = f(t,y) \text{, } y(t_0) = y_0 \text{ where } y \in \mathbb{R}^N\]where \(\dot{y}\) denotes \(\frac{dy}{dt}\). The solution \(y\) is differentiated using past (backward) values, i.e. \(\dot{y}_n\) is a linear combination of \(y_n\), \(y_{n-1}\), \(y_{n-2}, ...\). \(y\) is the array of all state variables, in this case the voltages \(V_j\) of all compartments (governed by \(dV_j/dt\)) and the states \(x_i\) (governed by \(dx_i/dt\)), where \(x_i\) is a given state variable of an ion channel \(i\). The variable-step BDF of order \(q\) can be written as:
\[y_n = \sum_{i=1}^{q} \alpha_{n,i} y_{n-i} + h_n \beta _{n,0} \dot{y}_n\]where \(y_n\) are the computed approximations to \(y (t_n)\), \(h_n = t_n - t_{n-1}\) is the step size, and \(q\) denotes the order (number of previous steps used by the BDF). The BDF coefficients \(\alpha\) and \(\beta\) are unique, and depend on the method order and on the recent step sizes. With a constant step size \(h_n = \Delta t\), the resolution can be unfolded as:
- BDF-1: \(y_{n+1} - y_n = \Delta t \, f (t_{n+1}, y_{n+1})\), i.e. the Backward Euler;
- BDF-2: \(3y_{n+2} - 4y_{n+1} + y_n = 2 \Delta t \, f (t_{n+2}, y_{n+2})\);
- BDF-3: \(11y_{n+3} - 18y_{n+2} + 9y_{n+1} - 2y_n = 6 \Delta t \, f (t_{n+3}, y_{n+3})\);
- BDF-4: \(25y_{n+4} - 48y_{n+3} + 36y_{n+2} - 16y_{n+1} + 3y_n = 12 \Delta t \, f (t_{n+4}, y_{n+4})\);
- BDF-5: \(137y_{n+5} - 300y_{n+4} + 300y_{n+3} - 200y_{n+2} + 75y_{n+1} - 12y_n = 60 \Delta t \, f (t_{n+5}, y_{n+5})\);
- BDF-6: \(147y_{n+6} - 360y_{n+5} + 450y_{n+4} - 400y_{n+3} + 225y_{n+2} - 72y_{n+1} + 10y_n = 60 \Delta t \, f(t_{n+6}, y_{n+6})\).
BDF with order \(q > 6\) is not zero-stable, and therefore cannot be used. Zero-stability means that, if a perturbation \(\eta\) happens on an initial value, then the difference between the perturbed and unperturbed results must be no bigger than \(k \eta\), for some constant \(k \in \mathbb{R}\) independent of the step size. CVODE allows for a maximum order of 5.
Zero-stability concerns the limit of small steps. On a stiff equation, a method must also stay stable with a large step on the fast components that decay, as Backward Euler does above. BDF-1 and BDF-2 are A-stable: they are stable for any step size on any decaying component. The higher orders are not, as no linear multistep method of order higher than 2 is A-stable: they are unstable on some oscillating components, and more so as the order grows.
Newton iterations
As with any implicit method, at every step one must (approximately) solve the nonlinear system:
\[G(y_n) \equiv y_n - h_n \beta_{n,0} f(t_n, y_n) - a_n = 0 \text{ , where } a_n \equiv \sum_{i=1}^{q} \alpha_{n,i} y_{n-i} \label{eq_variable_time_step_bdf}\]The simplest way to solve it is the functional iteration, also called fixed-point iteration, which evaluates \(f\) at the previous iterate. If the iterates are denoted by \(y_{n(m)}\), the functional iteration of the BDF is given by:
\[y_{n(m+1)} = h_n \beta _{n,0} f ( t_n, y_{n(m)} ) + a_n \label{eq_newton_method_derivation}\]Each iteration is cheap, as it only evaluates \(f\), but on a stiff equation it converges only for small steps. On the test equation above, with BDF-1 (\(\beta_{n,0} = 1\) and \(a_n = y_{n-1}\)), each iteration multiplies the error by \(h_n \lambda\), so the iteration converges only for \(h_n < \tau\), a limit even stricter than the \(2 \tau\) of Forward Euler. This is why CVODE uses the functional iteration only for non-stiff problems.
To resolve this, CVODE applies Newton iterations. Newton’s method finds successively better approximations to the roots (or zeroes) of a function, and is implemented (for a function \(g\) of one variable) as \(x_{m+1} = x_m - g(x_m) / g'(x_m)\) until a sufficiently accurate value is reached. In practice, it requires finding the solution of the linear systems:
\[M [y_{n(m+1)} - y_{n(m)}] = - G(y_{n(m)})\]where \(J\) is the Jacobian matrix of \(f\), the matrix of all its first-order partial derivatives, so that \(M\) approximates the Jacobian of \(G\):
\[M \approx I - \gamma J \text{ , } J = \partial f / \partial y \text{ , and } \gamma = h_n \beta_{n,0}\]For the Newton corrections, CVODE provides the following options: (a) a direct dense solver, (b) a direct banded solver, (c) a diagonal approximate Jacobian solver, or the SPGMR (Scaled Preconditioned GMRES) method. A preconditioner matrix is a transformation that conditions a given problem into a form that is more suitable for numerical solving methods. The SPGMR method uses a preconditioner matrix \(P\) and performs an Inexact Newton iteration, in which \(M\) is applied in a matrix-free manner, and the matrix-vector products \(Jv\) are obtained by either difference quotients or a user-supplied routine.
In practice, the Newton iteration transforms the nonlinear problem into a linear one, with the matrix \(M\) that approximates the Jacobian of \(G\). Each iteration solves the equation below, written in four equivalent forms, the last one multiplied on the left by the inverse of a preconditioner \(P\):
\[\begin{align*} & y_{n(m+1)} = y_{n(m)} - M^{-1} G(y_{n(m)}) \\ \Leftrightarrow \; & y_{n(m+1)} - y_{n(m)} = - M^{-1} G(y_{n(m)}) \\ \Leftrightarrow \; & M [y_{n(m+1)} - y_{n(m)}] = - G(y_{n(m)}) \\ \Leftrightarrow \; & P^{-1} M [y_{n(m+1)} - y_{n(m)}] = - P^{-1} G(y_{n(m)}) \end{align*}\]where the preconditioner \(P \approx I - \gamma J\) is another approximation of \(M\), for which a linear system is cheap to solve.
The first form requires a division by \(M\), i.e. a multiplication by its inverse. Due to the expensive computation of the inverse of the Jacobian, CVODE allows for a trade-off between the accuracy and the solution time of any equation, by requiring one to only supply a solver for \(P z = b\) instead, for a given vector \(b\).
NEURON does not use SPGMR: it supplies its own solver for \(P z = b\), in which the SOLVE block of each mechanism solves for the states of that mechanism, and takes \(P\) in place of \(M\) in the Newton iteration. For this linear system, although NEURON supports a resolution with the Hines solver (the default) or the (a) or (c) methods mentioned previously, there has been little exploration of the non-Hines approaches. The Hines solver, described in the previous post, solves the tree of compartments of a neuron in a time linear in their number. The tests of the preprint presented at the end of this post support this default: the diagonal approximation (c) was faster but highly inaccurate, and the dense solver (a) accurate but too slow and too large in memory.
Error Control and Step Size Selection
One main difference between fixed and variable time stepping is that, from the user’s perspective, one does not specify the time step but the relative (rtol) and absolute (atol) local error tolerances instead. The solver then adjusts the step size \(h_n\) based on the two values. The local error is estimated from an extrapolation of the previous steps, as described below. CVODE uses a weighted root-mean-square norm for all error-like quantities, denoted as:
\[|| v || = \sqrt{ \frac{1}{N} \sum_{i=1}^N (v_i / W_i)^2}\]where \(v_i\) represents the deviations, and the weights \(W_i\) are based on the current solution (with components \(y^i\)), with user-specified absolute tolerances \(\text{atol}_i\) and relative tolerance \(\text{rtol}\), as:
\[W_i = \text{rtol} \cdot \vert y^i \vert + \text{atol}_i\]In NEURON, the default relative tolerance is 0, so the weights are the absolute tolerances.
NEURON’s default error setting for CVODE was 10 μV for the membrane potential and 0.1 nM for the internal free calcium concentration (Hines and Carnevale, 2001). It gives an HH-based action potential an accuracy equivalent to that of a fixed time step of \(\Delta t = 25\) μs, although the interspike intervals are sometimes inaccurate unless the voltage tolerance is very small. Most tests below use \(\text{atol} = 10^{-3}\), the current default, i.e. 1 μV for the membrane potential. The default maximum order for BDF is 5, although it is recommended to let CVODE decide the best order.
Each step starts from a prediction \(y_{n(0)}\), extrapolated from the previous steps, which the Newton iterations of the previous section correct into \(y_{n(m)}\): CVODE is a predictor–corrector method. The difference between the two estimates the local truncation error of the step, i.e. the error made in this step alone, which grows as \(h_n^{q+1}\) for a method of order \(q\). The step passes the local error test when:
\[\lVert \Delta_n \rVert \leq \epsilon \text{ , where } \Delta_n = y_{n(m)} - y_{n(0)}\]and \(\epsilon\) depends on the order of the method, so that the test holds when the estimated local truncation error is below 1 in the weighted norm, i.e. within the tolerances. If the test fails, the step is rejected and tried again with a smaller step size.
In both cases, the size \(h'\) of the next step, or of the new attempt, is computed from the error of the current one. As the error grows as \(h_n^{q+1}\), the step is scaled so that the next error is 6 times smaller than the bound, as a safety margin:
\[\frac{h'}{h_n} = \left( \frac{\epsilon}{6 \, \lVert \Delta_n \rVert} \right)^{1/(q+1)}\]In practice, the steps grow while the states vary slowly, and shrink when they vary fast. After a successful step, CVODE limits the growth to a factor of 10, and keeps the step size when the factor is below 1.5. Also, after \(q + 1\) steps at order \(q\), it estimates this ratio for the orders \(q - 1\) and \(q + 1\) as well, and takes the order with the longest step.
When the integration restarts after a discontinuity, such as an incoming spike, CVODE starts again at order 1 with a small step, and raises the order by at most one every \(q + 1\) steps. This restart is why the number of events weighs so much on the cost of CVODE in the sections below.
Within each step, CVODE also controls the error of the Newton iterations. If \(y_n\) is the exact solution of equation \ref{eq_variable_time_step_bdf}, CVODE ensures that the iteration error \(y_n - y_{n(m)}\) is small enough, i.e. \(\| y_n - y_{n(m)} \| < 0.1 \epsilon\), where \(\epsilon\) is the bound of the local error test above (and \(0.1\) is user-changeable). For this, it also estimates the linear convergence rate constant \(R\), initialized at \(1\) and reset to \(1\) when \(M\) or \(P\) is updated. After computing a correction \(\delta_m = y_{n(m)} - y_{n(m-1)}\), \(R\) is updated if \(m > 1\) as:
\[R \leftarrow \text{max} \left\{ 0.3 R, \frac{|| \delta_m ||}{||\delta_{m-1} ||} \right\}\]It is used to estimate
\[||y_n - y_{n(m)}|| \approx || y_{n(m+1)} - y_{n(m)}|| \approx R || y_{n(m)} - y_{n(m-1)}|| = R || \delta_m ||\]Thus, the convergence test is
\[R || \delta_m || < 0.1 \epsilon\]CVODE allows at most 3 iterations per step (by default). If the test still fails, or if the iteration diverges, CVODE updates the Jacobian and tries again, and, when the Jacobian is already up to date, it reduces the step size to a quarter instead.
Local and Global Time Stepping
Large networks of cells cannot be integrated efficiently with global adaptive time stepping, as a high frequency of events such as gating channels or synapses causes discontinuities in parameters or state variables. These discontinuities require the reinitialization of the computation and force the integrator to start again with a new initial value problem. NEURON’s workaround is a local variable time stepping scheme called lvardt (Lytton and Hines, Independent Variable Time-Step Integration of Individual Neurons for Network Simulations, MIT Press) that creates individual CVODE integrators per cell. It aims at short time step integration for active neurons and long time step integration for inactive neurons, while keeping the integration accuracy consistent.
All cells are kept in an ordered queue (a splay tree), where their position is given by their event delivery time or their current simulation time. Because the system moves forward in time with multiple, independent integrators, the overall computation is reduced when compared to the global counterpart. Nevertheless, the main issue is the coordination of the time advancement of each cell, i.e. all the state variables of a given cell should be correctly available to any incoming event.
To solve that issue, every cell holds the information for all states between its current time instant and the previous time step. This allows for interpolation: the states of the cell at any time of its last step are computed from the stored values, without integrating the equations again, so that a cell can go back in time when an event arrives in its past. The integration coordinator also ensures that the interpolation intervals of the connected cells overlap, so that no event between two cells is missed. The critical point of this approach is that the time step is tentative, and an event received by the cell in the interim may reinitialize the cell to a time prior to the tentatively calculated threshold time.
The following picture illustrates a timeline (from A to D) of six cells running the lvardt algorithm. The intervals of possible interpolation are displayed as rectangles, and the right end of a cell’s rectangle, \(t_b\), is the time up to which that cell has integrated. The system’s earliest \(t_b\) or event time is shown by the dashed vertical line traversing all neurons. Triggers of discrete events on a particular neuron are displayed as short red vertical bars.
The four steps of the timeline are:
- (A) the cell with the smallest \(t_b\) (cell 0) advances by the length of the hashed rectangle, and crosses the spike threshold during that step, creating a tentative trigger event;
- (B) cell 5 has the smallest \(t_b\) and integrates forward;
- (C) the next earliest event in the system is the trigger of cell 0. This event trigger creates three new events to be delivered to cells 3, 4 and 5, at different delays;
- (D) the new earliest event forces cell 3 to back-interpolate, the event is handled, and cell 3 reinitializes. Cell 3 will be the next cell to integrate forward:
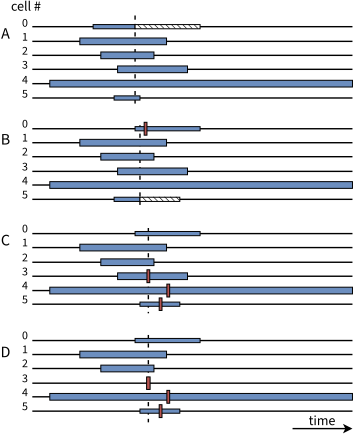
Adapted from: Lytton and Hines (2005), Independent variable time-step integration of individual neurons for network simulations, Fig. 1
Single Neuron Performance
One can notice the difference in performance of the Backward Euler (left) and Variable Timestep (right) integrators during the steep trajectory of an action potential of a layer 5 pyramidal cell in the following picture (one dot per step):
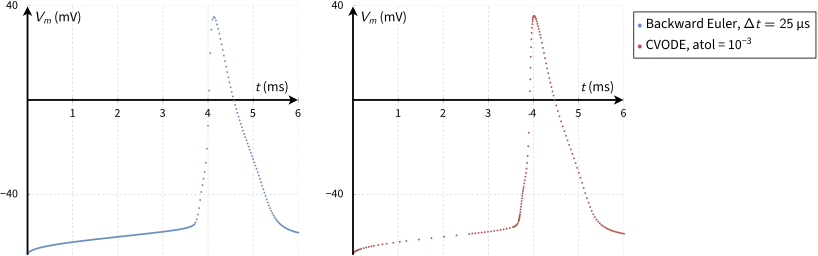
Note the difference in the placement of the steps: at equidistant intervals in the Backward Euler use case, and adapting to the solution gradient in the variable step counterpart. CVODE takes 30% fewer steps: long ones where the voltage rises slowly before the spike, and short ones on its rising phase and around its peak.
A current injection at the soma forces the neuron to spike at a rate that increases with the injected current. A simple test consists in enforcing different spiking rates and measuring the number of integration steps of both methods:
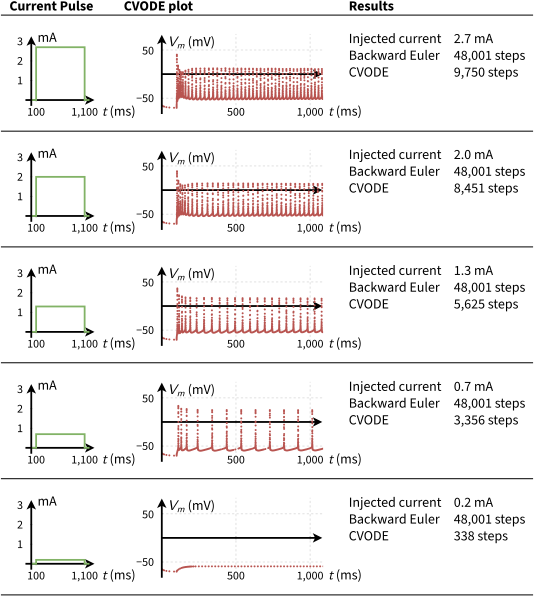
The picture above shows that Backward Euler performs the same number of steps for every current, while the step count of CVODE is much lower and grows with the spiking rate. The fixed step also sets the fastest reaction time of Backward Euler: a large step slows down the dynamics of the neuron, so that each spike comes a little late, and the delay adds up from one spike to the next. This shift of the voltage trajectory, a phase shift, is displayed below over 100 ms of simulation, for Backward Euler with three step sizes (top) and CVODE with four tolerances (bottom). Backward Euler with \(\Delta t = 1\) μs and CVODE with \(\text{atol} = 10^{-4}\) are taken as reference solutions:
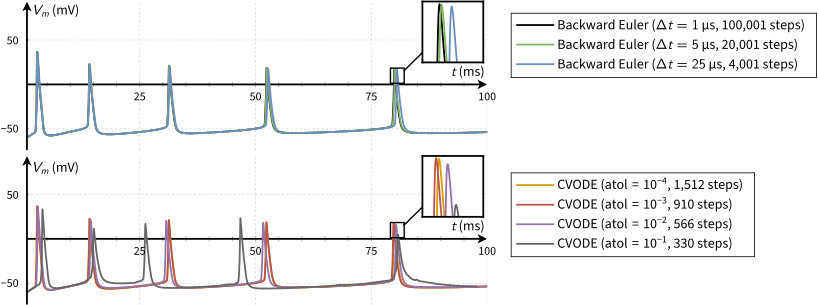
The tolerance \(\text{atol} = 10^{-2}\) approximates the accuracy of Backward Euler with the default step of 25 μs, with 7 times fewer steps, and \(\text{atol} = 10^{-3}\) that of the 5 μs step, with 22 times fewer steps. A looser tolerance takes fewer steps still, but its spikes drift far from those of the reference.
After a second of simulation, the spike time phase-shifting of Backward Euler is substantial (about 2 ms for \(\Delta t = 5\) μs and 6.5 ms for \(\Delta t = 25\) μs), demonstrating the gain in using variable step methods for this use case. The voltage trajectories over one second are displayed below, with a zoom on the last spike:
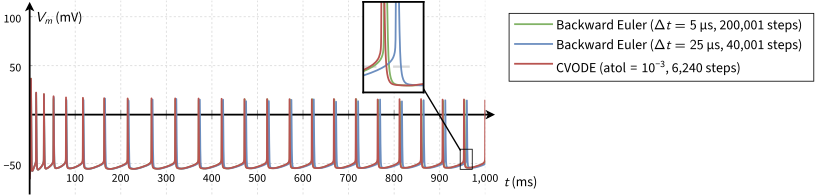
Over the whole second, CVODE takes 6 times fewer steps than Backward Euler with \(\Delta t = 25\) μs and 32 times fewer than with \(\Delta t = 5\) μs, and its last spike is close to that of the 5 μs step.
To study whether these advantages hold in practice, the simulation runtime of both methods is measured. The first test measures the impact of the spiking rate in terms of simulation steps and time to solution on an Intel i5 at 1.6 GHz. The different current values are injected as a proportion of the action potential threshold current, i.e. the minimum current that must be continuously injected for the neuron to spike. The results are displayed below, with the step count (left) and the runtime (middle) of both methods, for a current injected during the whole second of simulation (right):
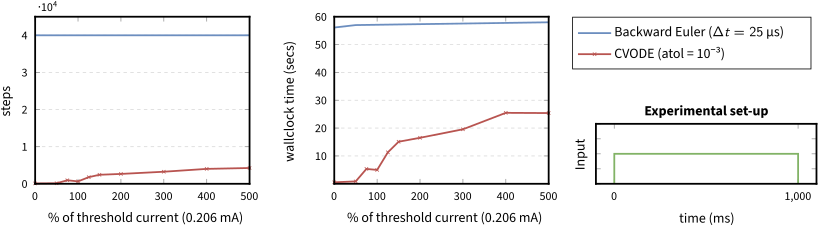
Results look promising: even at an extremely high current value, the speed-up is significant. CVODE runs about 100 times faster than Backward Euler when the neuron does not spike, 12 times faster at the threshold current, and 2.5 times faster at 500% of it. The runtime gains are smaller than the step gains, as a step of CVODE, with its Newton iterations and error estimation, costs more than a step of Backward Euler.
A second test enforces discontinuities and resets of the IVP by artificially injecting current pulses of 1 μs at given frequencies. The picture below shows the same measures for pulse frequencies from 10 Hz to 10 kHz and five pulse amplitudes:
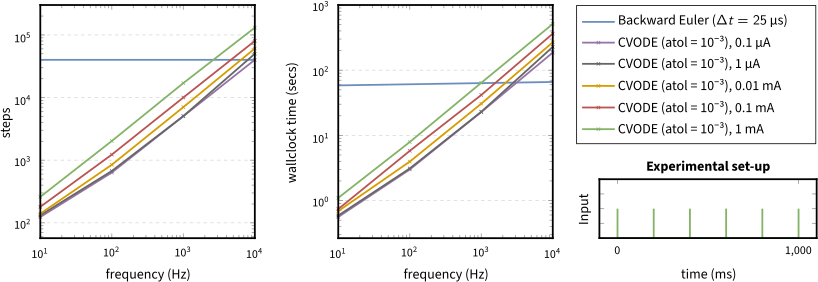
In this scenario, the runtime shows a high dependency on the number of discontinuities, as each pulse restarts the integration, and a minor dependency on the discontinuity value (i.e. the amount of current injected). CVODE runs 50 to 100 times faster than Backward Euler at 10 pulses per second, and stays faster up to about 1,000 to 3,000 pulses per second. The holy grail is then: how does this apply to networks of neurons?
Simulation of a network of homogeneous neurons
The performance of lvardt’s integration model was tested (Lytton and Hines 2005) on a connected homogeneous network of 100 inhibitory neurons on a single compute node. Due to their inhibitory features, the circuit presents rapid synchronization through mutual inhibition, where variable time step integrators are likely to encounter problems: the near-simultaneous spiking of all neurons fills the queue with events. A fixed time step of \(\Delta t = 2.5\) μs yielded closely comparable results to those of lvardt with an atol of \(10^{-3}\) or \(10^{-5}\).
The event deliveries and the associated interpolations took about \(12\%\) of the total execution time. When using global variable time stepping instead, the authors report that the large number of events leads to an increase in execution time of up to 60-fold.
The following picture presents the aforementioned results for the comparison of fixed and variable time step methods for the mutual-inhibition model. Execution time grows linearly with simulation time for the fixed-step integration (dashed lines, \(\Delta t = 2.5\) μs and 25 μs). Variable-step methods (solid lines, lvardt with \(\text{atol} = 10^{-5}\) and \(10^{-3}\)) show a reduction in CPU load at the onset of synchrony.
The rationale behind the non-linearity of adaptive time stepping is that lvardt produces time steps that jump around during the initial presynchrony phase of the simulation (fast uprising phase). It then slowly stabilizes to an alternation between large steps in the long intervals separating the population spikes and extremely short time steps during the population spike itself:
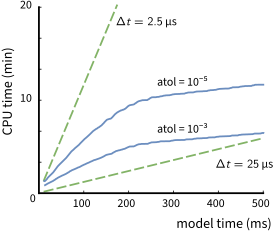
Adapted from: Lytton and Hines (2005), Fig. 3A
Another experiment featured a thalamocortical simulation with four cell types (cortical pyramidal neurons and interneurons, thalamocortical cells, and thalamic reticular neurons). The two thalamic cell types produced bursts with prolonged interburst intervals, which makes them very suitable for the lvardt algorithm. A simulation of 150 ms at high precision, with an atol of \(10^{-6}\) for lvardt and \(\Delta t = 10^{-4}\) ms for the fixed time step, took 6 minutes 13 seconds and 10 hours 20 minutes, respectively, a 100-fold speed-up. For a standard-precision run, with an atol of \(10^{-3}\) and \(\Delta t = 10^{-2}\) ms, the simulations took 2 minutes for lvardt and 5 minutes 53 seconds for the fixed time step, a 3-fold speed-up. The gain grows with the precision, as the fixed step method shortens every step, while lvardt shortens its steps only where the solution varies fast.
Simulation of a network of heterogeneous neurons
Although networks of similarly behaving neurons give an estimation of the achievable speed-up when using fixed and variable time step methods, it is a rough one. In practice, brain activity differs widely across space and time.
To measure the efficiency across the different spiking dynamics of neurons, the digital reconstruction of a laboratory experiment that the Blue Brain Project published in the journal Cell was reproduced. The reproduction simulates 7.5 seconds of electrical activity, performing a fixed-step simulation of the spontaneous activity of 219,247 neurons during tonic depolarization.
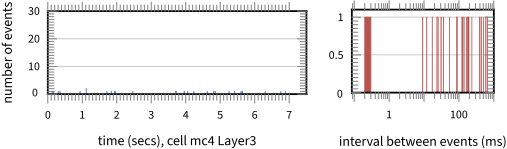
Two sample neurons are taken from the top 1% busiest neurons, in terms of incoming spikes, i.e. discontinuities. For each neuron, the pictures below display the number of spikes arriving per time interval (left, each time bin accounts for 10 ms) and the distribution of time intervals between spike arrivals (right):
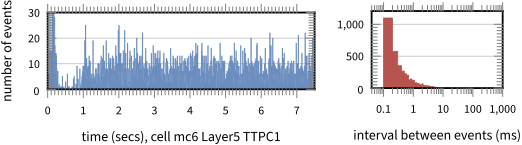
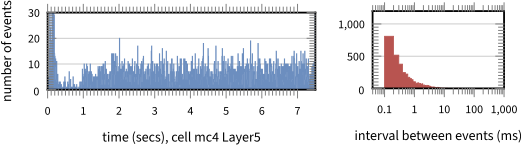
The number of spikes received in that top 1% was between 3,040 and 6,146 events, i.e. 405 to 820 per second. Nearly all intervals between two arrivals are shorter than 10 ms, and most are shorter than 1 ms (right): these neurons have no long period of silence in which CVODE could take long steps. The same analysis is redone for two sample neurons collected from the median 1% of neurons in terms of spike arrivals:
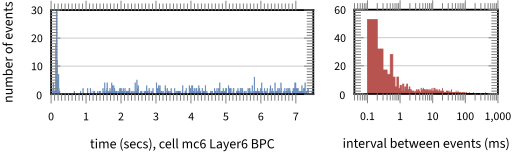
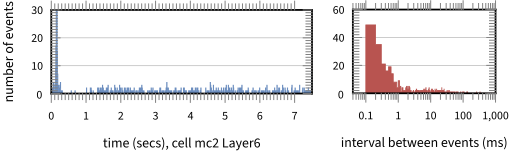
The neurons of the median 1% received 541 to 558 spiking events (72 to 74 per second). Most of their intervals are also shorter than 1 ms, as spikes arrive in groups, but some last from 10 ms to a few hundred milliseconds. And the bottom 1%:
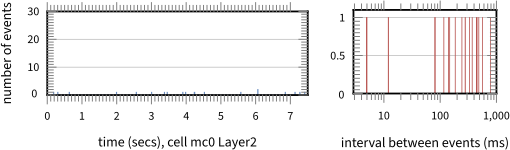
with fewer than 100 events, i.e. fewer than 13 per second, mostly separated by intervals of tens to hundreds of milliseconds.
The total number of events received across all neurons in the network was approximately 155 million, i.e. a mean of 707 incoming spikes per neuron. With one integrator per neuron, as in lvardt, each integrator restarts on average about every 10 ms, while a single integrator for the whole network would restart hundreds of times within each fixed step of 25 μs.
In practice, this means that most brain regions (or activity patterns) fall within the interval of acceleration measured on a single neuron: even the busiest 1% of the neurons receive fewer events per second than the pulses at which CVODE stops being faster. The pulses of that test arrived at regular intervals, unlike the spikes of a network, but they give an estimate of the number of events that CVODE can afford.
Is the theoretical speed-up guaranteed to hold in practice? Two main issues arise.
1. Distributed CVODE executions
Simulations of such scale require parallel/distributed computing due to the memory/computation requirements: the network above needs terabytes of memory for its states, and more for the BDF, which keeps the states of the previous steps.
However, in parallel computing environments, the synchronization of cells spread across different compute nodes presents a bottleneck, due to the required step synchronization between neurons. In practice, neurons held on different compute nodes have to be able to communicate their time instant. This way, when they spike, the synaptic current is delivered to a second neuron that has not advanced beyond the delivery time (or the spike would be missed).
To tackle this issue, the simulation is split into equidistant time intervals equal to the shortest delay of any global event (typically the minimal synaptic delay, or, when applicable, the update interval of extra-cellular mechanisms or gap junctions). A spike emitted within an interval reaches its targets no earlier than the next interval, so at every time interval, all the nodes in the network perform a collective communication call and share the events (spikes) to be sent in the next time frame. In the network above, the shortest synaptic delay is 0.1 ms, so the compute nodes synchronize once every 4 fixed steps of 25 μs. This approach, the bulk synchronous parallel (BSP) execution model, has previously been shown (Lytton and Hines 2005) to provide a good speed-up. It then guarantees:
- Asynchronous computation: every core in every compute node computes its dataset (neurons) independently, and advances the neurons up to the time limit of the next synchronization interval;
- Asynchronous communication: synaptic activity can be transmitted immediately after it occurs, or together with the synchronization information in an all-to-all communication;
- Synchronization at a barrier: neuron integration and spike communication for a stepping time window must be completed on all compute nodes before the computation and communication for the next window start.
However, going to the extreme of the possible optimization, this collective synchronization of neurons has three main downsides:
- no compute node can ever perform a CVODE timestep that exceeds the limits of the current time frame, i.e. 0.1 ms in the network above, while quiet neurons can take steps of more than 1 ms;
- all compute nodes must wait for the slowest one to reach the end of the time frame;
- all compute nodes restart CVODE at the initial instant of every time frame.
A solution to this problem is the fully-asynchronous parallel (FAP) execution model of the original publication, which makes the communication, the computation and the synchronization asynchronous. Its main concept is:
- Each neuron keeps a map of all its pre-synaptic dependencies, i.e. those neurons whose axons connect to its synapses, or in practice, those which may spike and deliver current into the neuron;
- This map is actively updated by small stepping notifications from the pre-synaptic dependencies;
- Each neuron keeps a map of all its post-synaptic dependencies, i.e. those whose dendrites connect to its axon terminal, or in practice, those which receive current from the neuron when it spikes;
- In addition to the spike communication, at a regular interval, the neuron must inform its dependencies that it stepped, or advanced in time;
- Collective synchronization barriers are removed. Instead, neurons advance in time as much as possible, taking into account their pre-synaptic dependencies, i.e. they advance up to the timestep that guarantees no missed event if any pre-synaptic dependency spikes.
In practice, a neuron \(i\) can advance up to the time:
\[t_i^{\max} = \min_j \left( t_j + d_{ji} \right)\]where the minimum is taken over its pre-synaptic neurons \(j\), \(t_j\) is the last time notified by neuron \(j\), and \(d_{ji}\) is the shortest synaptic delay from \(j\) to \(i\): a spike of neuron \(j\), emitted at \(t_j\) or later, cannot arrive at neuron \(i\) before \(t_j + d_{ji}\). Where BSP stops every neuron at the shortest delay of the whole network, each neuron is limited here only by its own pre-synaptic neurons and their delays. The notifications between two neurons are sent at an interval set for each pair, from 0.1 ms to several milliseconds. A scheduler on each compute node always integrates next the neuron that is the earliest in time, as it is the one that holds back the others, which maximizes the length of the steps.
This approach increases computational efficiency, as neurons can be stepped beyond the synchronization intervals of the other approaches, and perform more integration steps in a row, staying longer in the more efficient CPU cache levels.
In the terms of parallel discrete event simulation (PDES), FAP is a conservative synchronization: each neuron only integrates up to the earliest time at which a spike from another neuron could still arrive, so that nothing is ever undone. The synaptic delay \(d_{ji}\) is the lookahead of the link from neuron \(j\) to neuron \(i\). The stepping notifications are the null messages of the Chandy–Misra–Bryant algorithm: messages that carry no event, only a lower bound on the time of the next one. They let the receivers advance, and avoid a deadlock, a cycle of neurons that wait for each other forever.
The alternative, optimistic synchronization (the Time Warp algorithm of Jefferson), lets each process advance speculatively, and rolls it back when an event arrives in its past, as the back-interpolation of lvardt does within the last step of a cell. On distributed executions, the preprint found speculative stepping infeasible: a rollback may have to revert spikes already sent to other compute nodes, which leads to a cascade of reversals across neurons and much more communication.
2. Testing conditions alter spike rates
Even though results sound promising, different mammals, brain regions and mental states can easily change the simulation conditions, leading to very different spiking rates. So the final test is to understand how these factors alter the simulation efficiency. To that end, the fully-asynchronous execution model was applied and tested on five different brain dynamics, listed below with the share of the neurons of the simulated laboratory experiment in each of them:
| Dynamics | Spiking rate | Neurons | Representative of |
|---|---|---|---|
| quiet | 0.25 Hz | 31.43% | neurons almost at rest and/or with little activity; an upper bound of the runtime of circa 90% of neurons in the brain during regular activity |
| slow | 1.5 Hz | 38.44% | the lower bound of active neurons |
| moderate | 6.5 Hz | 27.02% | the irregular regime of slow oscillations of the Brunel network (SI slow); an upper limit to the spiking rate of the rat frontal cortex; a loose approximation of the visual cortex of cats |
| fast | 38 Hz | 3.10% | the cortical and thalamic neuronal activity during periods of high vigilance; the asynchronous irregular regime (AI) of the theoretical inhibition-dominated model of the Brunel network |
| burst | 55.8 Hz | 0.01% | typically a by-product of depolarizing current injections; the fast-spiking regime of the inhibition-dominated irregular dynamics of the Brunel network (SI fast) |
The shares were measured on the central minicolumn (31,346 neurons) of the network, between 2 and 4 s of simulation. Note that only 31.43% of these neurons are quiet, far from the 90% of the brain: the preprint attributes the difference to the small size of the simulated network.
The benchmark of the preprint tested several fixed- and variable-step integration methods: the methods 1a to 1c solve simple neuron models, and the methods 2a to 2c complex ones. The fixed step methods take steps of \(\Delta t = 25\) μs, and the variable step methods use an atol of \(10^{-3}\):
| Method | Neuron models | Solver | Time step | Execution model |
|---|---|---|---|---|
| 1a | simple | cnexp of NEURON: currents and states as linear equations, with an analytical solution of the ODE of each state |
fixed | BSP |
| 1b | simple | Euler of NEURON: as 1a, with an explicit Euler step for the states, cheaper as it needs no exponential or division | fixed | BSP |
| 1c | simple | the Euler method of 1b | fixed | FAP |
| 2a | complex | derivimplicit of NEURON: currents as a linear equation, and an implicit solution of the states of each mechanism, but not of the correlated states of different mechanisms (the † of the legend) |
fixed | BSP |
| 2b | complex | CVODE | variable | BSP |
| 2c | complex | CVODE, in three variants: each event delivered at its exact time, or event grouping (EG) within \(\Delta t / 2\) or \(\Delta t\) | variable | FAP |
Event grouping delivers at once all the events that arrive within an interval of \(\Delta t / 2\) or \(\Delta t\). Their delivery times lose precision, down to that of the fixed step methods, while the integration between them keeps the accuracy of the variable order and the variable step, with far fewer resets of the IVP.
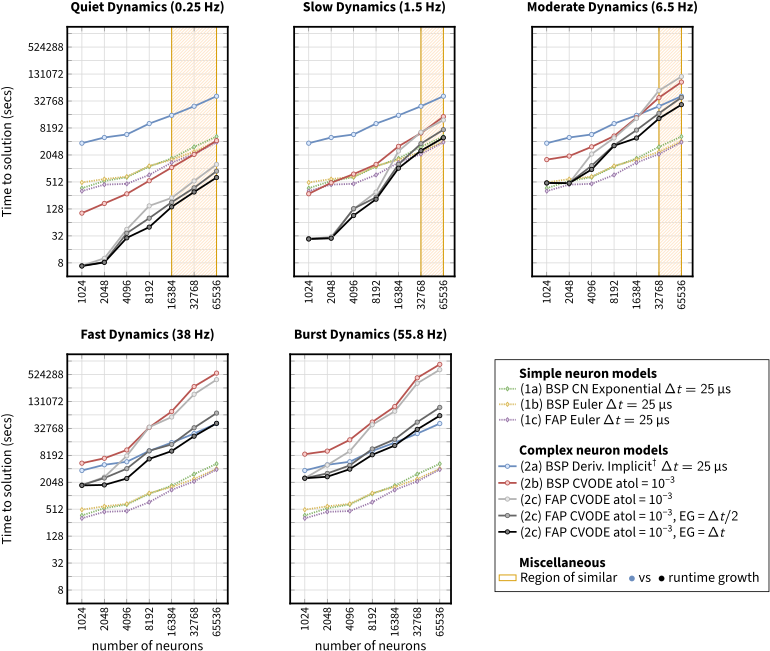
The benchmark ran on 64 Cray XE6 compute nodes, each with a 16-core AMD Opteron 6380 at 2.5 GHz and 64 GB of memory. Each regime was obtained with a constant current injected into all neurons, strong enough to bring the network to its spiking rate. The benchmark results are displayed next, with the time to solution of each method for one second of simulation, on networks of 1,024 to 65,536 neurons, in each of the five regimes (the runtimes of the moderate, fast and burst regimes are extrapolated from 250, 100 and 100 ms of simulation):
Quoting the preprint:
Fixed step methods do not yield significantly-different execution times across different spiking regimes. This is due to the homogeneous computation of neuron state updates throughout time, and the light computation attached to synaptic events and collective communication not yielding a substantial increase of runtime. The difference in execution times measured across the five regimes was of about \(2\%\), which we consider negligible.
On the other hand, as expected, variable step executions are penalized on regimes with high discontinuity rates. It is noticeable that the runtimes of fixed- and variable-step solvers approximate as we increase the spiking rate, i.e. the increase of runtimes with the input size is steeper for variable timestep (2b\(\hspace{0.3mm}{\color{#b85450}\bullet}\) and 2c\(\hspace{0.3mm}{\color{black}\bullet}{\color{#666666}\bullet}{\color{#b3b3b3}\bullet}\)) compared to fixed timestep methods (2a\(\hspace{0.3mm}{\color{#6c8ebf}\bullet}\)). This is due to discontinuities in variable-step being delivered throughout a continuous time line, compared to the discrete delivery instants of the fixed-step methods — therefore increase the number of interpolation steps; and the iterative model of the variable timestep reinitializing the state computation with small step sizes on each IVP reset, compared to the constant-sized step of fixed step methods.
A remarkable performance is visible on the quiet dynamics use case, where our fully-implicit ODE solver of complex models (with Newton iterations), still runs faster than the simple solver resolving only a system of linear equations. The underlying rationale is that — despite the inherent computation cost of Newton iterations in the variable step methods — the low level of discontinuities allow for very long steps, that surpass the simulation throughput of simple solvers running on fixed step methods.
The speed-up of the variable step method 2c, with event grouping within \(\Delta t\), over the fixed step method 2a for complex models is 544 to 65 in the quiet regime, on 1,024 to 65,536 neurons, and 7.7 to 1.8 in the moderate one. In the fast regime, 2c runs twice as fast as 2a on 1,024 neurons and as fast on 65,536, and in the burst regime, 1.5 times faster on 1,024 neurons and 1.5 times slower on 65,536.
In practice, the gain of the variable step methods is lost on large networks in the fast and burst regimes, where the fixed step methods are as fast or faster. Also, the benchmark shows that the FAP execution model is faster than BSP mainly on small networks: as a network grows, each neuron has more pre-synaptic neurons, so its stepping interval shrinks towards the BSP communication interval.
The preprint also gives an Overall Runtime Speed-up Estimation of 228.5–24.6× on 1,024 to 65,536 neurons for 2c with event grouping within \(\Delta t\) (224.5–11.9× with an exact delivery of the events). It is the mean of the per-regime speed-ups, weighted by the distribution of neurons per spiking regime in the simulation of the laboratory experiment above.
However, as the runtime of a mixed network is the sum of the runtimes of its parts, its speed-up is the weighted harmonic mean of the per-regime speed-ups, which the slowest parts dominate. The moderate regime alone, with 27.02% of the neurons and speed-ups of 7.7 and 1.8, keeps the speed-up under 28.5 on 1,024 neurons and 6.7 on 65,536 neurons.