Learning from sequences: Encoder-Decoder, RNNs, Transformers and BERT
A sentence is a sequence of words, and the meaning of each word depends on the others. A recurrent neural network (RNN) reads the words one at a time, in order. Attention relates all the words to each other at once, which trains faster on parallel hardware. The following sections introduce three models: the Encoder-Decoder, built from RNNs; the Transformer, built on attention; and BERT, a stack of Transformer encoders.
Encoder-Decoder and Sequence-to-Sequence
The Encoder-Decoder (original paper Sequence to Sequence Learning with Neural Networks) is a model that learns an encoding and a decoding task applied to two sequences, i.e. it trains for a sequence-to-sequence task such as the translation of a sentence from a source language to a target language. It runs in two phases, the encoder and the decoder, and each phase is a sequence of iterations over an RNN.
The structure of its RNN is as follows:
- Words are passed as input, each represented by an embedding of size \(d\);
- The neurons are not stateless, as a regular neuron with an activation function is, but have an internal state. Two common examples are Long Short-Term Memory (LSTM) and Gated Recurrent Units (GRU). The states of the neurons of a layer form its hidden state. GRU is the usual choice: it has one state variable per neuron instead of two, and three weight matrices instead of four, so it is faster to train;
- The network has three fully connected layers:
- an input layer of size \(d_h+d\), the concatenation of the hidden state of the previous iteration and the embedding of the current word. On the first iteration, the previous hidden state is a zero or a random vector;
- a hidden layer of size \(d_h\), the hidden state of the current iteration;
- an output layer of the size of the vocabulary, whose softmax gives the probability of each word being the predicted word.
This structure is represented by the following picture:
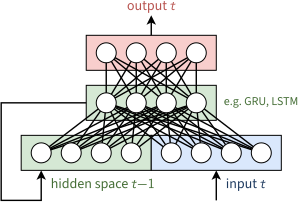
The recurrent neural network trained at each step of the encoder-decoder architecture. Its input layer is the concatenation of the hidden layer of the previous iteration (green) and the embedding of the current input word (blue). The hidden layer (green) holds the states of the GRU or LSTM neurons, and the output layer (red) holds the model output.
The training consists of an encoding and a decoding phase:
- During encoding, the RNN reads the words of the input sentence one at a time, and passes the hidden state of each iteration as input to the next one. The output of the RNN is discarded, as only the hidden states are needed. After the last word, the hidden state is passed to the first iteration of the decoder;
- The decoder is a second RNN with the same structure. Its first step takes the last hidden state of the encoder and the Beginning of Sentence (BOS) token, a special word of the vocabulary, and outputs the first word of the translation. Each following step takes the hidden state of the previous step and the previous word of the translation. In training, this word is the ground-truth word, not the predicted one, a method called teacher forcing, so that an early wrong word does not derail the rest of the sentence. The last output is the End of Sentence (EOS) token. Both RNNs are trained together on the loss of all outputs, as one deep network unrolled over the iterations.
This algorithm is illustrated below, where the thick arrow passes the last hidden state of the encoder to the decoder:
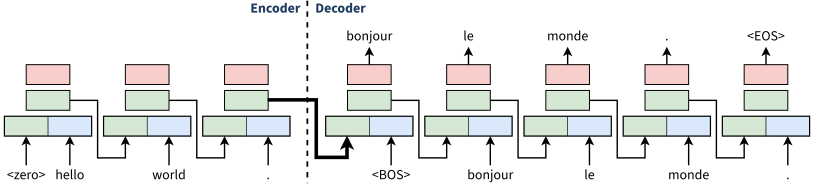
Once the network is trained, a new sentence is translated by running decoder iterations until the EOS token is output. Each iteration then takes as input the word predicted by the previous one.
Note that accurate results for long sentences are hard to obtain: the decoder sees the input sentence only through the last hidden state of the encoder, and information tends to get lost after many iterations. Also, acceleration and scaling are limited, as recurrent iterations cannot run in parallel: each iteration depends on the output of the previous one. The only option is then to parallelize the model itself, across its parameters and activations, which gives no speedup on small models.
An improvement based on an attention mechanism addresses the first limit (original paper: Neural Machine Translation by Jointly Learning to Align and Translate). It uses the hidden states of all encoder iterations, not only the last one, so that each decoding step can look back at the input words it needs. However, attention does not remove the second limit, as both RNNs still run one iteration per word.
Transformer
In 2017, researchers at Google introduced the Transformer (original paper Attention is all you need), overcoming many of the previous issues while demonstrating better results. Its encoder reads all the words of a sentence at once, and its attention relates each word to every other word in a single step. The transformer architecture is the following:
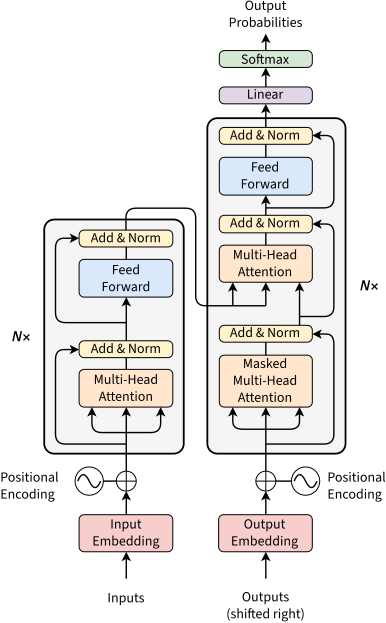
The transformer architecture. Grey regions represent one encoder layer (left) and one decoder layer (right), each repeated N times. Adapted from: Attention is all you need (2017, Google, arXiv)
The left and right components are the encoder and the decoder, respectively. Each encoder layer holds a multi-head attention and a feed forward block. Each decoder layer holds a masked multi-head attention, a multi-head attention over the output of the encoder, and a feed forward block. In the paper, both stacks have \(N=6\) layers. The next sections describe these components, and omit the implementation details to focus on computational complexity.
Word and Positional Embedding
The first unit of importance in the transformer is the embedding unit combined with the positional encoding (the red boxes and the circles above them in the previous picture). The transformer has no recurrence or convolution, so a positional encoder is needed to learn the context of a sequence from the order of its words. Without it, the model sees the input as a set of words, not as a sequence: the word dog would get the same output in “dog bites man” and in “man bites dog”. According to the paper, the positional encoding of a word at position \(pos\) of a sentence, at each dimension of an embedding of size \(d\), is:
- \(PE_{(pos,2i)} = \sin\left(\frac{pos}{10000^{2i/d}}\right)\) for an even dimension \(2i\), and
- \(PE_{(pos,2i+1)} = \cos\left(\frac{pos}{10000^{2i/d}}\right)\) otherwise.
In practice, the positional encoding is given by sine and cosine waves, with a different frequency for each pair of dimensions. The frequency decreases with the dimension: the first pair of dimensions repeats every few positions, and the last one only after tens of thousands. Like the hands of a clock, each turning at its own speed, the pairs together give each position a different pattern. The authors chose these functions because the encoding of a position shifted by a fixed offset is a rotation, i.e. a linear function, of the encoding of the position, so the model may learn to attend by relative positions. Learned positional embeddings gave nearly identical results (Section 3.5 in the paper).
Attention Mechanism
The main component of the transformer is the attention mechanism, which determines how the words in the input and output sentences interact. In brief, it is the component that learns the relationship between words, i.e. the relevant bits of information in each context (hence the name attention). The transformer runs several of these mechanisms in parallel, to learn several relevant aspects of the input. This Multi-head Attention Mechanism answers, for each of its \(h\) heads, What part of the input should this head focus on?
Consider a single attention head for now. Take a sentence of \(n\) words: how is each word related to every other word in that sentence? A single attention head computes the \(n \times n\) matrix of these inter-word importance metrics. Here is an example:
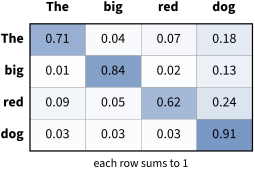
Attention weights of one attention head for the sentence “The big red dog”, of length \(n=4\). Each row holds the softmax-normalized relevance of that word to every word of the sentence, itself included, and sums to 1.
The scores of the picture come from three vectors that each word computes from its embedding: a query, a key and a value. Think of the query as the question that a word asks of the sentence, the key as the description that each word offers to answer it, and the value as the information that a word passes on. The score of a pair of words is high when the query of the first word matches the key of the second, i.e. when their dot product is large. The new representation of a word is then the sum of the values of all words, weighted by its row of scores.
How does this mechanism work? According to the paper, each attention head computes a scaled dot-product attention, formulated as:
\[Attention(K, V, Q) = A \, V = softmax\left( \frac{QK^T}{\sqrt{D^{QK}}} \right) V\]Where:
- \(Q\) is a tensor of queries of size \(N^Q×D^{QK}\)
- \(K\) is a tensor of keys of size \(N^{KV}×D^{QK}\), and
- \(V\) is a tensor of values of size \(N^{KV}×D^V\), thus
- \(Attention(K,V,Q)\) is of dimension \(N^Q×D^V\).
Finally, the multi-head attention mechanism combines all attention heads, and is defined as:
\[MHA(K, V, Q) = [head_1, ..., head_h]W^{MHA} \,\text{ and }\, head_i = Attention(KW^K_i, VW^V_i, QW^Q_i)\]I.e. it is a concatenation of all attention heads, and the parameters learned are the weights of the key (\(W^K_i\)), value (\(W^V_i\)) and query (\(W^Q_i\)) projections of each head \(i\), and a final transformation \(W^{MHA}\) of the concatenation. Each head has a size of \(d/h\), so that all heads together cost about as much as a single head of the full size \(d\) (Section 3.2.2 in the paper). In terms of computational complexity, the attention of the encoder processes the complete input sequence at once, instead of looping through its words. Therefore, the attention mechanism replaces the recurrent (RNN) iterations of an encoder with a set of matrix-matrix multiplications.
The Masked Multi-head Attention of the decoder is similar to the regular one, but hides the next words from the model (a causal mask): the dot products of the upper triangle of the attention matrix are set to \(-\infty\) before the softmax, which gives them a weight of zero. Decoding is performed one word of the output sentence at a time, and each word attends only to itself and to the words before it. In training, the whole target sentence is known, so the mask lets the decoder compute all iterations at once. Applied to “Le gros chien rouge”, the French translation of “The big red dog”, the four iterations are:
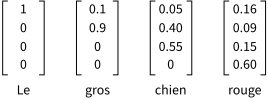
Stacked as rows, the four vectors of the picture form an attention matrix whose upper triangle is zero.
Computational Complexity
Besides the great reduction in the number of iterations on the encoder side, the authors compare the computational complexity of four layer types:
| Layer Type | Prefill / Training (per Layer) | Decode (per Layer and Token) | Sequential Operations | Maximum Path Length |
|---|---|---|---|---|
| Self-Attention | \(O(n^2 \cdot d)\) | \(O(n \cdot d)\) | \(O(1)\) | \(O(1)\) |
| Recurrent | \(O(n \cdot d^2)\) | \(O(d^2)\) | \(O(n)\) | \(O(n)\) |
| Convolutional | \(O(k \cdot n \cdot d^2)\) | \(O(k \cdot d^2)\) | \(O(1)\) | \(O(\log_k(n))\) |
| Self-Attention (restricted) | \(O(r \cdot n \cdot d)\) | \(O(r \cdot d)\) | \(O(1)\) | \(O(n/r)\) |
Computational complexity of four different learning models. Key: \(n\): sequence length, \(d\): representation dim., \(k\): kernel size, \(r\): size of neighbourhood.
For the RNN of the encoder-decoder, each of the \(n\) words of a sentence takes in the order of \(d^2\) multiplications (the weights of a fully connected layer), therefore \(O(n d^2)\). In self-attention, the attention matrix holds \(n^2\) dot products of vectors of size \(d\), and the weighted sum of the values takes as many operations, therefore \(O(n^2 d)\). In decode, each new word is computed on its own: its query attends to the keys and values cached for the \(n\) previous words (the KV cache), therefore \(O(n d)\) per word, while a recurrent layer only updates its hidden state, in \(O(d^2)\), and keeps no cache.
The claim is that \(O(n^2 d)\) is better than \(O(n d^2)\). This sounds illogical in most machine learning problems, as the input size is typically much larger than the embedding size. However, \(n\) here is the number of words in a sentence, usually tens, and \(d\) is the size of the embedding, usually hundreds. Thus, self-attention needs fewer operations than recurrence on most sentences, and more on long documents (Section 4 in the paper). Note that the table counts the attention only: the projections of the queries, keys and values, and the feed forward block, add \(O(n d^2)\) operations to each layer, as the weights of a recurrent layer do.
The last two columns of the table explain the gain in parallelism. Self-attention connects all words with a constant number of sequential operations, while a recurrent layer needs one sequential step per word. The constant path length between any two words also makes long-range dependencies easier to learn. For very long sequences, the restricted self-attention (last row), where each word attends only to its neighborhood, reduces the complexity, at the cost of longer paths between distant words. Sparse Transformers keep the paths short: each word attends to the last \(\sqrt{n}\) words and to every \(\sqrt{n}\)-th word before them, in \(O(n \sqrt{n} \cdot d)\) operations. LongNet attends to fewer words as the distance grows, in \(O(n \cdot d)\).
BERT: Bidirectional Encoder Representations from Transformers
Going back to the previous section, the main rationale of the Transformer’s Encoder-Decoder is that:
- The encoder learns the context of the input language (English in the previous example);
- The decoder learns the task of mapping the input to the output language (the English-to-French translation).
So, the encoder is trained efficiently and learns a context. The main question is then “Can the context of the encoder alone be used to learn complex tasks?”. This led to the BERT model (original paper BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding).
BERT is a stack of Transformer encoders that learns language contexts and performs interpretation tasks. As the encoder has no mask, the context of each word is learned from the words before and after it (hence Bidirectional). The following picture illustrates the model, where each block is one encoder layer of the transformer:
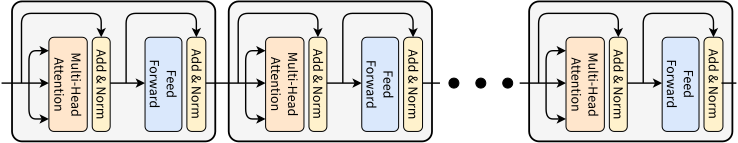
The training is performed in two phases: a pre-training phase learns the contexts of the language, and a fine-tuning phase adapts the trained model to the task being solved.
Pre-training
The pre-training solves two self-supervised prediction tasks at the same time:
- Masked language model: given a sentence with some words replaced by a flag (masked), the model is trained to predict the masked words. The paper masks 15% of the words, and sometimes keeps the word or replaces it by a random word instead of the flag, as the flag never appears in the fine-tuning;
- Next sentence prediction: given two sentences, the model is trained to guess whether the second sentence follows the first, which is the case for half of the pairs.
Here are two training examples:
Input = [CLS] the man went to [MASK] store [SEP] He bought a gallon [MASK] milk [SEP]
Output = [IsNext] the man went to the store [SEP] He bought a gallon of milk [SEP]

Input = [CLS] the man [MASK] to the store [SEP] penguins [MASK] to jump [SEP]
Output = [NotNext] the man went to the store [SEP] penguins like to jump [SEP]
The examples use three special tokens: [CLS] (classification) starts every input, [SEP] (separator) ends each sentence, and [MASK] is the flag of a masked word. The IsNext or NotNext label of the second task is predicted from the output at the position of [CLS], shown as the first word of the output. The layout of the input data is:
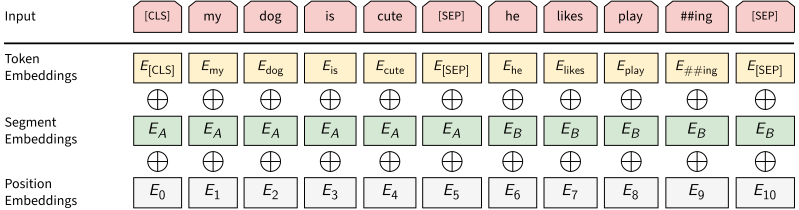
Input of the BERT model. Position embeddings are learned, one vector per position (up to 512), unlike the fixed sine and cosine encoding of the transformer described above. Segment embeddings flag each word as part of the first or second sentence. Token embeddings are the text embeddings of the input data. The input to the model is the sum of these three embeddings. Adapted from: BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Note that the word playing is split into play and ##ing: BERT splits rare words into frequent pieces (WordPiece tokens), where ## marks a piece that continues a word.
As a side note, the authors trained this model on BooksCorpus and English Wikipedia, in two sizes: BERT-base, with 12 encoder layers, and BERT-large, with 24. As attention is quadratic in the sequence length, most training steps use short sequences, and only the last steps use the full length.
Fine-tuning
The fine-tuning phase adds an extra layer to the pre-trained BERT model, to train it for the task at hand. This approach, known as transfer learning, has been applied previously in other models, particularly in convolutional neural networks. There, the first layers are pre-trained and learn edges and lines, and the remaining layers are added later and trained for the object-specific detection. Fine-tuning is much cheaper than the pre-training, and every task starts from the same pre-trained model.
In the original paper, the authors applied this model to four families of tasks:
- Sentence Pair Classification: classifies a pair of sentences, e.g. do they agree or disagree, does the second one follow the first, do they describe a similar context. As in the pre-training, the label is predicted from the output at the position of [CLS] (\(C\) in the picture below);
- Single Sentence Classification: similar to the previous, but applied to a single sentence, e.g. to detect hate speech or the sentiment of a movie review;
- Question Answering: the input is a question followed by a paragraph that holds the answer. For each word of the paragraph, the model predicts the probability that the answer starts or ends there, from the output of the word (\(T_i'\) in the picture below). As an example, with the predicted answer between markers:
- input: “[CLS] How old is John [SEP] His name is John. John is a Swiss carpenter and he is 23 years old”;
- output: “[CLS] How old is John [SEP] His name is John. John is a Swiss carpenter and he is ###23### years old”;
- Single Sentence Tagging: predicts the class of each word (name, location, job, etc.) from its output (\(T_i\) in the picture below), as in named-entity recognition. The picture writes the classes in the IOB format, where B-PER marks the first word of the name of a person and O a word outside any name. As an example, with the class of each word in its place:
- input: “[CLS] His name is John. John is a Swiss carpenter and he is 23 years old”;
- output: “[CLS] His name is [NAME]. [NAME] is a [NATIONALITY] [OCCUPATION] and he is [AGE] years old”.
The inputs and outputs of the fine-tuning for these tasks are illustrated in the following picture:
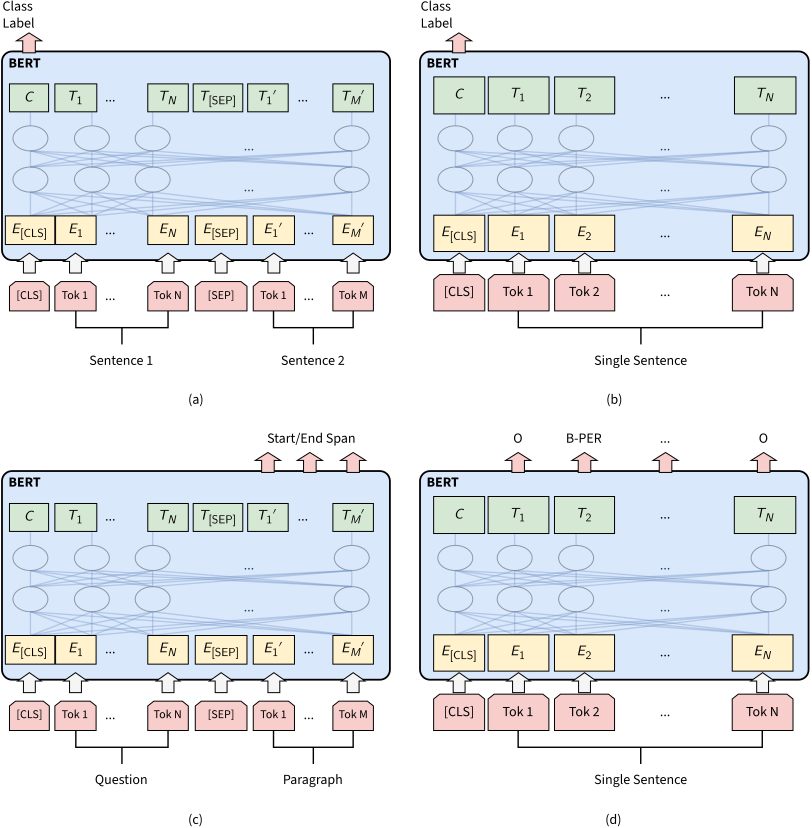
Input and output of the fine-tuning phase of a BERT network, applied to four types of tasks: (a) sentence pair classification (MNLI, QQP, QNLI, STS-B, MRPC, RTE, SWAG), (b) single sentence classification (SST-2, CoLA), (c) question answering (SQuAD v1.1) and (d) single sentence tagging (CoNLL-2003 NER). Adapted from: BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding